Google announced Gemini 4 Argon on September 30, 2026, the first model of the Gemini 4 generation and Google's first flagship since Gemini 3.1 Pro in February. Google calls it "our next era of frontier intelligence" and pitches it at long, complex work: software engineering, legal and financial research, and cybersecurity defense. With Google's new long-decode feature it can write up to 1 million tokens in a single response, against 64,000 on earlier Gemini models, and it costs an introductory $2 per million input tokens and $10 per million output tokens until November 30, 2026.
For its first two weeks Argon went only to vetted cyber defenders in Google's Fairwind Program. On October 13, 2026, Google opened it to everyone who pays: developers on the paid Gemini API, Google AI Pro and Ultra subscribers in the Gemini app and AI Mode in Search, and Ultra subscribers in Google Antigravity and AI Studio. The free and Plus plans do not get it. This guide covers what Argon is, where you can use it, what Google's benchmarks show, the independent results, and the doubts reported among Google employees.
The Key Takeaways
- A real frontier model again: Artificial Analysis scores Gemini 4 Argon 53 on its Intelligence Index, level with GPT-6 Astra and Claude Fable 5.1, and behind Claude Opus 5.5 and Sonnet 5.5. Gemini 3.1 Pro scored 30.
- Cheap for now: $2 input and $10 output per million tokens is a 50% launch discount. The standard price of $4 and $20, the same as Opus 5.5, applies from December 1, 2026.
- Where it leads: 77.9% on DeepSWE v1.1, #1 on the Vals Index and the LMArena Text Arena, and the lowest hallucination rate Artificial Analysis has measured among leading models.
- Where it trails: Claude Opus 5.5 beats it on Terminal-Bench 4.0 (66.4% vs 57.4%) and GPT-6 Astra on FrontierSWE v2 (65.5% vs 55.0%). Bloomberg reports some Google staff think it struggles with real coding work.
- Who gets it: since October 13, Google AI Pro ($19.99 a month) and Ultra subscribers in the Gemini app, and developers on the paid Gemini API as
gemini-4-argon. Free and Google AI Plus users do not get it.
What Gemini 4 Argon Is
Gemini 4 Argon is Google DeepMind's new top model and the first release of Gemini 4. The launch post, written by Koray Kavukcuoglu, SVP of Google DeepMind and Google's Chief AI Architect, says Argon is "built to sustain deep reasoning across complex, long-horizon workflows." It is a reasoning model, which means it thinks through a problem before it answers, and Google names four areas where it wants Argon to be at the frontier: coding, enterprise knowledge work, cybersecurity defense and creative writing.
Google DeepMind announced it on its official account:
Introducing Gemini 4 Argon – our new frontier model.
— Google DeepMind (@GoogleDeepMind) September 30, 2026
It’s built for complex workflows across coding, enterprise knowledge work, and cybersecurity defense – rolling out today to a set of trusted testers through our Fairwind Program.
Why Gemini 4 took so long
Gemini 4 Argon ends a long gap in Google's lineup. Google's last flagship was Gemini 3.1 Pro, which we covered in our Gemini 3.1 Pro launch guide in February. Since then Google shipped only faster Flash models, most recently Gemini 3.8 Flash, and has still not released the Gemini 3.5 Pro it said in July was testing with partners. Kavukcuoglu told reporters on September 24 that Google "took a little bit of a step back" to focus on Flash and on Gemini 4, and that the plan was to release "an early post-training output" as soon as possible, 9to5Google reported. Our Gemini 4 tracker followed those developments from the first pre-training mention in July.
The name is new too. Earlier Gemini models were split into Pro, Flash and Flash-Lite tiers. Argon is the first Gemini with a codename-style name, like OpenAI's GPT-6 models Astra and Sol. Google has not said what the other Gemini 4 models will be called or when they will ship.
The specs that matter
These figures come from the Gemini API model page and the Argon model card, which Google published with the public release on October 13.
| Spec | Gemini 4 Argon |
|---|---|
| Announced | September 30, 2026 (Fairwind Program only) |
| Public release | October 13, 2026 |
| API model ID | gemini-4-argon (stable) |
| Introductory price per 1M tokens | $2 input, $10 output, $0.10 cached input, until November 30, 2026 |
| Standard price per 1M tokens | $4 input, $20 output |
| Context window | 1,048,576 tokens, shared between input and output |
| Max output | 65,536 tokens by default, up to 1,048,576 with long decode |
| Input / output | Text, image, video, audio and PDF in, text out |
| Thinking levels | Low, medium, high |
| Knowledge cutoff | March 2026 |
| Architecture | Sparse mixture-of-experts, trained from scratch rather than fine-tuned from an earlier Gemini |
Who Can Use Gemini 4 Argon Today
Since October 13, 2026, anyone who pays for the right Google plan can use Gemini 4 Argon. The Gemini app release notes say it is "rolling out globally for Google AI Pro & Ultra subscribers", and Google's plans page now lists "Access to Gemini 4 Argon" on both. Here is where it shows up and what you need:
| Where | Who gets Gemini 4 Argon |
|---|---|
| Gemini app (web, mobile, desktop) | Google AI Pro ($19.99 a month) and Ultra ($99.99 or $199.99) |
| AI Mode in Google Search | Google AI Pro and Ultra |
| Gemini API | Paid tier only, as gemini-4-argon |
| Google AI Studio and Android Studio | Paid Gemini API tier, or Google AI Ultra |
| Google Antigravity | Google AI Ultra and business customers |
| Gemini for business | Business and enterprise customers |
| Free and Google AI Plus | Not included |
The free plan's model is now 3.5 Flash-Lite and Google AI Plus gets 3.6 Flash, so Pro is the cheapest way to use Argon in the Gemini app. Google has not said whether Argon will reach the lower plans. On Pro and Ultra, 9to5Google reports that the model picker now offers 3.5 Flash-Lite, 3.8 Flash, 3.1 Pro and 4 Argon. Our Gemini pricing guide covers what each plan includes.
Sundar Pichai, Google's CEO, marked the public release with a short video on X:
— Sundar Pichai (@sundarpichai) October 13, 2026
Google skipped a step it had announced. On September 30 it said Ultra subscribers and paid API customers would come first, but Pro subscribers got Argon on the same day as Ultra. The same day, Google built its Antigravity coding agent into the Gemini app for Mac, and it is offering 10,000 scientists Antigravity's highest usage tier free for six months, subject to selection.
The two-week Fairwind head start
From September 30 to October 13, Gemini 4 Argon went only to the Fairwind Program, Google DeepMind's controlled-access scheme for organizations that defend networks and software. Its page gives priority to governments and national cyber authorities, critical-infrastructure operators in healthcare, telecoms, energy and finance, and core technology platforms. Academic labs that focus on defensive benchmarking can also apply. Applicants are vetted, need phishing-resistant multi-factor authentication, and may not share or resell access. Google said more than 650 partners took part at launch, and on October 13 it began expanding the program to hundreds more.
Google's launch post says Fairwind partners and internal Google teams get a version of Argon without its cyber guardrails, the filters that normally block requests that look like hacking. They can also use it inside CodeMender, Google's agent that finds and patches security bugs. The only partner Google names in its launch post is Wiz, the cloud security company Google owns. Wiz used Argon in its Scan for Good project and, according to Google, found a critical vulnerability in healthcare software used by hospitals worldwide that earlier frontier models had missed.
Logan Kilpatrick, who leads Google AI Studio and the Gemini API, described the plan on launch day:
Introducing Gemini 4 Argon, our new frontier model, rolling out to cyber defenders starting today, and more widely as soon as possible. I am really excited by the progress we have made here. Argon is priced at $2 in and $10 out during introductory pricing!
— Logan Kilpatrick (@OfficialLoganK) September 30, 2026
Google also takes part in the U.S. government's voluntary process for reviewing frontier models before release. Anthropic and OpenAI also limited initial access to their strongest cyber models, through Anthropic's Project Glasswing and OpenAI's Daybreak program.
Gemini 4 Argon Pricing: Half Price for Now
Gemini 4 Argon's launch price is a 50% promotion. Google's post says Argon "will launch at an introductory price of $2 per million input tokens and $10 per million output tokens, with cached input tokens priced at 95% off input token price." After the promotion it costs $4 and $20. A footnote in Google's October 13 post sets the end date: the introductory price expires on November 30, 2026, so budget on the standard price for anything that runs past that. Caching is automatic only: the API page says Argon does not support explicit caching.
At the launch price, Argon is one of the cheapest frontier models. At the standard price, it costs the same per token as Claude Opus 5.5.
| Model | Input per 1M | Output per 1M | Cached input per 1M |
|---|---|---|---|
| Gemini 4 Argon (introductory) | $2 | $10 | $0.10 |
| Gemini 4 Argon (standard) | $4 | $20 | $0.20 |
| Gemini 3.1 Pro | $2 | $12 | not compared |
| Claude Opus 5.5 | $4 | $20 | $0.20 |
| Claude Sonnet 5.5 | $2 | $10 | $0.10 |
| GPT-6 Astra | $10 | $50 | $1 |
| GPT-6.1 Sol | $2 | $10 | $0.10 |
What a task actually costs
Models use very different numbers of tokens for the same job, so token prices alone do not tell you what a task costs. Artificial Analysis measured what it costs to run each model through its Intelligence Index. At the introductory price, Gemini 4 Argon costs $1.99 per task, 60% of GPT-6 Astra's $3.26. That is well under Claude Opus 5.5 at $5.98 and Claude Sonnet 5.5 at max effort at $7.62. At the standard price, Argon's cost rises to $3.98 per task, about 1.2 times GPT-6 Astra.
Argon is not a frugal model. Artificial Analysis says its low cost comes from low token prices, "rather than reduced token use." Argon averaged 62,000 output tokens per task, against 27,000 for GPT-6 Astra, and it costs 2.7 times as much per task as GPT-6.1 Sol. Without the discount, Argon loses most of its price advantage. Our guide to what AI tokens are explains how token counts turn into a bill.
Gemini 4 Argon Benchmarks: Google's Numbers
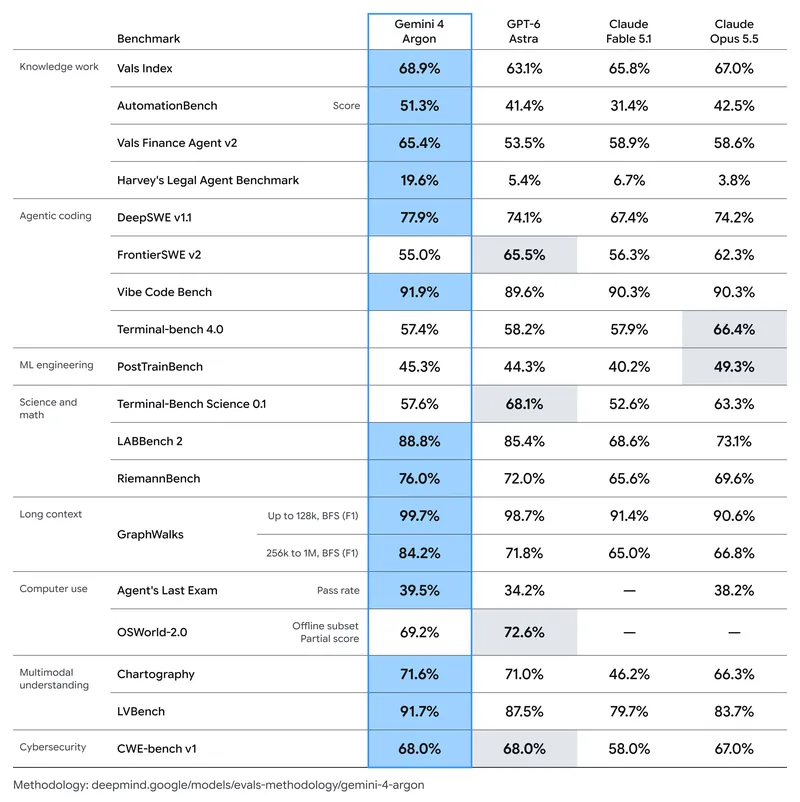
Google's launch post shows Gemini 4 Argon leading on long software tasks, business automation, legal and financial work, and long video. Google's full benchmark table is below, followed by the rows that matter most, checked against the write-ups by VentureBeat and MarkTechPost. By VentureBeat's count, Argon leads 12 of the 18 benchmarks Google published and ties one more.
| Benchmark | Gemini 4 Argon | Claude Opus 5.5 | GPT-6 Astra |
|---|---|---|---|
| DeepSWE v1.1 (long software tasks) | 77.9% | 74.2% | 74.1% |
| Vals Index (finance, law, coding, tax) | 68.9% | 67.0% | 63.1% |
| AutomationBench (business workflows) | 51.3% | 42.5% | 41.4% |
| Vals Finance Agent v2 | 65.4% | 58.6% | 53.5% |
| Harvey Legal Agent | 19.6% | 3.8% | 5.4% |
| GraphWalks (long context) | 84.2% | 66.8% | 71.8% |
| LVBench (long video) | 91.7% | 83.7% | 87.5% |
| CWE-bench v1 (fixing security flaws) | 68% | 67% | 68% |
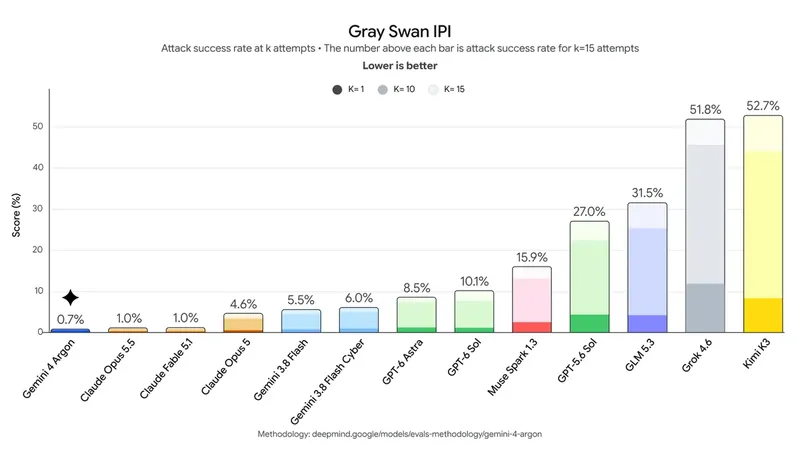
| Gray Swan IPI (prompt-injection success, lower is better) | 0.7% | 1.0% | 8.5% |
| Terminal-Bench 4.0 (agentic coding) | 57.4% | 66.4% | 58.2% |
| FrontierSWE v2 | 55.0% | 62.3% | 65.5% |
| PostTrainBench | 45.3% | 49.3% | 44.3% |
| Terminal-Bench Science 0.1 | 57.6% | 63.3% | 68.1% |
Argon's biggest wins are in professional knowledge work rather than pure coding: legal drafting, financial research and business automation. Its coding results are mixed. Argon leads DeepSWE, which tests long real-world software tasks. Claude Opus 5.5 is well ahead on Terminal-Bench 4.0, and GPT-6 Astra edges Argon there too. Astra leads FrontierSWE v2 by ten points. Google's post does not claim a clean sweep, and it should not.
Treat rival scores in a vendor's table with care. Labs run each other's models with their own settings, so the numbers do not always match. Anthropic's own launch table, for example, puts Claude Opus 5.5 at 40.0% on AutomationBench, not the 42.5% Google lists.
The cyber numbers
Cybersecurity is the headline use case, but Argon does not dominate the tests. On CWE-bench v1, which measures how well a model fixes known classes of security flaws, Argon scores 68%. That ties GPT-6 Astra and Grok 4.7 and sits one point above Claude Opus 5.5. The Fairwind page adds a score of 85.8% on a real-world vulnerability discovery benchmark that has not been published, so it cannot be compared with other models. On independent tests, Vals ranks Argon #2 on its CyberBench at 77.86%, 0.12 points behind GPT-6 Sol.
The prompt-injection number matters more for everyday users. On Gray Swan's indirect prompt injection benchmark, attacks hidden inside web pages or documents succeeded against Argon only 0.7% of the time, against 8.5% for GPT-6 Astra. These attacks hit AI agents browsing the web or reading your email, so a low success rate is a safety gain.
What Independent Testers Found
Three independent leaderboards published Gemini 4 Argon results within hours of the September 30 announcement, two weeks before the public release. All three put it at or near the top and found the same weaknesses as Google's own table. The figures below are from that launch-day testing.
Artificial Analysis: level with GPT-6 Astra
With reasoning set to high, Gemini 4 Argon scored 53 on Artificial Analysis's Intelligence Index. That matches GPT-6 Astra and Claude Fable 5.1 and is one point above GPT-6.1 Sol, but below Claude Opus 5.5 at 58 and Claude Sonnet 5.5 at 56. It is also 23 points above Gemini 3.1 Pro Preview, which puts Google back among the top three labs on this measure:
Google’s new Gemini 4 Argon equals GPT-6 Astra on the Artificial Analysis Intelligence Index at 60% of the Cost per Task with discounted prices. Google is now back to being one of the top three labs in intelligence achieved
— Artificial Analysis (@ArtificialAnlys) September 30, 2026
The most useful finding is about hallucinations. On Artificial Analysis's AA-Omniscience test, Gemini 4 Argon made things up 15% of the time, the lowest rate of any model scoring 45 or more on the Intelligence Index. GPT-6 Astra scored 51% and GPT-6.1 Sol 54%. In practice, Argon is much more likely to say it does not know than to guess. The trade-off is lower accuracy: Argon answered 50% of the factual questions correctly, 13 points below GPT-6 Astra. A model that declines more often gets fewer answers wrong, but it also gets fewer right.
Artificial Analysis also found Argon much stronger at agent work than past Gemini models. It ranked #1 on AutomationBench-AA at 77.5%, six points ahead of Claude Sonnet 5.5. On Terminal-Bench 4 it scored 57%, a 53-point jump over Gemini 3.1 Pro Preview but still behind Claude Sonnet 5.5, Claude Opus 5.5 and GPT-6 Astra.
Vals and LMArena: first place
On the Vals Index, which tests finance, legal, medical and coding tasks, Gemini 4 Argon ranks #1 of 41 models at 68.90%. It is ahead of Claude Sonnet 5.5 at 67.04% and Claude Opus 5.5 at 66.97%, and it cost $15.68 per test run against $32.14 for Opus 5.5. Vals also recorded a perfect 100% on its IOI programming-olympiad test, tied with GPT-6 Astra.
In LMArena's blind Text Arena, where people vote between two anonymous answers, Argon took first place with 1525 points. It also ranked first in the coding, hard prompts, instruction following and creative writing categories. Its web development score was weaker: #8 in Code Arena: WebDev with 1679 points, although that is a big jump from Gemini 3.8 Flash at #29.
Big news: Gemini 4 Argon (High) by @GoogleDeepMind just landed #1 in Text Arena with 1525 pts, and #8 in Code Arena: WebDev with 1679 pts!
— Arena.ai (@arena) September 30, 2026
This release has reshaped the Text Arena Pareto frontier with a blended $8/MToken! Gemini 4 Argon (High) is now the most cost efficient model, see its placement on Pareto frontier below.
If you want the background on what these leaderboards measure and where they mislead, see our AI benchmarks explainer.
The Doubts: Great on Benchmarks, Weaker at Real Work?
On launch day, Bloomberg reported that some Google employees are skeptical of Gemini 4. Bloomberg cited people with direct access who said the model does well on industry benchmarks but less well on employees' real tasks. They also said it struggles with some coding jobs. One weakness they named was front-end design, the code that decides how apps and websites look. Google disputed the report and said it would be inaccurate to call Gemini 4 an underperformer in areas like coding. One employee told Bloomberg there is a "large consensus" inside the company that the model is at the frontier.
Nine days later, the internal picture had shifted. Business Insider reported on October 9 that Google staff are testing a newer Gemini 4 version called Carbon in Jetski, Google's internal coding platform. One employee said Carbon "feels like Opus 5.5" for coding, though they wanted to test it more. Another said early versions of Argon felt behind on some coding tasks, closer to the older Claude Opus 5. Internal documents seen by Business Insider show that the model going public as Argon is a checkpoint called "Barium-B", so Carbon is a newer build than the checkpoint Google picked for launch. Business Insider could not determine whether Carbon will arrive as an Argon update or as a separate Gemini 4 model, and Google is not guaranteed to release it. There are no benchmark results for Carbon yet.
The public data partly supports both sides. Argon's #8 finish in Code Arena: WebDev matches the front-end complaint, and its Terminal-Bench and FrontierSWE scores trail Anthropic and OpenAI. But its DeepSWE lead and first place in the Text Arena's coding category show it is not a weak coder overall. Since October 13, paying users can check how the benchmark lead holds up on their own work.
How Google Is Already Using Argon
Google says teams across the company are already using Gemini 4 Argon, and its launch post gives four examples. Sundar Pichai, Google's CEO, said teams use it "extensively at Google, from coding to quantum computing" with "great feedback":
- Rust migrations: Argon agents are moving C and C++ codebases to the memory-safe Rust language, including work on the Zircon kernel of Google's Fuchsia operating system, which MarkTechPost puts at more than 800,000 lines.
- Faster video decoding: in the libgav1 AV1 decoder, agents replaced about 32,000 lines of hand-tuned SIMD code and made the decoder 2.7 times faster.
- Data-center memory: Argon analyzed profiling data from Google's server fleet and applied memory optimizations on its own, freeing more than 300 TiB.
- Quantum computing: Argon beat a published quantum algorithm baseline by 40% in an optimization task.
Google added more examples with the public release. It says Argon helped the Chrome team split a legacy folder of about 6 million lines out of Chromium's 40-million-line codebase, made its open Gemma 4 E2B model run 2.85 times faster on an A100 GPU, and raised agentic code submissions inside Google by more than 35% while cutting rollbacks by nearly a third.
These examples come from Google and cannot be independently checked. They show what the 1 million token output limit is for: jobs that run for hours and write huge amounts of code in one go.
What the 1 million token output limit means
Most models can write between 64,000 and 128,000 tokens in one response. A normal Gemini 4 Argon request also stops at 65,536 tokens, but with the API's new long decode feature it can keep going up to about 1 million, roughly 750,000 words. Long decode pauses a very long answer and resumes it across follow-up calls, so reasoning can run that far without the request timing out. The 1 million figure is a shared budget: the API page lists a single 1,048,576-token limit for input and output combined, so a long prompt leaves less room for the answer. For chat this makes no difference. For agents that migrate a whole codebase, draft a long legal document or reason through a hard problem for many minutes, it removes a limit that used to cut work off halfway.
Long outputs also mean long waits and big bills. Every output token is billed at the $10 or $20 output rate, so a single million-token answer costs $10 at the launch price and $20 after it.
Safety: Guardrails On for Everyone but Defenders
Google says it has strengthened four kinds of safeguards before Gemini 4 Argon's wider release. They cover misuse for cyberattacks and chemical, biological, radiological and nuclear weapons, attacks hidden in content the model reads, signs that the model is working against its instructions, and insecure agent environments. For the last two, Google says it monitors the model's chain of thought and runs high-risk tests in sealed sandboxes. The public release keeps the cyber guardrails that Fairwind partners and internal Google teams work without. Google's October 13 post adds that external biology red teamers could unlock fewer than 1% of the bio sub-tasks it tests for, and that shortcut attempts, such as working around a failing test, fell to 2% on its coding tests.
The model card Google published on October 13 is frank about the risks. Under its Frontier Safety Framework, Google says it cannot rule out that Argon has reached the critical capability level for biological risk or for cyberattacks, or the alert threshold for stealth and situational awareness, meaning the ability to notice its own setup and slip past basic oversight. For each, Google says the safeguards it applied bring the risk back below that level. The card points to a fuller Safety and Security Report for the detail. Anthropic published a system card for Claude Opus 5.5 on launch day, which our Opus 5.5 guide summarizes.
Gemini 4 Argon vs Claude Opus 5.5 vs GPT-6 Astra
Now that Gemini 4 Argon is public, this is how the three frontier models compare on the evidence so far.
| If you need | Best pick on current data | Why |
|---|---|---|
| Legal, finance and business automation | Gemini 4 Argon | Clear leads on Harvey Legal Agent, Finance Agent v2, AutomationBench and the Vals Index |
| Answers you can trust not to be invented | Gemini 4 Argon | 15% hallucination rate, the lowest Artificial Analysis has measured among leading models |
| Long video and very long documents | Gemini 4 Argon | Leads LVBench and GraphWalks |
| Terminal and agentic coding | Claude Opus 5.5 | 66.4% on Terminal-Bench 4.0 against Argon's 57.4% |
| Front-end and web design | Claude Opus 5.5 or GPT-6 Astra | Argon is #8 in Code Arena: WebDev |
| Hard science and frontier coding | GPT-6 Astra | Leads FrontierSWE v2 and Terminal-Bench Science |
| Highest overall intelligence score | Claude Opus 5.5 | 58 on the Artificial Analysis Intelligence Index against 53 |
| Lowest cost per task | GPT-6.1 Sol | Argon costs 2.7 times as much per task even at its launch price |
If you want to compare models on your own prompts, you can already run the current Gemini, GPT and Claude models side by side in Fello AI and switch between them in one chat.
The Verdict on Gemini 4 Argon
Gemini 4 Argon puts Google back at the frontier after seven months without a flagship. It leads on legal, financial and automation work, has the lowest hallucination rate among top models, and at the launch price it gets GPT-6 Astra-level results for 60% of the cost per task. It does not beat Claude Opus 5.5 overall, and it trails on terminal coding and front-end work, the same weak spot Google's own employees reportedly flagged. If you already pay for Google AI Pro, you can try it in the Gemini app today. Developers should test it on their own workloads before November 30, while the half-price introductory rate still applies, and budget on $4 and $20 after that.
Frequently Asked Questions
When was Gemini 4 Argon released?
Google announced Gemini 4 Argon on September 30, 2026, when it went only to trusted cyber defenders in Google's Fairwind Program. The public release followed on October 13, 2026, for paid Gemini API users and Google AI Pro and Ultra subscribers.
How much does Gemini 4 Argon cost?
Gemini 4 Argon costs $2 per million input tokens and $10 per million output tokens during an introductory period, with cached input at $0.10. The introductory price ends on November 30, 2026. After that it costs $4 and $20, the same as Claude Opus 5.5.
Can I use Gemini 4 Argon in the Gemini app?
Yes, if you pay for Google AI Pro ($19.99 a month) or Ultra. Since October 13, 2026, Gemini 4 Argon has been rolling out in the Gemini app and AI Mode in Search for both plans. The free plan and Google AI Plus do not include it, and Google has not said whether they will.
What is the Gemini 4 Argon API model ID?
The model ID is gemini-4-argon, a stable model on the paid tier of the Gemini API. It accepts text, images, video, audio and PDFs, has a 1,048,576-token limit shared between input and output, and supports low, medium and high thinking levels. Its knowledge cutoff is March 2026.
Is Gemini 4 Argon better than Claude Opus 5.5?
Gemini 4 Argon beats Claude Opus 5.5 on legal, finance, automation and long-video benchmarks and on the Vals Index. Opus 5.5 is ahead on Terminal-Bench 4.0, FrontierSWE v2 and the Artificial Analysis Intelligence Index, where it scores 58 against Argon's 53. Which is better depends on the kind of work you do.
What is the Fairwind Program?
The Fairwind Program is Google DeepMind's early-access scheme for vetted cyber defenders, such as governments, critical-infrastructure operators, technology platforms and academic security labs. Members get Gemini 4 Argon without its cyber guardrails for defensive work, and they had it two weeks before the public release. Google had more than 650 partners at launch and began adding hundreds more on October 13.
What happened to Gemini 3.5 Pro?
Google has not released Gemini 3.5 Pro and has not said whether it will. Google DeepMind's Koray Kavukcuoglu said in September 2026 that the company "took a little bit of a step back" to focus on its Flash models, and that its focus now is Gemini 4. Gemini 4 Argon is the first Google flagship since Gemini 3.1 Pro in February 2026.