Best AI Models in 2026
Rankings, comparisons, and deep dives, updated monthly as new models ship.
- Smartest overall and codingClaude Opus 5.5
- Hardest reasoningGPT-6 Astra
- ImagesChatGPT Images 2.5
- Best free pickClaude Sonnet 5.5
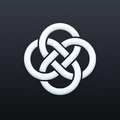
Stop tab-hopping between AI apps
Chat, search, PDFs and images in one app for Mac, iPhone and iPad.
Free to start·4.7★ from 27,000+ reviews
Rankings show who wins on average. Your prompt isn't average. Ask ChatGPT, Claude and Gemini in one window and keep the best answer.
Download Fello AIAnthropic still holds most of the measured crowns, and Artificial Analysis re-scaled the board this week. On its new Intelligence Index v5 (October 27), Claude Opus 5.5 scores 58.4 and leads every model you can actually use, ahead of GPT-6 Astra at 56.9, GPT-6.1 Sol at 54.5 and Claude Sonnet 5.5 at 54.2, which is free on claude.ai. Our guide to AI benchmarks explains how that index is built.
Google's Gemini 4 Carbon (October 28) scores higher still, 59.4, but only vetted cyber defenders can use it, so it takes no crown here, just as Gemini 4 Argon took none before its public release. Argon, open to Google AI Pro and Ultra since October 13, scores 50.4 and keeps second place on the chat podium. OpenAI competes on price: GPT-6.1 Sol is still the cheapest route past 50 on the index, and GPT-6.1 Terra (October 26) scores 51.0 at $1 / $5.
Moonshot's Kimi K3.1 Pro (October 23) leads Terminal-Bench 4.0 at 67% and is second on EQ-Bench Creative Writing, which puts it on the writing podium, though its open weights are only promised for November 4. On the new scale the best open model is DeepSeek's V4.1-Flash-1017 at 32.5, ahead of GLM-5.3 and Xiaomi's MiMo-V2.6-Pro, which stays the cheapest per task. Video belongs to MiniMax H3 and images to ChatGPT Images 2.5. Arena's boards could not be re-read for this update, so Arena figures date from October 20 and 24. Rankings are updated within 48 hours of any major launch.
Oct 28 Google Gemini 4 Carbon tops Intelligence Index v5 at 59.4, but only cyber defenders can use it New
Oct 27 Artificial Analysis Artificial Analysis launches Intelligence Index v5, which re-scales every score on this page New
Oct 26 OpenAI GPT-6.1 Terra scores 51.0 at half GPT-6.1 Sol's price, in ChatGPT Work and Codex New
Oct 23 Moonshot Kimi K3.1 Pro lands fourth on the Intelligence Index and first on Terminal-Bench 4.0, at $2 / $10 New
Oct 17 DeepSeek DeepSeek V4.1-Flash-1017 scores 45.1 at unchanged prices and takes the open price-performance pick New
Oct 15 Meta publishes the weights of Muse Spark Open, an 816B model under its own licence New
Oct 15 fal fal's FLUX 3 Max, a faster post-trained FLUX 3 Video, enters Artificial Analysis's video boards fourth and second New
Oct 13 Google Gemini 4 Argon opens to Google AI Pro, Ultra and the paid API, and takes second place on the chat podium New
Oct 12 Muse Wonder Full lands third on the Intelligence Index, but only inside Meta's Muse Code subscription New
Oct 7 Anthropic Claude Haiku 5.5 scores 43.4 at GPT-6 Luna's price, and every Claude plan can pick it, Free included New
Oct 6 Mistral Mistral Large 4 is the strongest model from the US or Europe that promises open weights, but you cannot download it yet New
Oct 6 Google Nano Banana 2.1 replaces Nano Banana 2 at half the price per image and lands fifth on Arena text-to-image New
Sep 30 Google Gemini 4 Argon tops Arena's text board and matches GPT-6 Astra on the Intelligence Index, but only cyber defenders can use it New
Sep 29 OpenAI GPT-6.1 Sol reaches fifth on the Intelligence Index at $2 / $10, the cheapest per task in the top tier New
Sep 28 Anthropic Claude Sonnet 5.5 lands second on the Intelligence Index at 56.0, at Sonnet's $2 / $10 New
Sep 22 OpenAI GPT-6 Sol and GPT-6 Luna halve OpenAI's API prices, and land everywhere except ChatGPT's chat window New
Sep 22 Anthropic Claude Opus 5.5 takes the Intelligence Index at 57.6 and undercuts Opus 5 on price New
Sep 21 SpaceXAI Grok 4.7 arrives on a larger base model at an unchanged $2 / $6, and costs 47% more per task New
Sep 21 Xiaomi Xiaomi's MiMo-V2.6-Pro is the highest-scoring open model ever measured, at $0.13 an index task under MIT New
Sep 20 Alibaba Qwen-Image-2.1 is the best image model you can download, but its licence allows research use only New
Sep 15 TypeSafe TypeSafe leaves stealth with Jev, a model that returns typed decisions instead of text, at $0.042 per 1M tokens New
Pending Google Gemini 3.5 Pro, still unreleased, and Gemini 4 Argon has overtaken it Delayed
Best AI for Writing
The best AI for writing is Claude Fable 5.1, and the case for it is consistency rather than a single first place.
It is inside the top ten of all three prose boards: third on EQ-Bench Creative Writing v3 at 2155.3, behind GPT-6 Astra and Moonshot's new Kimi K3.1 Pro, third on LiveBench Language at 89.5 and ninth on Arena's creative-writing board, the best combined placing of any model. Gemini 4 Argon leads Arena's text board at 1517.2 and is second on its creative-writing board at 1515.6, and Google AI Pro subscribers can use it since October 13, but EQ-Bench puts it only 32nd, at 1757.8, and LiveBench has not rated it yet.
Claude Opus 5.5 has taken first place on Arena's creative-writing board at 1519.1, but it is eighth on EQ-Bench and tenth on LiveBench Language; GPT-6 Astra leads EQ-Bench at 2176.9 but sits 38th on Arena's creative-writing board; Kimi K3.1 Pro is second on EQ-Bench at 2172.6, but LiveBench has not rated it; Claude Fable 5 tops LiveBench Language at 90.7 and is third on Arena's creative-writing board, but 13th on EQ-Bench. If your writing is a work deliverable rather than prose, the GDPval-AA v2.1 professional-deliverables board is a different question, and Claude Opus 5.5 leads it at 1866, ahead of Meta's Muse Wonder Full at 1857, Kimi K3.1 Pro at 1846, Claude Sonnet 5.5 at 1838 and Claude Fable 5.1 at 1764.
Claude Sonnet 5.5 is the free-tier value pick, since anyone can use it on claude.ai, though it scores 83.4 on LiveBench Language, sits only 22nd on Arena's creative-writing board and has no EQ-Bench rating yet. Claude Fable 5 is the pick if you weight Arena's human votes above the harness scores; it costs $10 / $50 per 1M tokens and is permanently included in Claude Max and Team Premium at roughly 50% of regular usage limits. Translation is a separate question with a separate winner, which we work through in our guide to the best AI for translation.
| Model | Best For | Strength | Weakness | Price (per 1M tokens) |
|---|---|---|---|---|
| Claude Fable 5.1 | Best writing overall | #3 EQ-Bench Creative Writing (2155.3), #3 LiveBench Language (89.5) and #9 Arena creative writing, the best combined placing of any model | Leads none of the three outright; Claude Opus 5.5 leads Arena's creative-writing board and GPT-6 Astra leads EQ-Bench | $10 / $50 |
| Claude Fable 5 | Strong on the human-vote boards | #1 LiveBench Language (90.7), #3 Arena creative writing (1501.5), #4 Arena text (1503.3) | #13 EQ-Bench; priciest option here | $10 / $50 |
| Kimi K3.1 Pro | Creative fiction and voice | #2 EQ-Bench Creative Writing (2172.6), 4.3 points behind GPT-6 Astra; #3 GDPval-AA v2.1 (1846) | Not yet rated on LiveBench; open weights only promised for November 4 | $2 / $10 |
| Claude Sonnet 5.5 | Free everyday writing | Free on claude.ai, 1M context; #4 GDPval-AA v2.1 (1838), behind Opus 5.5, Muse Wonder Full and Kimi K3.1 Pro | 83.4 LiveBench Language; #22 Arena creative writing; not yet rated on EQ-Bench | $2 / $10 |
| Claude Opus 5.5 | Arena's top creative writer | #1 Arena creative writing (1519) and #2 Arena text (1509); #1 GDPval-AA v2.1 (1866) | #8 EQ-Bench and #10 LiveBench Language | $4 / $20 |
| Gemini 4 Argon | Top-voted model on Arena | #1 Arena text (1517.2) and #2 Arena creative writing (1515.6) | #32 on EQ-Bench (1757.8); unrated on LiveBench | $19.99/mo Google AI Pro; $2 / $10 API intro to Nov 30 |
| GPT-5.5 | Fact-anchored business writing | Documented factual-reliability gains over GPT-5.4 | Reasoning tiers now marked deprecated | $5 / $30 |
| Gemini 3.8 Flash | Bulk drafts at scale | Intelligence Index 30.5 (v5), 308.4 tok/s output, 1M context | Agent-tuned rather than prose-tuned; intro price doubles January 1, 2027 | $0.75 / $3.75 |
The writing crown stays with Claude Fable 5.1, which still has the best combined placing across the three prose boards. Since the last update EQ-Bench re-ran its board on October 28 and rated Moonshot's Kimi K3.1 Pro second at 2172.6, which pushes Fable 5.1 to third there, so Kimi K3.1 Pro replaces Kimi K3 on the podium as the fiction pick. Earlier this month Claude Opus 5.5 took first place on Arena's creative-writing board and EQ-Bench rated Gemini 4 Argon 32nd. In September, Claude Opus 5.5 and Claude Sonnet 5.5 arrived, Sonnet 5.5 replaced Sonnet 5 as the free pick, and GPT-6.1 Sol entered LiveBench Language second, pushing Fable 5.1 to third there.
Best AI for Chat & Daily Assistant
The best AI for everyday chat is GPT-6, and the honest reason is reach rather than board position. Since October 7 it is what ChatGPT answers with by default: GPT-6 Sol on Plus, Pro, Business and Enterprise, and GPT-6 Luna on Free and Go, rolling out from October 8. That makes it the assistant most people can actually open.
On raw human preference it is far from the lead. GPT-6 Sol sits #62 on Arena's text leaderboard at 1459.0, below its predecessor GPT-5.6 Sol at #21, while Gemini 4 Argon leads at 1517.2, Claude Opus 5.5 is second at 1508.7 and Meta's Muse Wonder third, also at 1508.7. Artificial Analysis has not scored GPT-6 Sol on its new Intelligence Index v5, where GPT-6 Luna reads 27.8; on v4.3.2 Sol read 47.6. In the API, Sol costs $2 / $10 and Luna $0.10 / $0.50 per 1M tokens.
| Model | Best For | Strength | Weakness | Price |
|---|---|---|---|---|
| GPT-6 | Everyday chat, ChatGPT's default | The assistant most people can open: Sol on paid plans, Luna on Free and Go | GPT-6 Sol only #62 on Arena text | Free / $20/mo Plus; API $0.10 / $0.50 (Luna) to $2 / $10 (Sol) |
| Gemini 4 Argon | Top-voted conversation | #1 on Arena text (1517.2); 4% hallucination rate on AA-Omniscience, the lowest among leading models | Arena rating still preliminary; Google AI Pro or above in the Gemini app | $19.99/mo Google AI Pro; $2 / $10 API intro to Nov 30 |
| Claude Opus 5.5 | Highest-scoring conversation you can use | 58.4 on Intelligence Index v5, the highest of any model you can use, and #2 on Arena text (1508.7) | Not on the Free plan; usage-limited on Pro; Gemini 4 Carbon scores a point higher but only cyber defenders can use it | $20/mo Pro, $4 / $20 API |
| Claude Sonnet 5.5 | Free Claude chat | Free on claude.ai; 54.2 on Intelligence Index v5 at max effort, fifth among distinct models | Only #29 on Arena text; the apps run it at Medium effort, where it scores 30.3 | Free / $20/mo Pro, $2 / $10 API |
| GPT-5.5 Instant | Hallucination-sensitive daily work | 52.5% fewer hallucinated claims vs 5.3 Instant | Reasoning tiers now marked deprecated | $20/mo Plus; API $5 / $30 |
| Gemini 3.6 Flash | Fast, cheap, multimodal | 1M context, #22 on Arena text | Needs Google AI Plus in the Gemini app since October 9; 3.8 Flash outscores it at the same price | AI Plus / $0.75 / $3.75 API |
| Fello AI | Many leading models, one app | ChatGPT + Claude + Gemini + Grok + DeepSeek and more on Mac, iPhone and iPad | Routed via app, not direct | From $11.99/mo |
GPT-6 keeps the chat pick, because it is what ChatGPT answers with by default: GPT-6 Sol on paid plans since October 7 and GPT-6 Luna on Free and Go from October 8. Since the last update Artificial Analysis moved to Intelligence Index v5, where Google's new Gemini 4 Carbon scores 59.4 against Claude Opus 5.5's 58.4, but only vetted cyber defenders can use Carbon, so the podium does not move, and GPT-6.1 Terra, released October 26, stays in ChatGPT Work and Codex rather than the chat window. Earlier this month the pick moved from GPT-5.6 to GPT-6, and Gemini 4 Argon, the leader of Arena's text board, took second place when it reached Google AI Pro and Ultra on October 13.
Best AI for Images
The best AI for image generation is ChatGPT Images 2.5, which OpenAI made the default on every ChatGPT tier on September 8 and which leads all four image boards we track.
GPT-Image-2.5 Sunburst, built for precision, leads all four: Arena text-to-image at 1424.6, Arena image editing at 1523.6, Artificial Analysis's AA-Image-T2I v2.1 at 1222 and AA-Image-Editing v2.1 at 1199. The faster GPT-Image-2.5 Flare is second on three of them, and third on Artificial Analysis's editing board, where Microsoft's MAI-Image-2.7-Preview, released in October, has moved in between at 1193. Read the Sunburst-to-Flare gap on Arena text-to-image as provisional, because each rests on about 17,000 votes against GPT Image 2's 93,000. MAI-Image-2.6 is the runner-up, fourth on Artificial Analysis's editing board at 1151, in a three-way tie with Krea 3 (Ultra) and Nano Banana 2.1, and fifth on Arena's text-to-image board at 1332.1, a statistical tie with Grok Imagine Image 2.0 just above it.
Third is SpaceXAI's Grok Imagine Image 2.0, released in August and available in Grok Imagine and the xAI API: it is fourth on both Arena boards and sixth on Artificial Analysis's text-to-image board, ahead of Meta's Muse Image on three of the four boards. Google's Nano Banana 2.1, released on October 6, is now the highest-ranked Google model: sixth on Arena text-to-image at 1327.8, in the same rank band as MAI-Image-2.6 and Grok Imagine Image 2.0, and sixth on Arena editing, while on Artificial Analysis's v2.1 boards it is fourth on text-to-image at 1176, above both, and level with MAI-Image-2.6 on editing at 1151, well ahead of Grok Imagine Image 2.0.
The best image model you can download is Alibaba's Qwen-Image-2.1, released on September 20 and now the highest-ranked open-weight model on both Arena boards, 18th on image editing and 19th on text-to-image, and one place behind a newer open model on each Artificial Analysis board, Black Forest Labs' FLUX 3 Image Klein on text-to-image and Bria's non-commercial Fibo 2.0 on editing, but its licence allows research and evaluation only, so it is not a free commercial option. Our full breakdown of what shipped is in ChatGPT Images 2.5.
| Model | Best For | Strength | Weakness | Price |
|---|---|---|---|---|
| ChatGPT Images 2.5 | Images with readable text | Sunburst #1 on all four boards and Flare #2 on three: Arena text-to-image (1424.6 / 1397.6), Arena editing (1523.6 / 1481.0), Artificial Analysis text-to-image (1222 / 1207) and editing (1199, with Flare third at 1182) | Its Arena text-to-image lead rests on about 17,000 votes per model | Default on every ChatGPT tier |
| MAI-Image-2.6 | Editing an image you already have | #4 on Artificial Analysis image editing (1151, a three-way tie) and #5 on Arena text-to-image (1332.1) | Public preview, not in Copilot or Bing yet; its successor MAI-Image-2.7-Preview, editing only so far, is now second on that board | MAI Playground / Microsoft Foundry |
| Grok Imagine Image 2.0 | Fewest restrictions, Spicy Mode | #6 on Artificial Analysis text-to-image (1166) and #4 on Arena image editing (1439.1); #4 on Arena text-to-image (1333.5) | Only #17 on Artificial Analysis image editing | $30/mo Premium (X Subscription); xAI API |
| Nano Banana 2.1 | Google's everyday image model | #6 Arena text-to-image (1327.8) and #6 Arena image editing (1428.1), the highest of any Google model; half Nano Banana 2's API price per image | Behind MAI-Image-2.6 and Grok Imagine Image 2.0 on both Arena boards, though #4 on Artificial Analysis text-to-image (1176); input tokens cost three times as much as on Nano Banana 2 | Gemini app / AI Studio; $0.0336 per 1K image |
| Seedream 5.0 Pro | Multilingual text + region editing | 10+ languages incl. Arabic RTL, lasso and layer editing | Around tenth on the independent boards; copyright cloud | BytePlus / Magnific |
| Midjourney v8 | Stylized art, illustration | Aesthetic baseline most artists prefer | Weaker on text in image | $10-$120/mo |
| Qwen-Image-2.1 | Best image model you can download | Highest-ranked open-weight model on both Arena boards: #18 image editing (1368.7) and #19 text-to-image (1222.9); #22 and #23 on the two Artificial Analysis boards, one place behind a newer open model on each; 7B generator, transparent PNGs, up to 10 reference images | Qwen Research License, research or evaluation only, no commercial use | Free download (Hugging Face) |
| Qwen-Image-3.0-Pro | Dense, text-heavy layouts | #13 Arena text-to-image (1255.2) and #17 Artificial Analysis text-to-image (1095); prompts up to 4.5k tokens, text in 12 languages | Hosted only, no weights; not rated on Arena image editing | Qwen Chat; $0.04-$0.075 per image in the API |
| Muse Image | Image editing, Meta ecosystem | #10 on Artificial Analysis image editing (1129) and #8 on its text-to-image board | Off the podium; #9 on Arena text-to-image and #8 on Arena editing | Meta AI app |
ChatGPT Images 2.5 keeps the image crown, and GPT-Image-2.5 Sunburst still leads all four boards we track. Since the last update Microsoft's MAI-Image-2.7-Preview, an editing-only preview released in October, has entered Artificial Analysis's editing board second at 1193, between Sunburst and Flare, which pushes MAI-Image-2.6 to fourth there, in a three-way tie at 1151 with Krea 3 (Ultra) and Nano Banana 2.1. The podium stays as it is, because MAI-Image-2.7-Preview has not been rated for making images from text, and both Arena boards still put MAI-Image-2.6 and Grok Imagine Image 2.0 narrowly ahead of Nano Banana 2.1.
Earlier this month Artificial Analysis moved both its image boards to v2.1, which re-scaled every score, Google released Nano Banana 2.1 on October 6 and it took Nano Banana 2's table row, Grok Imagine Image 2.0 took third place from Muse Image, and two new open models, Black Forest Labs' FLUX 3 Image Klein and Bria's Fibo 2.0, moved one place above Qwen-Image-2.1 on Artificial Analysis's boards. In September, Images 2.5 replaced GPT Image 2 at the top on September 8.
Best AI for Video
The best AI for video generation is MiniMax H3, which MiniMax released on July 31 with open weights, and the case for it is that it places near the top everywhere rather than winning one board outright.
It leads Arena's image-to-video board at 1495.4, ahead of Gemini Omni 1.1 Flash at 1488.5 and Alibaba's Wan 3.0 at 1479.8, and it is third on both of Artificial Analysis's boards with audio: 1158 on text-to-video and 1126 on image-to-video, where ByteDance's Dreamina Seedance 2.5 now leads at 1148. Its weak spot is Arena's text-to-video board, where it is eighth at 1460.3.
It makes 2K clips of 4 to 15 seconds with native stereo audio, from $0.13 a second at 2K, and the weights are on Hugging Face under MiniMax's own community licence, without the 2K upscaler and with an application required in the US, EU, UK and South Korea. Gemini Omni 1.1 Flash, our pick until this update, still leads Arena's text-to-video board at 1516.2, in a statistical tie with Gemini Omni Flash at 1512.9, and it is the pick for long takes: scene extension in 10-second steps to 40 seconds, first and last frame control and 4K output, from about $0.03 a second at 360p to $0.30 at 4K.
But on Artificial Analysis it comes only tenth on text-to-video at 1128 and ninth on image-to-video at 1044. Wan 3.0 leads Artificial Analysis's text-to-video board at 1174 and is third on Arena's image-to-video board, but only sixth on Arena's text-to-video board. If you need longer takes inside Google's tooling, Veo 3.1 still runs in the Gemini app, AI Studio and Vertex AI with native audio and 1080p output.
| Model | Best For | Strength | Weakness | Price |
|---|---|---|---|---|
| MiniMax H3 | Best AI video overall | #1 Arena image-to-video (1495.4) and #3 on both Artificial Analysis boards (1158 text-to-video, 1126 image-to-video); 2K clips of 4-15s with native stereo audio | #8 on Arena text-to-video (1460); the open weights exclude the 2K upscaler and need an application in the US, EU, UK and South Korea | $0.13/sec at 2K |
| Gemini Omni 1.1 Flash | Long takes and 4K | #1 Arena text-to-video (1516), #2 Arena image-to-video (1488.5); 40-second scene extension, 4K output | Only #10 on Artificial Analysis text-to-video (1128) and #9 on its image-to-video board (1044) | $0.03-$0.30/sec; Gemini API / AI Studio / Flow |
| Gemini Omni Flash | Cheaper 10-second clips | #2 Arena text-to-video (1513); conversational editing | Caps at 10-second generations | ~$0.10/sec; Gemini app / AI Studio |
| Wan 3.0 | Video from documents and slides | #1 Artificial Analysis text-to-video (1174), #3 Arena image-to-video (1479.8); 2-30s, up to 1080p, Omni-Reference input | API-only, no published weights; #6 on Arena text-to-video | $0.05-$0.20/sec |
| Dreamina Seedance 2.5 | ByteDance challenger | #1 Artificial Analysis image-to-video (1148), #5 Artificial Analysis text-to-video (1156), #4 Arena image-to-video (1477.4) | #7 Arena text-to-video (1474); ByteDance ecosystem, limited Western access | Dreamina / BytePlus |
| Muse Video | Meta ecosystem video | #9 on Arena text-to-video at 1456 | Newest of the group, thin tooling | Meta AI app |
| Veo 3.1 | Longer production clips | Native audio, 1080p, strong physics consistency | #12 on Arena video, not the quality leader | Google AI Pro / Ultra |
| Kling 3.0 / 3.0 Turbo | Fast iteration at lower cost | Native 4K, 60fps, 15-second clips; Turbo shipped June 17 | Outside the top 16 on Arena text-to-video | From $10/mo |
| Luma Ray 3 | Photoreal scenes | Strong realism for landscapes | Smaller community | Free / from $9.99/mo |
MiniMax H3 keeps the video crown, because it still places in the top four on three of the four boards we track and leads Arena's image-to-video board. Since the last update it has lost first place on Artificial Analysis's image-to-video board, where ByteDance's Dreamina Seedance 2.5 now leads at 1148, ahead of Seedance 2.0 at 1132 and H3 at 1126, and it has moved up to third on text-to-video at 1158. Seedance 2.5 does not take the crown, because it is only fourth on Arena's image-to-video board and seventh on text-to-video.
Earlier this month the crown moved from Gemini Omni 1.1 Flash to H3 once Artificial Analysis first rated Omni 1.1 Flash, Artificial Analysis added audio to its video boards, HeyGen Video 1 and fal's FLUX 3 Max entered them, and FLUX 3 Video and Grok Imagine Video 1.5 entered Arena's text-to-video board third and fourth. Omni 1.1 Flash still leads Arena's text-to-video board, in a statistical tie with Gemini Omni Flash, so it stays on the podium as the text-to-video pick, with Wan 3.0 third. In September, Gemini Omni 1.1 Flash held first place on Arena's text-to-video board and MiniMax H3 took first place on its image-to-video board.
Best AI for Coding
The best AI for coding is Claude Opus 5.5, which Anthropic shipped on September 22, though it no longer leads every board, and the model that took two of them is its own cheaper sibling.
Claude Sonnet 5.5, released September 28, leads LiveBench Coding at 91.4 against Opus 5.5's 89.3 and beats it on Artificial Analysis's own Terminal-Bench 4.0 run, 63.6% to 59.6%, though Moonshot's Kimi K3.1 Pro has led that run at 67.2% since October 23 and Google's Gemini 4 Carbon, which only cyber defenders can use, is second at 65.2%. Opus 5.5 keeps the crown on the rest of the evidence. It leads Arena's WebDev board at 1807, ahead of GPT-6 Astra at 1774 and Claude Sonnet 5.5 at 1769, and FrontierCode 2.0, the new coding test inside Intelligence Index v5, at 46.4% against Astra's 42.4% and Sonnet 5.5's 41.7%. It scores 71.7 on LiveBench Agentic Coding, second only to DeepSeek V4.1-Flash, where Sonnet 5.5 manages 56.3, and on Anthropic's own harnesses it beats Sonnet 5.5 on FrontierCode v1.1, 54.4% to 52.1%, and on CursorBench 4.0, 57.8% to 55.5%. On price the two are closer than they were.
Sonnet 5.5 is $2 / $10 per 1M tokens against Opus 5.5's $4 / $20, but on Intelligence Index v5 Artificial Analysis puts a max-effort task at $10.02 against Opus 5.5's $10.04, and Opus 5.5 at xhigh, 57.0 for $6.05 a task, now scores higher than Sonnet 5.5 at max, 54.2, for 60% of the cost; Sonnet 5.5 is cheaper only at lower settings, 41.1 for $1.64 at high. Opus 5.5 has also taken Arena's image-to-WebDev board at 1752.6, ahead of Sonnet 5.5 at 1737.1 and GPT-6 Astra at 1726.2; Astra matches Opus 5.5's 59.6% on Terminal-Bench 4.0 at xhigh, at $10 / $50, and Claude Fable 5.1 is fifth on WebDev and fourth on image-to-WebDev.
GPT-6.1 Sol is the cheap OpenAI option: fourth on WebDev, 56.1% on Terminal-Bench 4.0 and 54.5 on Intelligence Index v5 for $1.27 an index task at max effort, though LiveBench puts it well outside the top ten on Coding, at 80.7. GPT-6.1 Terra, released October 26, halves that token price to $1 / $5 and scores 51.0 for $0.96 a task, with 55.6% on Terminal-Bench 4.0. Gemini 4 Argon leads Google's own DeepSWE v1.1 table at 77.9%, but Artificial Analysis measures 57.1% on Terminal-Bench 4.0, Arena puts it eleventh on WebDev, and since October 13 it is on the paid API and in Antigravity for Google AI Ultra subscribers.
Claude Haiku 5.5, released October 7 at $0.10 / $0.50, is the cheap Claude for high-volume sub-agent work: 33% on Artificial Analysis's Terminal-Bench 4.0 run, level with GLM 5.3 Flash, and 57.2 on LiveBench Agentic Coding, just above Sonnet 5.5, though Arena puts it only 35th on WebDev. Among open weights, DeepSeek V4.1-Flash-1017, released October 17, has the highest open score on Intelligence Index v5, 32.5, and is the highest-placed open model on Arena WebDev, 14th at 1665, ahead of Kimi K3 in 17th; GLM-5.3 is still the strongest open model on Terminal-Bench 4.0 at 41.9%, and Xiaomi's MiMo-V2.6-Pro takes 34.8% there under plain MIT at $0.26 an index task.
Artificial Analysis has retired both its Coding Index and its Coding Agent Index, so the two composite coding rankings this page used to quote no longer exist.
| Model | Best For | Strength | Weakness | Price (per 1M tokens) |
|---|---|---|---|---|
| Claude Opus 5.5 | Best coding overall | #1 Arena WebDev (1807) and #1 FrontierCode 2.0 (46.4%); 58.4 on Intelligence Index v5, the highest of any model you can use; 71.7 LiveBench Agentic Coding, 15 points above Sonnet 5.5 | Behind Sonnet 5.5 on Terminal-Bench 4.0 (59.6% to 63.6%) and LiveBench Coding (89.3 to 91.4) | $4 / $20 |
| Claude Sonnet 5.5 | Value pick for coding | #1 LiveBench Coding (91.4), #3 Terminal-Bench 4.0 (63.6%) and #3 Arena WebDev (1769), at half Opus 5.5's token price | 56.3 LiveBench Agentic Coding, 15 points behind Opus 5.5; on Intelligence Index v5 Opus 5.5 at xhigh outscores it at max for less per task | $2 / $10 |
| GPT-6 Astra | Second on Arena WebDev | #2 Arena WebDev (1774) and #3 image-to-WebDev (1726.2); 59.6% Terminal-Bench 4.0 at xhigh | 2.5x Opus 5.5's price; behind Sonnet 5.5 on Terminal-Bench and well behind both Claude models on LiveBench Coding | $10 / $50 |
| Kimi K3.1 Pro | Strongest terminal coder | #1 Terminal-Bench 4.0 (67.2%); 46.0 on Intelligence Index v5 at $3.68 an index task | #8 Arena WebDev (1692); open weights promised for November 4, not yet published | $2 / $10 |
| Claude Fable 5.1 | Highest composite score before Opus 5.5 | #5 Arena WebDev and #4 image-to-WebDev; 49.7 on Intelligence Index v5; AA-Briefcase 1669 | 55.1% Terminal-Bench 4.0 at xhigh; 2.5x the price of Opus 5.5 | $10 / $50 |
| Claude Opus 5 | Superseded by Opus 5.5 | 49.0% Terminal-Bench 4.0 and #9 Arena WebDev and #7 image-to-WebDev | Costs more per token than Opus 5.5 and scored seven points lower on v4.3.2; not scored on Intelligence Index v5 | $5 / $25 |
| Claude Fable 5 | Hardest long-horizon agentic work | Intelligence Index 49.6 (v4.3.2); 42.4% Terminal-Bench 4.0; 1M context | The priciest per index task on v4.3.2 at $8.75; #10 on Arena image-to-WebDev | $10 / $50 |
| Qwen3.8-Max-0902 | Brief holder of Arena's WebDev board | #12 Code Arena: WebDev (1673); 33.6 on Intelligence Index v5; 2.4T parameters, 1M context | QwenCloud API only with no consumer front-end; lost the WebDev lead within days | $2 / $6 |
| DeepSeek V4.1-Flash-1017 | Strongest open model | 32.5 on Intelligence Index v5, the highest open score, at $0.60 a task; #14 Arena WebDev (1665) and #11 Agent Arena, the best open placements on both; MIT | 33.8% on Terminal-Bench 4.0; 552B/16B active to self-host | $0.15 / $0.60 off-peak |
| GPT-5.6 Sol | OpenAI's cheaper flagship | Intelligence Index 47.0 (v4.3.2); 39.9% Terminal-Bench 4.0 | Superseded by GPT-6 Sol, which scores higher at half the price; eval-gaming flagged by METR | $4 / $20 |
| GPT-6 Sol | Cheap GPT-6 coding in Codex | Intelligence Index 47.6 (v4.3.2) and 43.9% Terminal-Bench 4.0, both above GPT-5.6 Sol, at half its price | #10 Arena WebDev (1681) | $2 / $10 |
| GPT-6.1 Sol | Cheapest top-tier model per task | 54.5 on Intelligence Index v5, #4 Arena WebDev (1749) and 56.1% Terminal-Bench 4.0 at $1.27 an index task, or 50.2 for $0.59 at high effort; cached input at $0.10 | 80.7 on LiveBench Coding, well outside the top ten; in Codex and ChatGPT Work only, not in Chat | $2 / $10 |
| GPT-6.1 Terra | OpenAI's half-price coder | 51.0 on Intelligence Index v5 at $0.96 an index task; 55.6% Terminal-Bench 4.0; third among distinct models on FrontierCode 2.0 (42.3%) | In ChatGPT Work and Codex only, not in Chat; LiveBench has not rated it | $1 / $5 |
| Gemini 4 Argon | Long software tasks | 77.9% DeepSWE v1.1 on Google's own figures; 50.4 on Intelligence Index v5 | 57.1% Terminal-Bench 4.0 and #11 Arena WebDev (1674) | $2 / $10 intro to Nov 30, $4 / $20 standard |
| Gemini 4 Carbon | Not yet usable: long coding and cyber defense | 59.4 on Intelligence Index v5, the highest score published; #2 Terminal-Bench 4.0 (65.2%) | Cyber defenders and Fairwind partners only, no public date; sixth among distinct models on FrontierCode 2.0 (40.6%) | $2 / $10 intro, then $4 / $20 (announced) |
| Muse Spark 1.3 | Cheap agentic coding | Intelligence Index 48.1 (v4.3.2) at $1.25 / $4.25, and $1.60 per index task | 33.3% on Terminal-Bench 4.0; the coding wins come from Meta's own chart, measured on a partners-only max variant; not yet scored on v5 | $1.25 / $4.25 |
| Muse Wonder Full | Meta's strongest model, inside Muse Code | 49.7 on Intelligence Index v5, level with Claude Fable 5.1; #2 GDPval-AA v2.1 (1857); 57.1% Terminal-Bench 4.0 | Muse Code subscription only ($50 and $200 plans), no API; sixth on Arena WebDev (1726) | Muse Code, from $50/mo |
| Muse Wonder | Meta's frontier model on the API | 43.3 on Intelligence Index v5; 52.0% Terminal-Bench 4.0; 1M context | Same $4 / $20 as Opus 5.5, which scores 15.1 points higher; $6.95 an index task | $4 / $20 |
| Grok 4.7 | Cheap value coder | 46.3% CursorBench 4.0 and 71.0% DeepSWE v1.1 on SpaceXAI's own figures; 35.0 on Intelligence Index v5 | 24.7% on Terminal-Bench 4.0; $6.18 an index task; prompts of 200K tokens and up re-bill the whole request at double | $2 / $6 |
| Gemini 3.8 Flash | Agent coding at scale | 30.5 on Intelligence Index v5; 308.4 output tokens per second | 19.7% on Terminal-Bench 4.0; intro price doubles January 1, 2027 | $0.75 / $3.75 |
| GLM 5.3 Flash | Smallest serious coder you can host | 32.8% Terminal-Bench 4.0 at $0.28 an index task on v4.3.2 (not yet scored on v5); MIT, 320B/18B active, against 552B for DeepSeek V4.1-Flash | GLM-5.3 reaches 41.9% on the same harness; no consumer product | Open weights (MIT) |
| Claude Haiku 5.5 | Cheapest Claude for sub-agents | 36.2 on Intelligence Index v5 at $0.41 an index task; 32.8% Terminal-Bench 4.0, level with GLM 5.3 Flash; 57.2 LiveBench Agentic Coding, above Sonnet 5.5 | #35 Arena WebDev (1586); Anthropic says Sonnet 5.5 and Opus 5.5 remain better for complex agentic coding; prompts above 100K tokens cost five times as much | $0.10 / $0.50 |
| MiMo-V2.6-Pro | Cheapest strong open model per task | 29.9 on Intelligence Index v5 and 34.8% Terminal-Bench 4.0 at $0.26 an index task; MIT, 1.02T/42B active | Only #23 on Arena WebDev (1625), behind DeepSeek V4.1-Flash-1017 and Kimi K3 | $0.435 / $0.87 |
Claude Opus 5.5 keeps the coding crown: it still leads Arena's WebDev board at 1807, ahead of GPT-6 Astra at 1774 and Claude Sonnet 5.5 at 1769, and it leads FrontierCode 2.0 at 46.4%, the coding test Artificial Analysis added in Intelligence Index v5 on October 27. The same rescale moved the cost argument: Opus 5.5 at xhigh effort now outscores Sonnet 5.5 at max for less per task, so Sonnet 5.5's value case rests on LiveBench Coding, Terminal-Bench 4.0 and its half-price tokens. Since the last update Google's Gemini 4 Carbon has entered Terminal-Bench 4.0 second at 65.2%, but only cyber defenders can use it, and GPT-6.1 Terra arrived on October 26 at $1 / $5 with 55.6%.
Earlier this month Kimi K3.1 Pro took Terminal-Bench 4.0 at 67.2% from Sonnet 5.5, Claude Haiku 5.5 arrived on October 7 at $0.10 / $0.50 as the cheapest Claude for sub-agent work, DeepSeek V4.1-Flash-1017 became the highest-placed open model on WebDev, and Meta's Muse Wonder Full entered that board sixth. In September the crown moved twice, from Claude Fable 5.1 to GPT-6 Astra and then to Opus 5.5, and Claude Sonnet 5.5 took Terminal-Bench 4.0 and LiveBench Coding as the value pick.
Best AI for Creativity
The best AI for unfiltered, on-trend creative work is Grok 4.7, and we want to be exact about why. This pick is about the product line, not the prose quality.
Grok carries the fewest content restrictions of any frontier model and the only native real-time X integration, which makes it the one model that will engage with edgy, topical or deliberately provocative briefs that the others decline. SpaceXAI shipped Grok 4.7 on September 21 to the Grok API, Cursor and Grok Build, and since October 3 it also powers Expert mode on grok.com, plus Fast mode for paid subscribers. It is not the best writer, though the picture is more mixed than it was.
EQ-Bench has rated Grok 4.7 and puts it ninth at 2012.2, inside its top ten and far above Grok 4.5 in 57th, but Arena's human voters put 4.7 only 78th on creative writing, behind Grok 4.6 in 57th and the older Grok 4.20-beta1 in 25th. If you are picking on output quality alone, Claude Opus 5.5 now leads Arena's creative-writing board, with Gemini 4 Argon, on Google AI Pro since October 13, second and Claude Fable 5 third, while EQ-Bench puts GPT-6 Astra first at 2176.9, Moonshot's Kimi K3.1 Pro second and Claude Fable 5.1 third. Choose Grok for what it will let you make, not for how well it writes.
| Model | Best For | Strength | Weakness | Price |
|---|---|---|---|---|
| Grok 4.7 | Unfiltered, opinionated, on-trend | Fewest content restrictions, native real-time X grounding | #78 on Arena creative writing, though #9 on EQ-Bench (2012.2) | $2 / $6 API; $30/mo Premium app (X Subscription) |
| Claude Fable 5 | Highest-quality creative prose | #3 Arena creative writing, #1 LiveBench Language | Cautious guardrails on edgy briefs | $10 / $50 API |
| Kimi K3.1 Pro | Fiction and distinctive voice | #2 EQ-Bench Creative Writing at 2172.6 | Not yet rated on LiveBench; open weights promised for November 4 | $2 / $10 |
| Claude Opus 5 | Long-form structured creativity | Holds long threads and self-edits; 50.8 on Intelligence Index v4.3.2, not scored on v5 | Most cautious of the group | $20/mo Pro; $5 / $25 API |
| Gemini 3.1 Pro | Multimodal creative | Strong text, image and video chain | Needs Google AI Pro in the Gemini app since October 9 | AI Pro / $2.00-$4.00 API in |
| Grok Imagine (Spicy Mode) | NSFW / adult creative | Most permissive image generation | Niche use case | $30/mo Premium, most likely (xAI names no tier) |
Grok keeps this pick on Grok 4.7, and nothing about the product's permissiveness or its live X access changed, which is what the pick rests on. Since the last update EQ-Bench re-ran its board on October 28: it now puts 4.7 ninth, and Moonshot's Kimi K3.1 Pro entered second, which is why K3.1 Pro replaces Kimi K3 on the podium as the fiction pick. Earlier this month Claude Opus 5.5 took the lead on Arena's creative-writing board, with Gemini 4 Argon second and Claude Fable 5 third, Grok 4.7 slipped to 78th there, and on October 3 Grok 4.7 started powering Expert mode on grok.com. In September, Grok 4.7 replaced Grok 4.6 as SpaceXAI's flagship on September 21 and both creative-writing boards rated it.
Best AI for Accuracy & Research
The best AI for accuracy and research is Claude Fable 5.1, which holds the highest factual accuracy Artificial Analysis has measured, 68% on AA-Omniscience.
That is the exact column this category is decided on. Claude Opus 5.5 beat Fable 5.1 on almost everything else when it arrived on September 22, including Humanity's Last Exam at 61.4% to 59.1% and the hallucination-penalised AA-Omniscience index at 48.1 to 46.3, but on raw factual accuracy it reads 66% to Fable 5.1's 68%. Read the two together: Opus 5.5 is the better bet when a wrong answer is worse than no answer, Fable 5.1 when you want the most facts right. Google's Gemini 4 Carbon now leads that index at 53.5, but it answers only 58% correctly and only cyber defenders can use it.
The value pick is GPT-6.1 Sol, which answers 62% correctly with an AA-Omniscience index of 42.0 at $2 / $10 per 1M tokens and $1.27 an index task, and scores 98.5% on ARC Prize's ARC-AGI-1 for $0.06 a task. That beats Gemini 3.1 Pro, our value pick until early October, on every accuracy measure Artificial Analysis has published for it: it read 55% raw accuracy and an index of 31.9.
Gemini 3.1 Pro keeps its case where the answer has to be current, because it grounds answers in Google Search and is in the Gemini app (Google AI Pro and above since October 9), while GPT-6.1 Sol runs in ChatGPT Work, Codex and the API rather than in ChatGPT's chat window. Gemini 4 Argon is the model to watch: Artificial Analysis measures a 4% hallucination rate, the lowest among leading models, because it declines rather than guesses, but it answers only 48% correctly; since October 13 it is in the Gemini app on Google AI Pro and above.
On grounded search specifically, Arena's search leaderboard is led by OpenAI: GPT-5.6 Sol tops it at 1261, level with Qwen3.8-Max, with Claude Fable 5.1 fifth and Gemini 3.1 Pro grounding 15th. On novel reasoning the crown sits elsewhere, with GPT-6 Astra leading ARC-AGI-2 and ARC-AGI-3. Claude Opus 5 holds no accuracy crown because Artificial Analysis measures its hallucination rate at 61%.
| Model | Best For | Key Benchmark | Weakness | Price |
|---|---|---|---|---|
| Claude Fable 5.1 | Highest measured factual accuracy | 68% factual accuracy on AA-Omniscience, the highest Artificial Analysis has measured, three points above Claude Opus 5.5 | No cheap tier; unrated on Arena's search leaderboard; Opus 5.5 leads Humanity's Last Exam and Gemini 4 Carbon the AA-Omniscience index | $10 / $50 |
| Claude Opus 5.5 | When a wrong answer is worse than none | #1 Humanity's Last Exam (61.4%) and #2 AA-Omniscience index (48.1), behind only the cyber-defender-only Gemini 4 Carbon; 66% raw accuracy | Three points behind Fable 5.1 on raw accuracy | $4 / $20 |
| GPT-6.1 Sol | Best value | 62% raw accuracy and an AA-Omniscience index of 42.0 at $1.27 an index task; 98.5% ARC-AGI-1 at $0.06 a task | 52% hallucination rate; in ChatGPT Work and Codex, not in Chat | $2 / $10 |
| Gemini 4 Argon | Fewest hallucinations | 4% hallucination rate on AA-Omniscience, the lowest among leading models | Only 48% raw accuracy | $19.99/mo Google AI Pro; $2 / $10 API intro |
| Gemini 4 Carbon | Not yet usable | #1 AA-Omniscience index (53.5), with an 11% hallucination rate | 58% raw accuracy; cyber defenders and Fairwind partners only | Announced at $2 / $10 intro |
| Gemini 3.1 Pro | Grounded search; Gemini app on AI Pro from Oct 9 | Native Google Search grounding; 98% ARC-AGI-1 at $0.52/task | 55% raw accuracy on AA-Omniscience, below GPT-6.1 Sol; #15 on Arena search | $2.00-$4.00 / $12.00-$18.00 (tiered) |
| Claude Fable 5 | Grounded search | #5 on Arena's search leaderboard, behind GPT-5.6 Sol | No single cheap tier | $10 / $50 (Fable 5) |
| GPT-5.6 Sol | Novel reasoning | #4 ARC-AGI-2 at 92.5%, behind GPT-6 Astra (95%), GPT-6.1 Sol (94.2%) and Claude Opus 5.5 (93.3%) | Scheming flagged by METR | $4 / $20 |
| Claude Opus 5 | Hardest unseen problems | 30.2% ARC-AGI-3 on the standard harness, second to GPT-6 Astra (ARC Prize) | Artificial Analysis measures a 61% hallucination rate | $5 / $25 |
| Qwen 3.7 Max | Frontier accuracy at value pricing | 92.4 GPQA Diamond, 200 free requests/day | API-only, no chat front-end | $1.25 / $3.75 promo; $2.50 / $7.50 list |
| Claude Opus 4.6 | Honesty under pressure | #1 on Scale SEAL's MASK board at 96.28; Anthropic holds the top 5 | Superseded as a flagship | Legacy Anthropic model |
The accuracy crown stays with Claude Fable 5.1, at 68% raw factual accuracy against Claude Opus 5.5's 66%. Since the last update Artificial Analysis's AA-Omniscience figures have moved: Fable 5.1's accuracy now reads 68% rather than 67%, Opus 5.5's index 48.1 rather than 46.4, and Gemini 4 Argon's hallucination rate 4% rather than 15%. Google's Gemini 4 Carbon, announced October 28, takes the top of the index at 53.5 while answering only 58% correctly, so it would not take the crown even if people could use it. GPT-6.1 Sol stays the value pick, at $1.27 an index task on Artificial Analysis's re-measured costs.
Earlier this month GPT-6.1 Sol took the value card from Gemini 3.1 Pro, beating it on every accuracy measure Artificial Analysis publishes, and Gemini 4 Argon reached the Gemini app on October 13. Two older lines were corrected as well: Claude Opus 5's hallucination rate reads 61% rather than 50%, and it no longer leads ARC-AGI-3. In September, Opus 5.5 took the hallucination-penalised index and Humanity's Last Exam, which is why this block splits the two Claude models rather than crowning one outright.
Best AI for Problem Solving
The best AI for hard problem solving is GPT-6 Astra, which took the reasoning boards off GPT-5.6 Sol within days of launching.
It leads LiveBench Reasoning at 92.65 and ARC-AGI-2 at 95%, the highest anyone has scored against that board's 100% human panel, and sits fourth on LiveBench Mathematics at 96.81, behind Claude Opus 5.5 at 97.08, Claude Fable 5.1 at 97.01 and GPT-6.1 Sol at 96.83. It also reports 97.6% on FrontierMath Tier 4 v2, a number worth carrying with Epoch AI's disclosure that OpenAI funded the benchmark and holds exclusive access to part of it. The catch is price and reach: $10 / $50 per 1M tokens against GPT-6.1 Sol's $2 / $10, and it needs a paid ChatGPT plan.
GPT-6.1 Sol, released September 29, is the value alternative and very nearly a co-leader: 92.63 on LiveBench Reasoning, 0.02 behind Astra, and 94.2% on ARC-AGI-2, 0.8 points behind, for $0.25 a task against Astra's $1.12. Astra keeps the crown because it still leads both boards and ARC-AGI-3, where it scores 62.7% on the standard harness against GPT-6.1 Sol's 52.7%. Gemini 4 Argon leads Arena's math category, but on only a few hundred votes, and LiveBench has not rated it; ARC Prize puts it fifth on ARC-AGI-2 at 91.3% and third on ARC-AGI-3 at 49.8%. GPT-5.6 Sol, the old value pick, is now fifth on LiveBench Reasoning and fourth on ARC-AGI-2 at 92.5%.
Qwen 3.7 Max is the budget pick for competition-style problems at 97.1 on the February 2026 HMMT index and 44.5 on Apex, with 200 free model requests a day. Claude Opus 5 remains the alternative for long agentic reasoning chains, though Astra has taken ARC-AGI-3 from it as well.
| Model | Best For | Key Benchmark | Weakness | Price |
|---|---|---|---|---|
| GPT-6 Astra | Hardest math, science and reasoning | #1 LiveBench Reasoning (92.65), #1 ARC-AGI-2 (95%), #1 ARC-AGI-3 | Needs a paid ChatGPT plan; 5x GPT-6.1 Sol's price | $10 / $50 |
| Claude Opus 5 | Long agentic reasoning chains | 1657 on AA-Briefcase v1.1 and 1722 on GDPval-AA v2.1, seventh and eighth among distinct models; 30.2% ARC-AGI-3 | Astra now leads ARC-AGI-3; 61% hallucination rate; now a legacy model | $5 / $25 |
| GPT-5.6 Sol | Value STEM flagship | #4 ARC-AGI-2 (92.5%); #5 LiveBench Reasoning (91.65), Mathematics 96.20 | FrontierMath still unpublished; scheming flagged by METR | $100/mo ChatGPT Pro; API $4 / $20 |
| GPT-6.1 Sol | Value pick, near-Astra reasoning | #2 LiveBench Reasoning (92.63), #2 ARC-AGI-2 (94.2%), #3 LiveBench Mathematics (96.83); 54.5 on Intelligence Index v5 at $1.27 an index task | 52.7% on ARC-AGI-3 against Astra's 62.7%; in ChatGPT Work and Codex, not in Chat | $2 / $10 |
| Qwen 3.7 Max | Competition math on a budget | 97.1 HMMT 2026 Feb, 44.5 Apex, 200 free requests/day | API-only | $1.25 / $3.75 promo; $2.50 / $7.50 list |
| Claude Fable 5 | Math inside a coding workflow | #3 on Arena's math subcategory (1522), behind Gemini 4 Argon and Claude Opus 5; 96.0 LiveBench Mathematics | Priciest option here | $10 / $50 |
| GLM 5.3 Flash | Open-weight problem solving | Intelligence Index 41.8 (v4.3.2) under MIT, almost eight points above GLM-5.2 at less than half the size; 320B/18B active, 1M context | Needs a multi-GPU server, not a workstation; not yet scored on v5; GLM 5.3 scores higher on Z.ai's own figures and is downloadable since August 28, but at more than twice the size and under a bespoke licence | Open weights (MIT) |
GPT-6 Astra keeps the problem-solving crown, by less than a point. It still leads LiveBench Reasoning at 92.65, 0.02 ahead of GPT-6.1 Sol, ARC-AGI-2 at 95% against Sol's 94.2%, and ARC-AGI-3. Since the last update Google's Gemini 4 Carbon has taken the top of HLE-Diamond and Terminal-Bench-Science, two of the new tests in Artificial Analysis's Intelligence Index v5, at 69.1% and 64.8%, but LiveBench and ARC Prize have not rated it and only cyber defenders can use it, so the crown does not move. Earlier this month ARC Prize scored GPT-6.1 Sol second on ARC-AGI-2 and Gemini 4 Argon fifth at 91.3%, and Argon took Arena's math category on a few hundred votes. In September, Astra took this crown from GPT-5.6 Sol after its September 3 launch, and LiveBench Mathematics passed to Claude Opus 5.5.
Best AI Agent
The best AI agent is Gemini Spark if you want the agent in the cloud and Claude Cowork if you want it on your desktop.
These are joint picks rather than a first and a second: Spark runs in a Google Cloud VM, so it keeps working while your laptop is shut, wired into Gmail, Docs and, since early September, Google Photos; Cowork runs on your Mac or Windows machine and drives your local apps and your screen. Spark is no longer the only agent that keeps working in the cloud.
SpaceXAI's Grok Bot (August 11) gives each account a persistent cloud computer that signs into your apps, from a $30/month X Subscription Premium plan; Meta's Muse (September 8) runs errands from a cloud VM of its own and is free up to 100 million tokens a week; and OpenAI dots (September 29) run on GPT-6 Astra with their own cloud computer and browser, from the $100/month Pro plan, which does not include them in the EEA, UK or Switzerland. No independent board rates these products against each other, so the choice is about where the work has to happen rather than which one scores higher.
Price is no longer a tiebreaker either: Spark now reaches the $19.99/month Google AI Pro tier in the US and more than 160 other countries, and Cowork is included at no extra charge on every paid Claude plan from $20/month. ChatGPT Codex Mobile (May 14) is the alternative for coding-agent work. Read the full Gemini Spark vs Claude Cowork comparison.
| Agent | Best For | Where It Runs | Strength | Price |
|---|---|---|---|---|
| Gemini Spark | 24/7 cloud tasks, Workspace workflows | Google Cloud VM (always-on) | Always-on, deep Workspace integration | From $19.99/mo Google AI Pro |
| Claude Cowork | Desktop, app-driving, design + code | Your Mac/Windows desktop | Drives local apps, sees your screen | $20/mo Claude Pro |
| ChatGPT Codex Mobile | Coding agent on phone | OpenAI cloud + iOS/Android | Approve diffs and redirect work from phone | Included in ChatGPT plans |
| Grok Bot | Browser jobs across logged-in apps | One persistent SpaceXAI cloud computer shared by all your Bots | Signs into apps with your own logins and keeps going with your laptop closed | From $30/mo X Subscription Premium (Cursor Pro at $20 for existing subscribers) |
| OpenAI dots | Ongoing responsibilities, not one-off tasks | OpenAI cloud computer and browser | Runs on GPT-6 Astra; keeps working with your computer off; reachable in ChatGPT, Slack and by voice | From $100/mo ChatGPT Pro (not EEA/UK/CH); Business Premium |
| Meta Muse | Free personal errands | A Muse Secure VM in Meta's cloud | Free up to 100M tokens a week; a separate Sentinel agent approves what it sends out | Free; $20/mo Power, $100/mo Maximum |
| Claude Duet | Proactive daily briefings and errands | Its own cloud VM and browser, on iOS, Android and claude.ai | Checks your connected apps every few hours and works with your devices off; asks before it sends, pays, signs or deletes | Research preview, US Claude Pro and Max, waitlist |
Gemini Spark (cloud) and Claude Cowork (desktop) remain joint picks, because this category crowns products, and no new agent product has shipped since the last update. The model layer moved a little: on Artificial Analysis's AA-Briefcase v1.1, Claude Sonnet 5.5 leads at 1812 with Claude Opus 5.5 second at 1800, Opus 5.5 still leads GDPval-AA v2.1 at 1866, ahead of Meta's Muse Wonder Full at 1857 and Moonshot's Kimi K3.1 Pro at 1846, and Google's Gemini 4 Carbon, announced October 28, edges Gemini 4 Argon on AutomationBench-AA, 77.8% to 77.5%, though Argon is still the top model there that you can use. Earlier this month Anthropic's Claude Duet (October 21), a waitlisted research preview for US Pro and Max subscribers, joined the table rather than the podium, Claude Opus 5.5 took the top of Arena's Agent Arena with 21.4% confirmed success, and Argon reached the paid API and the Gemini app on Google AI Pro on October 13.
Among open models on the Agent Arena, DeepSeek V4.1-Flash-1017, released October 17, is now the highest at eleventh, ahead of Xiaomi's MiMo-V2.6-Pro at fourteenth, while Kimi K3 has slipped to 24th. In September, Grok Bot, Meta's Muse and OpenAI dots joined Gemini Spark as always-on cloud agents, and Spark reached the $19.99/month Google AI Pro tier.
Press ⌥ Space on your Mac, ask, and keep working. Also on iPhone and iPad.
Free to start, 4.7★ across 27,000+ reviews.
Download Fello AIBest AI for Students
The best AI for students is GPT-6 Luna inside ChatGPT for general coursework and Gemini 3.6 Flash for STEM and multimodal study, with Qwen 3.7 Max as the API alternative for harder problem sets (200 free requests a day) and Claude Sonnet 5.5 as the free alternative for essay editing.
Most students don't need to pay. Since October 8, ChatGPT Free and Go have been moving from GPT-5.6 Luna to GPT-6 Luna, which Artificial Analysis scored 38.1 on Intelligence Index v4.3.2 against 37.3; the free plan has unlimited text chats, while file uploads and image tools stay capped. Claude Sonnet 5.5 is free on claude.ai, where free accounts can also pick Claude Haiku 5.5 (October 7), the Claude model that uses the least of your usage limit.
Gemini changed on October 9: the free Gemini app now runs on Auto, which sends most prompts to Flash-Lite, so choosing Gemini 3.6 Flash yourself needs Google AI Plus, though it stays free in Google AI Studio. For step-by-step working on the hardest math, GPT-6 Astra reports 97.6% on FrontierMath Tier 4 v2 but is not on ChatGPT's free tier; Qwen 3.7 Max is the value alternative at 97.1 HMMT 2026 February with API pricing at $1.25 / $3.75 on its current 50% promo ($2.50 / $7.50 list).
| Task | Best Model | Why | Free? | Alternative |
|---|---|---|---|---|
| Essays & coursework | GPT-6 Luna | ChatGPT's Free and Go model, rolling out since October 8; unlimited text chats | Yes | Claude Sonnet 5.5 (free Claude) |
| STEM problem-solving | GPT-6 Sol / Qwen 3.7 Max | ChatGPT's paid default; Astra reports 97.6% FrontierMath Tier 4 v2 / 97.1 HMMT 2026 Feb | Plus paid / Qwen API paid | Gemini 3.6 Flash (AI Plus since Oct 9) |
| Research & accuracy | Gemini 3.1 Pro | 98% ARC-AGI-1 at $0.52/task, native Google Search grounding | AI Pro (Gemini app) since Oct 9 | Claude Opus 5 |
| Writing editing | Claude Sonnet 5.5 | Free on claude.ai since September 28 and fifth among distinct models on Intelligence Index v5 at max effort; Claude Fable 5.1 is the quality leader | Yes (Claude free) | Claude Fable 5.1 |
| Multimodal study (PDFs, slides, images) | Gemini 3.6 Flash | 1M context via AI Studio; Gemini app needs AI Plus since Oct 9 | Free in AI Studio | NotebookLM (Google) |
Two changes for students. ChatGPT's free model is moving from GPT-5.6 Luna to GPT-6 Luna, rolling out to Free and Go since October 8, so GPT-6 Luna takes the essays row. And since October 9 the free Gemini app runs on Auto, which sends most prompts to Flash-Lite, so picking Gemini 3.6 Flash in the app needs Google AI Plus.
Anthropic also released Claude Haiku 5.5 on October 7, which free Claude accounts can pick, and Claude Sonnet 5.5 is still free on claude.ai. Gemini 4 Argon, public since October 13, comes with Google AI Pro, so US students on Google's free year of AI Pro get it, while the free plan and the Google AI Plus student offer elsewhere do not. In September, Claude Sonnet 5.5 replaced Sonnet 5 as the free writing and editing pick.
Best AI for Work & Professionals
The best AI for professional work is GPT-6 (ChatGPT's default since October 7, Sol on paid plans) for daily knowledge work, Claude Opus 5.5 for coding and high-stakes writing, and Gemini Spark for 24/7 agentic workflows.
Most professionals get the most out of running two paid subscriptions (ChatGPT Plus at $20/month plus Claude Pro at $20/month, total $40/month). Or keep one bill: Fello AI covers ChatGPT, Claude and Gemini for everyday work. For agentic work that runs while you sleep, Gemini Spark is the always-on cloud agent that lives inside Google Workspace, and since July 30 it reaches the $19.99/month Google AI Pro tier as well as Google AI Ultra; OpenAI dots, Grok Bot and Meta's Muse are the alternatives, covered in the agents section above.
| Use Case | Best Model | Key Stat | Price | Alternative |
|---|---|---|---|---|
| Daily knowledge work | GPT-6 | ChatGPT's default since October 7; GPT-6 Sol on Plus | $20/mo ChatGPT Plus | Claude Opus 5.5 |
| Legal, finance & tax research | Gemini 4 Argon | #1 HLAB 1.1 (27.1%), Harvey's legal-agent test inside the Vals Index; #2 Finance Agent v2.1 (67.7%); #1 AutomationBench-AA (77.5%) among models you can use | $19.99/mo Google AI Pro | Claude Opus 5.5 |
| ChatGPT Work & Codex | GPT-6.1 Sol | In ChatGPT Work and Codex for Plus, Pro, Business, Enterprise and Edu since September 29, at $2 / $10 in the API | $20/mo ChatGPT Plus | GPT-6 Luna for volume work |
| Coding (proprietary) | Claude Opus 5.5 | #1 Arena WebDev (1807) and #1 FrontierCode 2.0 (46.4%), at $4 / $20 | $20/mo Claude Pro | Claude Sonnet 5.5, which leads LiveBench Coding at half the token price |
| Coding (cost-effective) | Claude Sonnet 5.5 | #1 LiveBench Coding (91.4) and #3 Terminal-Bench 4.0 (63.6%); $1.64 an index task at high effort | $2 / $10 | Kimi K3.1 Pro; DeepSeek V4.1-Flash-1017 |
| Research & briefings | Gemini 3.1 Pro | 98% ARC-AGI-1 at $0.52/task, Google grounding | Google AI Pro / Ultra | Claude Opus 5.5 |
| Hard math, physics, finance modelling | GPT-6 Astra | #1 LiveBench Reasoning and ARC-AGI-2 (95%); reports 97.6% FrontierMath Tier 4 v2 | $100/mo ChatGPT Pro | GPT-6.1 Sol; Qwen 3.7 Max |
| Always-on agent workflows | Gemini Spark | Always-on cloud agent inside Google Workspace | From $19.99/mo Google AI Pro | Claude Cowork |
| Live news, X-context creative | Grok 4.7 | 35.0 on Intelligence Index v5 + native X grounding; in the Grok app since October 3 | $30/mo Premium (X Subscription) | Gemini 3.1 Pro |
| All-in-one consolidation | Fello AI | ChatGPT + Claude + Gemini + Grok + DeepSeek | From $11.99/mo | Pay each vendor separately |
The daily knowledge work row stays with GPT-6, ChatGPT's default since October 7. Since the last update Vals re-ran its index on October 27: Claude Sonnet 5.5 still leads at 70.85%, Google's new Gemini 4 Carbon is second at 70.36% and Gemini 4 Argon fourth at 69.24%, and Vals no longer prints its note that Argon would rank first once fallback answers count as failures. Argon keeps the legal, finance and tax row on HLAB 1.1, where it leads at 27.1%, Finance Agent v2.1, where it is second to Claude Opus 5.5 by 0.2 points, and AutomationBench-AA, where only the not-yet-public Carbon scores higher, though it is now fifth on Vals Legal Research, which Carbon leads. The coding rows now cite FrontierCode 2.0 from Intelligence Index v5. Earlier this month Argon took the new legal, finance and tax row on October 13 and Kimi K3.1 Pro took Terminal-Bench 4.0 from Claude Sonnet 5.5. In September, Claude Opus 5.5 took the proprietary coding row at a lower price than Opus 5, Claude Sonnet 5.5 took the cost-effective coding row, and GPT-6.1 Sol took the ChatGPT Work and Codex row on September 29.
AI Model Pricing in October 2026
From $0 free tiers to $199.99/month Google AI Ultra. The price that matters most on this table is Claude Opus 5.5 at $4 / $20: the highest-scoring model you can use on Artificial Analysis's Intelligence Index v5 costs less than the Claude Opus 5 it replaced ($5 / $25), and cache reads fall 60% to $0.20. Claude Fable 5.1 and GPT-6 Astra both list at $10 / $50 and both score below it. Google's Gemini 4 Carbon scores a point higher at an announced $2 / $10 introductory rate, but so far only cyber defenders can use it.
The busiest rate is now $2 / $10, shared by Claude Sonnet 5.5, GPT-6 Sol, GPT-6.1 Sol and Moonshot's Kimi K3.1 Pro, which scores 46.0 at $3.68 an index task. GPT-6.1 Sol is still the cheapest route past 50 on the index, at $0.59 an index task for 50.2 at high effort, or $1.27 for 54.5 at max, and OpenAI's GPT-6.1 Terra (October 26) halves the token price to $1 / $5 for 51.0 at $0.96. With Sonnet 5.5 the effort setting decides the bill: an index task costs $1.64 at high effort and $10.02 at max, level with Opus 5.5's $10.04, and Anthropic halved its cache reads to $0.10 on October 7. Google's Gemini 4 Argon also starts at an introductory $2 / $10 ($4 / $20 standard), until November 30, and since October 13 anyone on the paid API can buy it.
Token price and task cost can drift apart. Grok 4.7 lists at $2 / $6, yet an index task costs $6.18 for a score of 35.0, because it writes so much output. Mistral Large 4 (public preview since October 6) lists at $1.36 / $4.18, though Mistral's own model page shows half that, and it is verbose enough that an index task costs $5.54 for a score of 25.3. Meta's Muse Spark 1.3 at $1.25 / $4.25 was the frontier value pick on v4.3.2, at $1.60 an index task for 48.1, and Artificial Analysis has not yet scored it on v5.
At the cheap end, GPT-6 Luna is the cheapest model per task on this page: $0.10 / $0.50, or $0.15 an index task for 27.8 at max effort. Claude Haiku 5.5 (October 7) matches that token price on prompts up to 100,000 tokens and scores 36.2 to Luna's 27.8, but it writes so much more that an index task costs $0.41 at max effort, or $0.25 for 34.3 at xhigh; above 100,000 tokens it rises to $0.50 / $2.50. Among open models sold by the token, DeepSeek V4.1-Flash-1017, the build DeepSeek's API has served since October 17, is the pick at $0.15 / $0.60 off-peak and $0.30 / $1.20 at peak ($0.60 an index task for 32.5, the highest open score on v5), while GLM 5.3 Flash at $0.15 / $0.50 has not yet been scored on v5. Xiaomi's MiMo-V2.6-Pro is cheaper per task at $0.26 for 29.9, but only if you host its 1.02 trillion parameters yourself. For a deeper breakdown see our full AI Pricing Comparison Guide.
| Model | Input (per 1M) | Output (per 1M) | Context | Free Access? |
|---|---|---|---|---|
| GPT-6 Astra | $10.00 | $50.00 | 1,050,000 (922,000 max input) | In Chat on Pro, Business and Enterprise since September 4; Plus gets it in ChatGPT Work and Codex rather than Chat; no free tier; live in the API |
| GPT-6 Sol | $2.00 | $10.00 | 1,050,000 (922,000 max input) | ChatGPT Chat on Plus, Pro, Business and Enterprise since October 7; Work & Codex; API |
| GPT-6.1 Sol | $2.00 | $10.00 | 1,050,000 (922,000 max input) | ChatGPT Work & Codex on Plus, Pro, Business, Enterprise and Edu since September 29; API; not in Chat; cache reads $0.10 |
| GPT-6.1 Terra | $1.00 | $5.00 | 1,050,000 (922,000 max input) | ChatGPT Work & Codex on Plus, Pro, Business, Enterprise and Edu since October 26; API; not in Chat; cache reads $0.05 |
| GPT-6 Luna | $0.10 | $0.50 | 1,050,000 (922,000 max input) | ChatGPT Chat on Free and Go, rolling out since October 8; Work & Codex on paid plans; API |
| GPT-5.5 | $5.00 | $30.00 | 1M (400K in Codex) | ChatGPT Free; API paid |
| GPT-5.5 Pro | $30.00 | $180.00 | 1M | ChatGPT Pro from $100/mo ($200 and $500 higher-usage tiers) |
| GPT-5.6 Sol | $4.00 | $20.00 | Not published | Live in ChatGPT, Codex & API (July 9); promotional rate through at least November 21, 2026 |
| GPT-5.6 Terra | $2.00 | $12.00 | Not published | Live in ChatGPT, Codex & API (July 9) |
| GPT-5.6 Luna | $0.20 | $1.20 | Not published | Live in ChatGPT, Codex & API (July 9) |
| Claude Opus 5.5 | $4.00 | $20.00 | 1M | Claude Pro/Max/Team; API paid; cache reads $0.20 |
| Claude Opus 5 | $5.00 | $25.00 | 1M | Legacy model at Anthropic; Pro/Max/API |
| Claude Opus 4.8 | $5.00 | $25.00 | 1M | Legacy model at Anthropic; Pro/Max/API |
| Claude Fable 5.1 | $10.00 | $50.00 | 1M | Cache reads $0.25; in Max/Team Premium (~50% of usage limits); Pro/Team Standard via credits. Mythos 5.1 bills identically, by invitation only |
| Claude Fable 5 | $10.00 | $50.00 | 1M | Permanent in Max/Team Premium (~50% of usage limits); Pro/Team Standard via credits |
| Claude Sonnet 5.5 | $2.00 | $10.00 | 1M | Free on claude.ai; Pro/Max/Team; API paid; cache reads $0.10 since October 7 |
| Claude Sonnet 5 | $2.00 | $10.00 | 1M | Legacy model since September 28; the fallback for flagged cyber requests; API paid |
| Claude Sonnet 4.6 | $3.00 | $15.00 | 1M | API paid (superseded by Sonnet 5) |
| Claude Haiku 5.5 | $0.10 (≤100K) / $0.50 (>100K) | $0.50 (≤100K) / $2.50 (>100K) | 1M | Free, Pro, Max, Team and Enterprise on Claude.ai (web, iOS, Android); API paid; cache reads $0.01 |
| Gemini 3.1 Pro | $2.00 (≤200K) / $4.00 (>200K) | $12.00 (≤200K) / $18.00 (>200K) | 1M | Gemini app on Google AI Pro and above since Oct 9; API paid |
| Gemini 4 Argon | $2.00 intro to Nov 30 / $4.00 standard ($0.10 cached, intro) | $10.00 intro / $20.00 standard | 1M, shared by input and output | Paid API since October 13; Gemini app on Google AI Pro and Ultra |
| Gemini 4 Carbon | $2.00 intro / $4.00 later (announced) | $10.00 intro / $20.00 later | Not published | Announced October 28; cyber defenders and Fairwind partners only, no date for the public API or the Gemini app |
| Gemini 3.8 Flash | $0.75 intro / $1.50 from Jan 1, 2027 | $3.75 intro / $7.50 from Jan 1, 2027 | 1M | AI Studio, Antigravity, Gemini Enterprise + paid API; in the Gemini app reported for AI Pro/Ultra |
| Gemini 3.7 Flash | $0.75 intro / $1.50 from Jan 1, 2027 | $3.75 intro / $7.50 from Jan 1, 2027 | 1M | AI Studio, Android Studio, Antigravity + paid API; in the Gemini app via Spark only (AI Pro/Ultra, excludes EEA/UK/CH/Nigeria) |
| Gemini 3.6 Flash | $0.75 intro / $1.50 from Jan 1, 2027 | $3.75 intro / $7.50 from Jan 1, 2027 | 1M | Gemini app on AI Plus and above since Oct 9; AI Studio; free API tier + paid API |
| Gemini 3.5 Flash-Lite | $0.30 | $2.50 | 1M | AI Studio; free API tier + paid API |
| Qwen3.8-Max-0902 | $2.00 ($0.17 explicit cache hit, $0.25 implicit) | $6.00 | 1M (128K output) | QwenCloud API only; no consumer chat front-end; open weights only as the text-only Qwen3.8-2.4T-A95B it is built on |
| Qwen 3.7 Max | $1.25 promo / $2.50 list | $3.75 promo / $7.50 list | 1M | 200 free requests/day; API paid beyond that |
| MiniMax M3 | $0.30 (50% off $0.60) | $1.20 (≤512K) | 1M | Open weights; hosting costs apply |
| LongCat-2.0 | Provider-dependent | Provider-dependent | 1M | Open weights (MIT); hosting costs apply |
| NVIDIA Nemotron 3 Ultra | Provider-dependent | Provider-dependent | 1M | Open weights (OpenMDW); hosting costs apply |
| Qwen 3.5 (open-weight) | Self-host / Together | Self-host / Together | 1M | Open weights; hosting costs apply |
| Nex-N2-Pro | Self-host / providers | Self-host / providers | 1M | Open weights (Apache 2.0); hosting costs apply |
| Rio 3.5 Open 397B | Self-host / providers | Self-host / providers | 1M | Open weights (MIT); hosting costs apply |
| Grok 4.3 | $1.25 | $2.50 | 1M | Free consumer plan; API paid |
| Grok 4.6 | $2.00 (<200K) / $4.00 (≥200K) | $6.00 (<200K) / $12.00 (≥200K) | 500K | SpaceXAI API, Cursor, Grok Build, OpenRouter, Vercel, Cloudflare |
| Grok 4.7 | $2.00 (<200K) / $4.00 (≥200K) | $6.00 (<200K) / $12.00 (≥200K) | 500K | SpaceXAI API, Cursor, Grok Build, harnesses and cloud routers; Grok app Expert mode since October 3 |
| Muse Spark 1.3 | $1.25 ($0.10 Contributor tier) | $4.25 ($0.20 Contributor tier) | 1M | Paid API; Muse Code, Meta Model API and OpenRouter; Contributor tier trades training rights for a ~92% discount |
| Muse Wonder | $4.00 | $20.00 | 1M | Paid API; Meta Model API, Muse Code and OpenRouter; Muse Wonder Full is only in Muse Code, on the $50 and $200 plans |
| Kimi K3 | $3.00 ($0.30 cache-hit) | $15.00 | 1M | Free basic tier in the Kimi app; open weights on Hugging Face (Kimi K3 License) |
| Kimi K3.1 Pro | $2.00 ($0.20 cache-hit) | $10.00 | 1M | Kimi.com, Kimi apps, Kimi Work, Kimi Code and the Kimi API since October 23; open weights promised by November 4; Highspeed variant at twice the price |
| Mistral Large 4 | $1.36 ($0.68 on Mistral's model page) | $4.18 ($2.09) | 512K (1M per Mistral) | Public preview API since October 6; open weights promised by the end of October, no licence named yet |
| Gemini Omni Flash (video) | $1.50 | $17.50 (video output) | 10-second clips | Gemini app / Flow; AI Studio + API |
| DeepSeek V4-Pro | $0.66 off-peak / $1.32 peak ($0.022 cache-hit off-peak) | $1.98 off-peak / $3.96 peak | 1M | DeepSeek Chat free; API paid, peak/off-peak tiers since August 16 |
| DeepSeek V4.1-Flash-1017 | $0.15 off-peak / $0.30 peak ($0.003 cache-hit off-peak) | $0.60 off-peak / $1.20 peak | 1M | DeepSeek Chat free; API paid, peak/off-peak tiers; 1017 build since October 17 at the same prices |
| Kimi K2.7 Code | Provider-dependent | Provider-dependent | 256K | Open weights; hosting costs apply |
| GLM-5.2 | Provider-dependent | Provider-dependent | 1M | Open weights; hosting costs apply |
| GLM 5.3 | $1.40 ($0.26 cache-hit) | $4.40 | 1M | Z.ai API, GLM Coding Plan and ZCode; weights on Hugging Face since August 28 under the bespoke GLM 5.3 License |
| GLM 5.3 Flash | $0.15 ($0.03 cache-hit) | $0.50 | 1M | Z.ai API, GLM Coding Plan, OpenRouter; MIT weights on Hugging Face; the launch promotion ended September 9 |
| Tencent Hy4 Preview | $0.834 ($0.042 cache-hit) | $2.501 | 1M+ | Open weights (Apache 2.0); Tencent Cloud TokenHub, OpenRouter, WorkBuddy, CodeBuddy |
| Qwen3.8-Flash-Next | Provider-dependent | Provider-dependent | 262K (to 1M) | Open weights (Qwen Community License 1.0); hosting costs apply |
| MiMo-V2.6-Pro | $0.435 | $0.87 | 1M | Open weights (MIT); hosting costs apply |
| ERNIE 5.1 | China-region pricing | China-region pricing | 256K | Baidu free tier |
| Gemini Spark (agent) | Not API-priced | Not API-priced | 1M (Gemini base) | Google AI Pro $19.99, AI Ultra $99.99 or $199.99/mo |
| Fello AI (aggregator) | Routed via app | Routed via app | Model-dependent | From $11.99/mo, free tier available |
The GPT-5.5 and GPT-5.5 Pro rates above are short-context prices; OpenAI no longer publishes the specific long-context figures. The GPT-5.6 tiers are billed at 2x input and 1.5x output once a prompt passes 272K input tokens, which puts long-context Terra at $4 / $18 and Luna at $0.40 / $1.80. The GPT-6 tiers carry the same surcharge past 272K input tokens, applied to the whole request, and their cached input reads are 90% off: $1.00 for Astra, $0.20 for GPT-6 Sol and $0.01 for Luna, with GPT-6.1 Sol at 95% off, $0.10.
Grok 4.6 works the same way but bites harder: at 200,000 prompt tokens and above, SpaceXAI re-bills the entire request at the higher rate rather than only the overage, so crossing the line by a thousand tokens doubles the cost of the whole call. DeepSeek is the other rate card that needs reading twice: since August 16 both V4 models bill at peak rates from 01:00 to 04:00 and from 06:00 to 10:00 UTC on weekdays, and at exactly half that in every other hour, so the same job can cost twice as much depending on when you run it.
The cheapest way through this table is often one subscription instead of three. Fello AI puts GPT, Claude, Gemini, Grok, Perplexity and more in a single app for Mac, iPhone and iPad, from $11.99 a month in most countries.
Best Open-Weight Models in October 2026
The best open-weight model in October 2026 is DeepSeek's V4.1-Flash-1017, released on October 17 under MIT: 552 billion parameters, with 8 billion active at prefill and 16 billion at decode, and a 1M-token context. Artificial Analysis scores it 32.5 on its new Intelligence Index v5, the highest score of any model with published weights, ahead of GLM-5.3 at 31.7 and Xiaomi's MiMo-V2.6-Pro at 29.9, and it is also the highest-placed open model on Arena, 14th on WebDev and 11th on the Agent Arena. It costs $0.15 / $0.60 per 1M tokens off-peak, or $0.60 an index task.
Two other open models still lead somewhere. Xiaomi's MiMo-V2.6-Pro, published on September 21 under plain MIT, is the cheapest strong open model per task at $0.26, and it led this ranking until Intelligence Index v5 re-scaled the board on October 27. GLM-5.3 is the strongest open model on Terminal-Bench 4.0 at 41.9%, though on a bespoke Z.ai licence rather than MIT.
Two October releases sit just outside this ranking. Moonshot's Kimi K3.1 Pro (October 23) scores 46.0, 13.5 points above DeepSeek V4.1-Flash-1017, but Moonshot has only promised its weights for November 4, so until they are on Hugging Face it is a closed model. MiniMax-M3.1-Flash, whose weights are on Hugging Face under MiniMax's community licence, scores 28.9 from 428B total and 23B active parameters at $0.49 an index task, a little cheaper per task than DeepSeek V4.1-Flash-1017 but 3.6 points lower.
For teams running their own weights, the practical pick is still GLM 5.3 Flash (Z.ai, MIT): 41.8 on v4.3.2 from 320B total and 18B active, and not yet scored on v5. It is a separate model on a newly trained base, not a trimmed GLM 5.3, which is why it ships under MIT. A 1.02-trillion-parameter model is not a workstation proposition, and the K3 download alone is about 1.56 TB. DeepSeek-V4.1-Flash-1017 replaced the September V4.1-Flash build on October 17 at unchanged prices: MIT, natively multimodal, and $0.15 / $0.60 off-peak.
Four more are worth watching. Mistral Large 4 (public preview since October 6) is the highest-scoring model from the US or Europe that promises open weights, at 25.3 on v5, but you cannot download it yet: Mistral said the weights would follow by the end of October and has not named a licence. Alibaba's Qwen3.8-Flash-Next, 125B with only 6B active, previews the Qwen4 architecture and scored 39.8 on v4.3.2. Tencent's Hy4 Preview, 770B total and 49B active under Apache 2.0, has no Artificial Analysis rating but sits 21st on Arena WebDev. Meta's Muse Spark Open, released October 15 at 816B total and 42B active, scores 24.7 on v5 under Meta's own Muse Model License rather than an open-source licence.
| Model | Best For | Key Benchmark | Context / License | Where To Run |
|---|---|---|---|---|
| DeepSeek V4.1-Flash-1017 | Best open model, and the best open value sold by the token | II 32.5 (v5.0), the highest open score, at $0.60 an index task; top open model on Arena WebDev and the Agent Arena; 552B, 8B active at prefill and 16B at decode | 1M / MIT | DeepSeek API ($0.15/$0.60 off-peak, $0.30/$1.20 peak), local |
| Kimi K3 | Largest open model on this page | II 43.6 (v4.3.2); #17 Arena WebDev and #24 Agent Arena; 2.8T/104B active | 1M / Kimi K3 License | Hugging Face (96 shards, 1.56 TB), Moonshot API, providers |
| GLM 5.3 Flash | Best open model most teams can actually run | II 41.8 (v4.3.2) at about $0.28 an index task, the smallest of the leading open models; 320B/18B active, natively multimodal | 1M / MIT | Hugging Face, Z.ai API ($0.15/$0.50), OpenRouter |
| GLM-5.2 | Fallback with an independent track record | II 33.7 (v4.3.2); #31 Arena WebDev (1,604.3), #23 Agent Arena; 744B/40B active | 1M / MIT | Z.ai, Hugging Face, OpenRouter |
| GLM 5.3 | Open since August 28, but on a bespoke licence | II 31.7 (v5.0), second among open models; same 744B base as GLM-5.2, post-trained only, published checkpoint counted at 753B; CyberGym 84.5% and Terminal-Bench 3.0 28.3 (vendor figures) | 1M / GLM 5.3 License (MaaS above $10B revenue needs a Z.ai security review) | Hugging Face, Z.ai API ($1.40/$4.40), GLM Coding Plan, ZCode |
| MiMo-V2.6-Pro | Cheapest strong open model per task | II 29.9 (v5.0), third among open models, at $0.26 an index task; 34.8% Terminal-Bench 4.0; GDPval-AA v2.1 1691; 1.02T/42B active | 1M / MIT | Hugging Face (XiaomiMiMo), providers, self-host |
| MiniMax-M3.1-Flash | Cheap open coder and agent | II 28.9 (v5.0) at $0.49 an index task; 428B/23B active, text, image and video input; #34 Arena WebDev (1589) | 1M / MiniMax Community License | Hugging Face, MiniMax, self-host |
| Tencent Hy4 Preview | Largest permissively licensed model yet | 770B/49B active; 2.99/4.00 on Tencent's own 203-task expert panel vs Kimi K3 2.94 and GLM 5.3 2.92 (vendor); no Artificial Analysis rating; #21 Arena WebDev (1631), #22 Agent Arena | 1M+ / Apache 2.0 | Hugging Face (BF16 and FP8), Tencent Cloud TokenHub, OpenRouter |
| Qwen3.8-Flash-Next | Preview of the Qwen4 architecture | 125B total plus a 51B N-gram embedding, 6B active; 91.7 GPQA Diamond and 62.5 SWE-Bench Pro (vendor); II 39.8 (v4.3.2); #22 Arena WebDev (1629) | 262K to 1M / Qwen Community License 1.0 | Hugging Face, providers, self-host |
| LongCat-2.0 | Frontier open coder trained on Chinese chips | II 33 (v4.1); 59.5% SWE-Bench Pro (vendor), 1.6T/~48B active | 1M / MIT | Hugging Face, GitHub, OpenRouter |
| MiniMax M3 | Cheap long-context multimodal | II 18.7 (v5.0; 29.2 on v4.3.2), 59% SWE-Bench Pro, multimodal | 1M / MiniMax Community License | Hugging Face, API $0.30/1M (50% off) |
| Nex-N2-Pro | Strongest open coding score | II 41 (v4.1); 80.8 SWE-Bench Verified, 397B/17B active | Qwen-based / Apache 2.0 | Hugging Face, providers, self-host |
| Kimi K2.7 Code | Strongest commercially-licensed open coder | +21.8% on Kimi Code Bench v2 vs K2.6 (vendor); 1T/32B active | 256K / Modified MIT | Hugging Face, DeepInfra, providers |
| DeepSeek V4-Pro | Agentic real-world work | II 44 (v4.1), 1.6T/49B active | 1M / MIT | DeepSeek API ($0.66/$1.98 off-peak, $1.32/$3.96 peak since August 16), local |
| Hy3 | Newest permissive-licence entrant | II 41 (v4.1); #62 on Arena WebDev (1,506.1) | Apache 2.0 | Hugging Face, providers, self-host |
| Inkling | Thinking Machines' first open model | II 41 (v4.1), agentic 32.3, released July 15 | Open weights | Hugging Face, providers, self-host |
| Inkling Small | Same family at a quarter the size | II 40 (v4.1), agentic 30.8; 276B/12B active, text, image and audio in | Apache 2.0 | Hugging Face (BF16 and NVFP4), providers, self-host |
| NVIDIA Nemotron 3 Ultra | NVIDIA-tuned, fully permissive license | II 38 (v4.1), 65-70.4 SWE-Bench Verified, 550B/55B active | 1M / OpenMDW | OpenRouter, Hugging Face, AWS (8x B200 self-host) |
| Qwen 3.5 (397B / 17B active) | Multimodal, fast decode | 88.4 GPQA, 91.3 AIME 2026, 83.6 LiveCodeBench v6 | 1M / open | Together, OpenRouter, local |
| Qwen3.6-35B-A3B | Efficient open agentic coder (3B active) | 86.0 GPQA Diamond, 92.7 AIME 2026, 35B/3B active | 262K (to 1M YaRN) / Apache 2.0 | Hugging Face, OpenRouter, local |
| Qwen3.6-27B | Laptop-runnable dense coder | 87.8 GPQA Diamond, dense 27B, multimodal | 256K / Apache 2.0 | Local Mac/PC, Hugging Face, OpenRouter |
| Rio 3.5 Open 397B | Qwen 3.5 fine-tune, multilingual reasoning | 70.8 Terminal-Bench 2.1 (first-party), beats Qwen 3.7 Plus on 4/5 | 397B/17B active / MIT | Hugging Face, providers, self-host |
| Llama 4 Maverick | Meta-line flagship | 17B active / 400B total params | Llama 4 license | Meta cloud, Hugging Face, local |
| NVIDIA Nemotron 3 Nano Omni | Edge / low-power | Multimodal, very small footprint | Compact / open | Local, NVIDIA tool |
Licensing matters as much as raw score here, and August widened the gap between the two groups. Kimi K2.7 (Modified MIT), DeepSeek V4 (MIT), GLM 5.3 Flash (MIT), MiMo-V2.6-Pro (MIT), GLM-5.2 (MIT), LongCat-2.0 (MIT), Hy3 (Apache 2.0), Hy4 Preview (Apache 2.0), Nex-N2-Pro (Apache 2.0) and Nemotron 3 Ultra (OpenMDW) all clearly allow commercial use with no revenue test.
The rest carry conditions worth reading before you build on them: MiniMax M3, MiniMax-M3.1-Flash and MiniMax H3 ship under their own community licences, H3 additionally requiring an application from the US, EU, UK and South Korea; Kimi K3 sits on a custom licence with a revenue threshold for anyone reselling it as a service; GLM 5.3 requires a Z.ai security review of any model-as-a-service operator above $10 billion in revenue; and the Qwen Community License 1.0 on Qwen3.8-Flash-Next requires a separate licence from Qwen to run a model-as-a-service or an AI work-assistant business, though internal use is exempt. No open model is first on any Arena board we track any more: Claude Opus 5 took the Agent board in July, the last one an open model led.
Benchmarks, Prices, and Hands-On Use
Every ranking on this page combines three inputs: public benchmarks from seven independent houses (Artificial Analysis, Arena formerly LMArena, Scale SEAL, LiveBench, EQ-Bench, ARC Prize and the official Terminal-Bench 4.0 board, covering the Intelligence Index, GPQA Diamond, ARC-AGI-1 through 3, Humanity's Last Exam, GDPval-AA, FrontierMath, HMMT, MCP Atlas, SWE Atlas and the Remote Labor Index), published API and subscription pricing from each vendor's official pricing page, and hands-on use by the FelloAI editorial team running real prompts across the same task on every model. We re-fetch official pricing and benchmark sources before every monthly update.
Benchmarks are weighted to the use case: SWE-bench and Terminal-Bench drive coding, GPQA Diamond and ARC-AGI-2 drive accuracy, GDPval-AA (Artificial Analysis's professional-deliverables benchmark) informs professional-task quality while writing style is judged primarily by hands-on testing, FrontierMath and HMMT drive problem-solving. We disclose when a benchmark is vendor-reported but not independently verified, and we strip any claim we cannot reproduce against a live source. We rank on measured scores: a category crown moves as soon as a model out-scores the holder on the boards that define that category, without waiting for the vote-based boards to catch up, and a model that is not yet widely available is flagged on its card rather than denied one. We re-check ranks as well as figures, because a score can stay correct while the board around it moves. When a model goes through a major upgrade between updates, we re-rank the category and add a "What changed this month" line at the bottom of the deep-dive.
Ask ChatGPT, Claude and Gemini and keep the best answer. No three bills.
Fello AI runs on Mac, iPhone and iPad, free to start.
Download Fello AI