On July 8, 2026, xAI released Grok 4.5, its first model built specifically for coding and agentic work. This is not a general capability upgrade. It is a deliberate pivot toward developers, with training done using real Cursor developer session data and benchmarks designed to measure what an AI can actually do inside a real codebase over a long session. It was superseded on August 12, 2026 by Grok 4.6, a post-training upgrade on the same foundation. Grok 4.6 in turn gave way to Grok 4.7 on September 21, 2026, and Artificial Analysis now lists Grok 4.5 as deprecated.
The result is a model that scores 38.8 on Artificial Analysis Intelligence Index v4.3.2, at a fraction of what Anthropic’s frontier costs to run. Artificial Analysis spends $1.04 putting Grok 4.5 through the index, against $5.98 for Anthropic’s current Claude Opus 5.5 at max reasoning. OpenAI has closed that gap, though: GPT-6.1 Sol runs the same index for $0.72 at max reasoning and scores 51.8. Our guide to AI benchmarks explains what those scores actually measure.
Elon Musk positioned it directly: “It is an Opus-class model, but faster, more token-efficient and lower cost.” In a follow-up he was more precise: “Grok 4.5 is roughly comparable to Opus 4.7, but much faster.”
Musk has also flagged that current speeds are not the ceiling. xAI has not yet deployed its internally developed C/C++ inference stack that maps directly to the GB300 hardware, and when it does, he expects speeds to double or more. He signalled a further step-change release for the following month, and it arrived twice over: Grok 4.6 on August 12, 2026, then Grok 4.7 on September 21, 2026. grok-4.5-latest is no longer the front of xAI’s model list.
The Key Takeaways
- Grok 4.5 launched July 8, 2026 and scores 38.8 on Artificial Analysis Intelligence Index v4.3.2. It ranked 4th of 168 entries at launch and now sits 56th of 664.
- Built on the 1.5-trillion-parameter V9 foundation and trained on real Cursor session data for coding and agentic tasks.
- Priced at $2 / $6 per million tokens with cached input at $0.30, against $4 / $20 for Claude Opus 5.5, the model Anthropic now sells as its daily driver. Artificial Analysis spends $1.04 per Intelligence Index task on it, against $5.98 for Opus 5.5.
- Highly token-efficient, using about 14,000 output tokens per Intelligence Index task versus 67,020 for Opus 4.8 in xAI’s launch-day comparison.
- Musk calls it “Opus-class, but faster,” with a custom inference stack expected to double the current ~80 tokens/sec.
What Grok 4.5 Actually Is
Grok 4.5 is xAI’s first model trained from the ground up for coding and agentic tasks rather than general intelligence. Built on the 1.5-trillion-parameter V9 foundation model, it was trained in partnership with Cursor to handle long-running jobs across multiple repositories and to operate with minimal human intervention across hundreds of tool calls. That partnership later produced SpaceXAI’s agent product, which puts the same approach into a desktop app.
The headline specs are straightforward.
| Spec | Detail |
|---|---|
| API model name | grok-4.5 |
| Architecture | V9 foundation model, 1.5 trillion parameters (3x larger than Grok 4.3’s V8) |
| Context window | 500k tokens |
| Speed | approximately 80 tokens per second at launch; Artificial Analysis now measures a 58 t/s median |
| Input modalities | text and images (vision) |
| Reasoning | configurable at low, medium, high or xhigh effort (default high) |
| Supported APIs | Responses API and Chat Completions |
| Built-in capabilities | function calling, web search, X search, code execution |
The V9 name marks a full generation shift from the V8-series that powered Grok 4.3, tripling the scale while shifting the training focus entirely toward coding and agentic tasks. The context window dropped from Grok 4.3’s 1 million tokens to 500k, which is a real tradeoff for anyone who needed the full million.
The Cursor Connection
The “trained with Cursor” framing in the announcement is not just a marketing partnership. In mid-June 2026, SpaceX acquired Cursor for approximately $60 billion, bringing one of the most widely used AI coding editors directly into the xAI ecosystem. That acquisition is why Grok 4.5’s training incorporated real Cursor developer session data, giving xAI direct access to the actual workflows, context patterns, and long-horizon task structures that developers use in production.
Unlike training on public code repositories, real session data captures how developers iterate on a problem, context-switch across files, and make multi-step decisions inside actual projects. Grok 4.5 is the first model to reflect that.
xAI also introduced a new training methodology alongside this model, asynchronous learning, which allows multi-hour agentic training runs to proceed in parallel with ongoing model training rather than sequentially. The practical effect is that feedback loops between the model’s behavior and its training updates are much tighter, which is what enables the model to handle the kind of long-running autonomous sessions that most agents currently stall on.
Benchmark Results
xAI’s Published Benchmarks at Launch
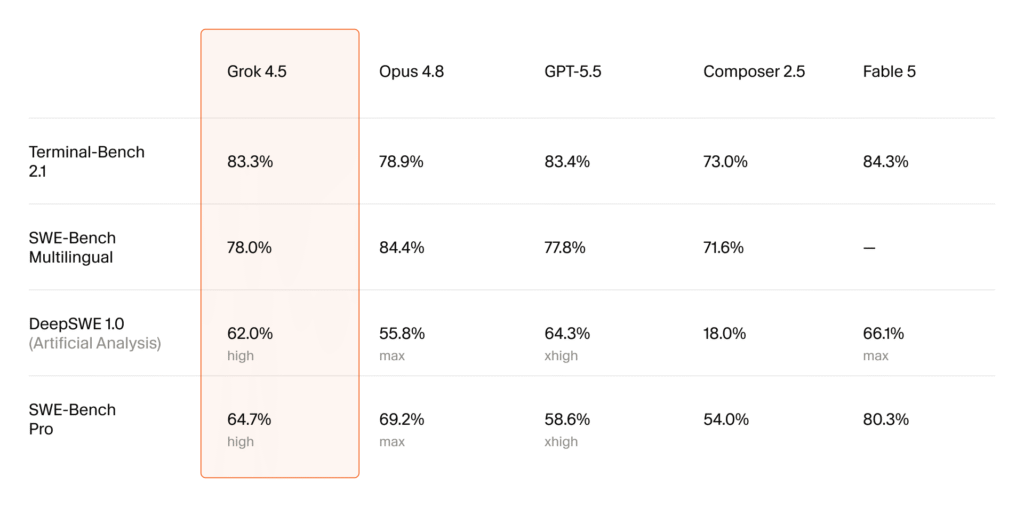
| Benchmark | Fable 5 | GPT-5.5 | Grok 4.5 | Opus 4.8 | GLM-5.2 |
|---|---|---|---|---|---|
| DeepSWE 1.0 | 66.1% | 64.3% | 62.0% | 55.8% | n/a |
| DeepSWE 1.1 | 70.0% | 67.0% | 53.0% | 59.0% | 44.0% |
| Terminal-Bench 2.1 | 84.3% | 83.4% | 83.3% | 78.9% | n/a |
| SWE-Bench Pro | 80.4% | n/a | 64.7% | 69.2% | 62.1% |
These are the figures xAI published on July 8, 2026, measured against the models that were current that day. Reading them straight: Grok 4.5 beats Opus 4.8 on two of the four benchmarks (DeepSWE 1.0 and Terminal-Bench 2.1) and trails it on two others (DeepSWE 1.1 and SWE-Bench Pro). Claude Fable 5 leads all four, and on Terminal-Bench 2.1 the margin between Grok 4.5 (83.3%) and GPT-5.5 (83.4%) is a single tenth of a point. Opus 4.8 and GPT-5.5 have each been superseded twice since: by Claude Opus 5 and then Claude Opus 5.5, and by GPT-5.6 Sol and then GPT-6 Astra. xAI has published head-to-head numbers against none of the four, so the current standings section below is the one to read for buying decisions.
Independent Benchmarks from Artificial Analysis
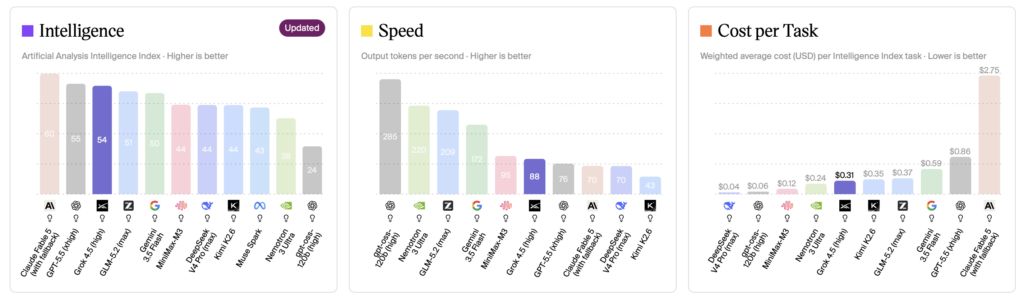
On the Artificial Analysis Intelligence Index, now at version v4.3.2, Grok 4.5 at high reasoning scores 38.8. Grok 4.3 scores 24.9 on the same board, so this is still the single largest generation-over-generation jump xAI has posted on this index. Every Artificial Analysis figure below is stamped with the index version it came from, because the versions are not comparable. The same model read 56 on v4.1.1: Artificial Analysis rescaled the entire board between the two releases, and the number fell without the model changing. One launch claim did not survive the move, though. Grok 4.5 no longer beats every Gemini model, because Gemini 3.8 Flash scores 40.9 at high effort. Gemini 3.6 Flash, the strongest Gemini on the board when Grok 4.5 shipped, now sits at 34.0.
Its position has moved, though, and that is worth stating plainly. Grok 4.5 ranked fourth of 168 entries at launch on July 8. On the v4.3.2 board as of September 25, 2026 it is 56th of 664 entries, with 27 separate models above it, among them Claude Opus 5.5, Claude Fable 5.1, GPT-6 Astra, Claude Opus 5, Muse Spark 1.3, GPT-6 Sol, Grok 4.7, Qwen3.8 Max, GLM-5.3, Grok 4.6 and Kimi K3. Claude Opus 4.8, the model Grok 4.5 was benchmarked against at launch, is still listed and scores 41.8, ahead of it. The rescale moved the number, the field moved the rank.
Another launch claim has flipped outright. Grok 4.5 no longer outperforms every open-weight model, because Kimi K3 shipped its open weights on July 27, 2026 and scores 43.6 on v4.3.2. GLM-5.3 at 44.8 and MiMo-V2.6-Pro at 46.3 are open-weight and above it too.
On GDPval-AA, the benchmark measuring sustained agentic knowledge work and now at v2.1, Grok 4.5 scores an Elo of 1,370, ahead of GLM-5.2 at 1,358 and behind Claude Opus 4.8 at 1,438. It ranked fourth at launch. Claude Opus 5 has since posted 1,708, and Claude Opus 5.5 leads the board outright at 1,846. On the toughest financial reasoning sub-task, tau3-Banking, Grok 4.5 hits 42.1%, still comfortably ahead of GPT-5.5 (xhigh) at 39.0%. It is no longer the top score, though. Qwen3.8 Max leads that board at 51.3%.
On the Artificial Analysis Coding Agent Index (DeepSWE, Terminal-Bench v2, and SWE-Atlas QnA combined), Grok 4.5 in the Grok Build harness scored 76, which ranked third in July 2026. It was on par with GPT-5.5 (xhigh) in Codex and sat just below Fable 5 (max) in Claude Code. Artificial Analysis has since retired that index, and neither DeepSWE nor SWE-Atlas QnA appears on its current evaluation list, so this one cannot be refreshed against today’s models.
xAI also reports the Harvey Legal Agent Benchmark, where Grok 4.5 ranks first. Combined with the tau3-Banking top score, that points at legal and financial knowledge work as specific strengths beyond what the coding benchmarks alone capture.
Token Efficiency
The per-token price is the headline, but token efficiency is the more meaningful number. On SWE-Bench Pro, Grok 4.5 used approximately 15,954 output tokens per task versus Opus 4.8’s 67,020, a 4.2x gap. On the Artificial Analysis Intelligence Index it uses roughly 14,000 output tokens per task, over 60% fewer than Opus 4.8. On the Coding Agent Index it averages 1.9 million total tokens per task, versus 7.2 million for Fable 5 in Claude Code and 6.2 million for GPT-5.5 in Codex.
A model that uses 4x fewer tokens is not just cheaper per task. It is faster and produces less noise in agentic pipelines, which matters for multi-step autonomous work.
Pricing and Cost Per Task
Grok 4.5 is priced at $2.00 per million input tokens and $6.00 per million output tokens. Cache hits are discounted 85%, bringing cached input tokens to $0.30 per million. One important caveat, pricing doubles for inputs longer than 200k tokens. For a full breakdown of Grok subscription and API pricing, including the consumer tiers, that guide covers all the options.
Against the current frontier that is half what Claude Opus 5.5 charges on input and under a third of what it charges on output, at $4 / $20. The Opus 5 that Grok 4.5 was measured against for most of its life listed at $5 / $25 and is now on Anthropic’s legacy list. But cost per task is the more meaningful number, since it accounts for how many tokens each model actually spends. The table below carries xAI and Artificial Analysis figures as published at launch in July 2026.
| Model | Input (per 1M) | Output (per 1M) | Cost per Intelligence Index task | Cost per Coding Agent task |
|---|---|---|---|---|
| Grok 4.5 | $2.00 | $6.00 | $0.31 | $2.49 |
| GPT-5.5 (Codex) | $5.00 | $30.00 | higher | $5.07 |
| Fable 5 (Claude Code) | $10.00 | $50.00 | higher | $11.80 |
| Opus 4.8 | $5.00 | $25.00 | higher | n/a |
The per-task figures are what actually matter at production scale. Grok 4.5 achieved near-equivalent coding agent performance at roughly half the cost of GPT-5.5 and less than a quarter the cost of Fable 5 per completed job. That advantage has held against Anthropic as the field moved on, but not against OpenAI. On Intelligence Index v4.3.2, Artificial Analysis puts the cost of running Grok 4.5 at $1.04 against $5.98 for Claude Opus 5.5 at max reasoning, while GPT-6.1 Sol at high reasoning runs it for $0.32 and scores higher.
Where Grok 4.5 Is Available
Grok 4.5 went live across a wide set of platforms on launch day. It is available in the xAI API under the model name grok-4.5, in Grok Build (xAI’s own coding agent harness), and in Cursor across all plans. Third-party access covers OpenRouter, Vercel, Cloudflare, Snowflake, and Databricks Mosaic. It is also live in Fello AI on Mac, iPhone and iPad.
The Office plugin launch is noteworthy. xAI is positioning Grok 4.5 not just as a coding model but as a knowledge work model capable of constructing complex Excel models with integrated web research and generating sophisticated PowerPoint content. That broadens the addressable use case well beyond software development.
The EU gap has closed. Grok 4.5 launched in 47 countries but was blocked across all 27 EU member states, a delay attributed to compliance work under the EU AI Act, which treats models trained above 1025 FLOPs as carrying systemic risk. xAI opened EU access later in July 2026, and its developer documentation no longer carries the regional restriction it showed at launch.
The model supports both the Responses API and Chat Completions formats, meaning it slots into codebases already built on OpenAI-compatible APIs without modification.
What Elon Musk Said
Musk made several statements around launch day that point at where this model fits and where it is going.
On capability positioning: “It is an Opus-class model, but faster, more token-efficient and lower cost,” with a follow-up clarification that it is “roughly comparable to Opus 4.7, but much faster.” That last detail matters. Musk is benchmarking against Opus 4.7, not 4.8, which the independent data broadly supports.
On the speed ceiling: “Grok 4.5 is not yet using our internally developed C/C++ inference software that exact maps to the GB300 hardware. Doubling or more of the current speed is probably achievable.” Current throughput around 80 tokens per second is not the final figure. The custom inference stack is in development and will add further speed without changing the model weights.
On what is next: “Next month’s release will be another step-change improvement, as we close the loop on solving real-world engineering problems at Tesla, SpaceX, Neuralink and Boring Company.” That feedback loop from real engineering work at xAI’s sister companies is a training data source no other lab has at the same scale.
On future multimodal capabilities: Grok will gain the ability to call Grok Imagine as a tool in agentic mode, invoking image and video generation as part of a longer autonomous workflow rather than as a separate feature. Musk flagged this as especially valuable for game developers.
Early User Reactions
Developer feedback from early Cursor access was positive. Danny Limanseta described it as “Opus 4.8 at 2x the speed at a much cheaper price point” after using it to brainstorm, plan, and implement a complex game feature across a full session without needing to manually correct it at each step.
Artificial Analysis summarized the competitive shift bluntly on launch day, writing that Grok 4.5 “brings SpaceXAI to the intelligence frontier behind only OpenAI and Anthropic, and outperforming all open weights models and notably Google’s Gemini models.” Both halves of that sentence have since been overtaken, as noted above.
How Grok 4.5 Compares to the Competition
Against the current frontier, Grok 4.5 rarely takes the outright top spot on raw capability. Against Anthropic it still wins on cost and token efficiency; against OpenAI’s GPT-6.1 Sol it no longer does. Here is how it stacks up model by model, using the Artificial Analysis v4.3.2 board for anything current and xAI’s launch figures where they are the only published numbers.
Versus Grok 4.3
38.8 against Grok 4.3’s 24.9 on v4.3.2 is the biggest generational leap in the Grok lineage. The context window halved from 1M to 500k, and input modalities narrowed to text and images, which are the two real tradeoffs. If you have been using Grok 4.3 for coding, Grok 4.5 is a significant upgrade across every other dimension.
Versus Claude Opus 5.5
Claude Opus 5.5 took over from Claude Opus 5 on September 22, 2026, and it now tops Intelligence Index v4.3.2 at 57.6, ahead of Claude Fable 5.1 at 53.4 and OpenAI’s GPT-6 Astra at 52.7. That is almost nineteen points clear of Grok 4.5, where Opus 5 was twelve. It also carries a 1M-token context window against Grok 4.5’s 500k. The cost comparison still runs the other way, though by less than it did: Opus 5.5 lists at $4 / $20 per million tokens against $2 / $6, where the Opus 5 it replaced listed at $5 / $25. Artificial Analysis spends $5.98 running Opus 5.5 through the index against $1.04 for Grok 4.5. For the hardest open-ended coding work Opus 5.5 has the edge; for agentic pipelines where per-task cost compounds across hundreds of tool calls, Grok 4.5 is the better economics.
Versus Claude Fable 5.1
Fable 5 led across all four xAI benchmarks at launch, and the cost gap was the largest of any comparison: $2.49 versus $11.80 per Coding Agent task, nearly 5x. Claude Fable 5.1 has since replaced it, and Artificial Analysis now lists Fable 5 as deprecated. On v4.3.2 Fable 5.1 scores 53.4 at max effort against Grok 4.5’s 38.8, and Artificial Analysis spends $7.63 running it through the index against $1.04, more than 7x. For workloads where the absolute top coding performance is mandatory, Fable 5.1 is ahead. For much lower cost per task, Grok 4.5 wins.
Versus GPT-6.1 Sol
GPT-6 Astra is OpenAI’s flagship, but GPT-6.1 Sol is the closer comparison on the board, and it is the one that breaks Grok 4.5’s cost case. On v4.3.2 GPT-6.1 Sol scores 51.8 at max reasoning and 50.2 at high, against Grok 4.5’s 38.8 at high. Artificial Analysis spends $0.72 running it through the index at max, less than Grok 4.5’s $1.04, and $0.32 at high. At matched high reasoning, GPT-6.1 Sol is eleven points stronger for less than a third of the cost. Its list price is higher on output, $2 / $10 per million tokens against $2 / $6, but it spends far fewer tokens per task. OpenAI released it on September 29, 2026 as the successor to GPT-6 Sol, which this section compared against until then and which scores 47.5 at max and 42.8 at high. GPT-5.6 Sol, the comparison before that, is still on OpenAI’s API, and Artificial Analysis now lists it as deprecated.
Versus the Launch-Day Pair, Opus 4.8 and GPT-5.5
Both models Grok 4.5 was benchmarked against in July have since moved to legacy status, but the numbers are worth keeping because they are the only head-to-head data xAI published. Against Opus 4.8, Grok 4.5 won DeepSWE 1.0 and Terminal-Bench 2.1 and lost DeepSWE 1.1 and SWE-Bench Pro. Against GPT-5.5 the margin on Terminal-Bench 2.1 was a tenth of a point (83.3% vs 83.4%), the Coding Agent Index was a tie, and Grok 4.5 led tau3-Banking by 2 points at roughly half the per-task cost ($2.49 vs $5.07).
Versus GLM-5.2
Grok 4.5 sits just ahead of GLM-5.2 on GDPval-AA v2.1 (Elo 1,370 vs 1,358). Grok 4.5 leads on the overall Intelligence Index as well, 38.8 against 33.7 on v4.3.2, and on tau3-Banking, 42.1% against 34.6%.
Why This Release Matters
Three things stand out from the Grok 4.5 launch that are worth tracking beyond the benchmark numbers.
xAI has reached the intelligence frontier. Grok 4.3 was not competing with Anthropic and OpenAI at the top of the capability rankings, scoring 24.9 on Intelligence Index v4.3.2. Grok 4.5 was, at 38.8 on the same board, and xAI has stayed there since: Grok 4.6 scores 44.3 and Grok 4.7 scores 46.3. That changed the competitive structure of the market from a two-player race to a three-way one.
The cost efficiency case is real, not just a pricing discount. Grok 4.5 is cheaper per token, but it is also dramatically more token-efficient per task. A model that produces the same output in 14,000 tokens when a competitor uses 67,000 is not just cheaper to run, it is faster and generates less noise in agentic workflows. Both matter at production scale.
The speed ceiling was not hit at launch. xAI quoted roughly 80 tokens per second on launch day, and Artificial Analysis now measures a median of 58 output tokens per second. Musk expected the custom C/C++ inference stack mapped to the GB300 hardware to double the launch figure, which would have made a model already competitive on cost and quality significantly faster with no model update required.
Grok 4.5 is live in Fello AI, where you can run it alongside Claude, ChatGPT, Gemini, DeepSeek, and Perplexity in one native app for Mac, iPhone, and iPad, comparing the same task across every frontier model on one subscription instead of managing separate accounts. For context on what comes after Grok 4.5, the Grok 5 article covers what xAI has signaled about the next major version.
FAQ
When was Grok 4.5 released?
xAI released Grok 4.5 on July 8, 2026. It is xAI’s first model built specifically for coding and agentic work, trained on real Cursor developer session data.
How much does Grok 4.5 cost?
API pricing is $2.00 per million input tokens and $6.00 per million output tokens. Cache hits get an 85% discount, dropping cached input to $0.30 per million. Pricing doubles for inputs longer than 200k tokens.
Is Grok 4.5 better than Claude Opus 5.5?
Not on raw capability. Claude Opus 5.5, Anthropic’s current model, scores 57.6 on Artificial Analysis Intelligence Index v4.3.2 against Grok 4.5’s 38.8, and carries a 1M-token context window against 500k. Grok 4.5 wins decisively on cost, at $2 / $6 per million tokens against $4 / $20, and on token efficiency per completed task.
What is Grok 4.5’s context window?
Grok 4.5 has a 500k-token context window, down from Grok 4.3’s 1 million tokens. It is the one clear tradeoff in an otherwise across-the-board upgrade.
Can I use Grok 4.5 in Fello AI?
Yes. Grok 4.5 is live in Fello AI, so you can run it next to Claude, ChatGPT, Gemini, DeepSeek, and Perplexity in one native Mac, iPhone, and iPad app and compare the same task across every frontier model on a single subscription.