Best AI Models in 2026
Rankings, comparisons, and deep dives, updated monthly as new models ship.
- Smartest overall and codingClaude Opus 5.5
- Hardest reasoningGPT-6 Astra
- ImagesChatGPT Images 2.5
- Best free pickClaude Sonnet 5.5
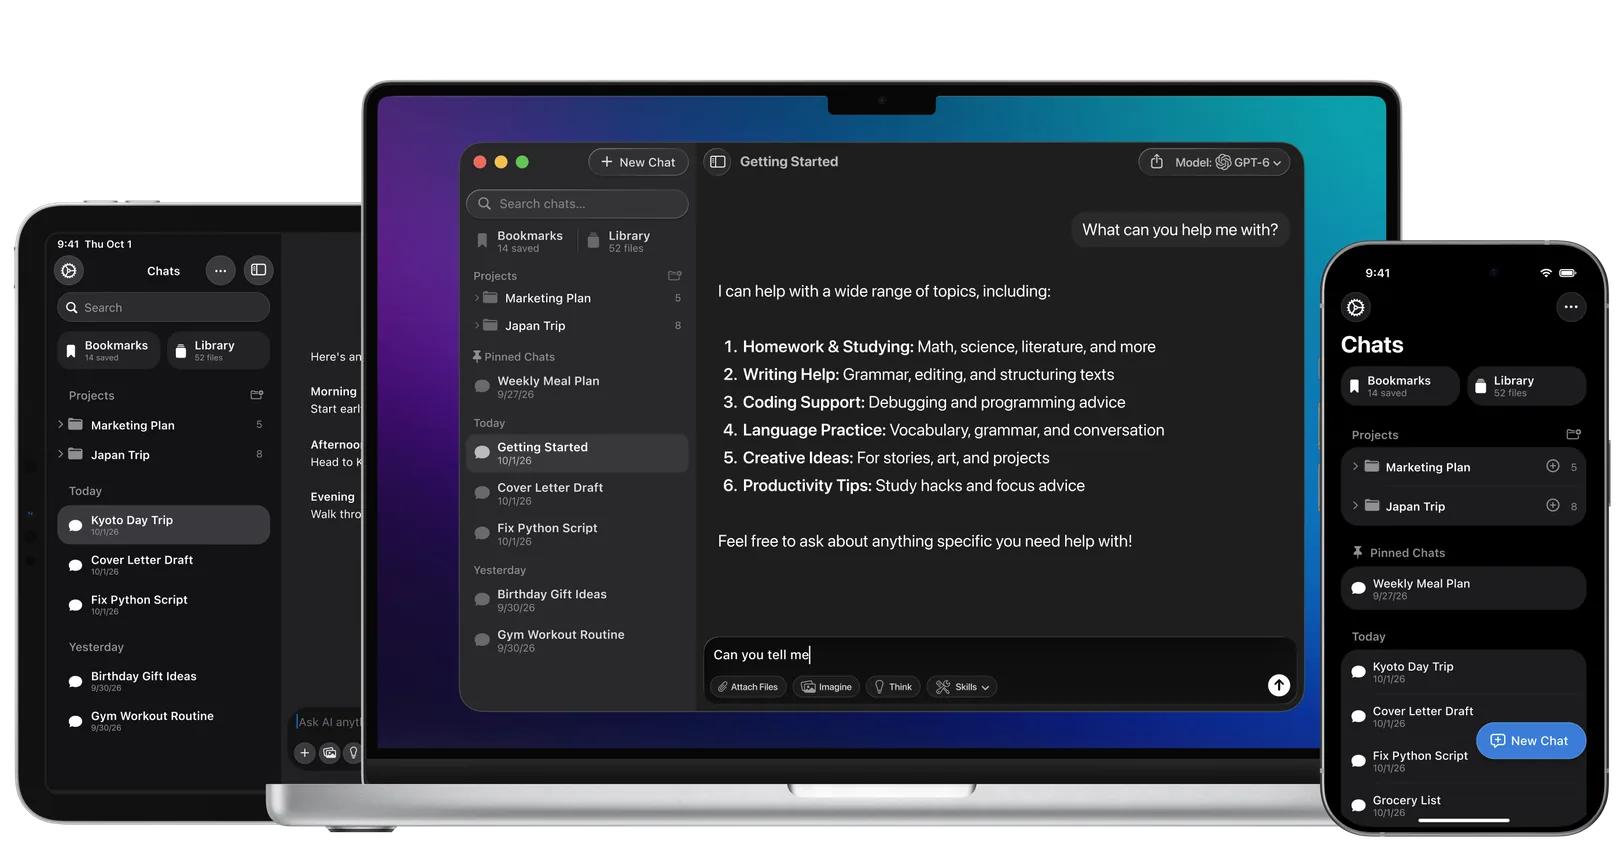
Stop tab-hopping between AI apps
Chat, search, PDFs and images in one app for Mac, iPhone and iPad.
Free to start·4.7★ from 27,000+ reviews
Rankings show who wins on average. Your prompt isn't average. Ask ChatGPT, Claude and Gemini in one window and keep the best answer.
Download Fello AIAnthropic holds most of the measured crowns this month. Claude Opus 5.5 (September 22) is #1 on the Intelligence Index at 57.6 and on Arena's WebDev board, Claude Sonnet 5.5 (September 28) is second at 56.0 and free on claude.ai, and Claude Haiku 5.5 (October 7) completes the family at $0.10 / $0.50. Our guide to AI benchmarks explains how that index is built.
Google's Gemini 4 Argon (September 30) scores 52.6, level with GPT-6 Astra, and is first on Arena's text board, and since October 13 it is open to Google AI Pro and Ultra subscribers and the paid API, which puts it second on the chat podium, but it wins no category: EQ-Bench, LiveBench and ARC Prize have not rated it yet. OpenAI competes on price: GPT-6 Sol and Luna halved its API rates, and GPT-6.1 Sol (September 29) scores 51.8 at $2 / $10, the cheapest model in the top tier per index task.
Meta's Muse Wonder (October 12) is the newest frontier entrant: Muse Wonder Full scores 55.8, third behind the two Claude models, but it runs only inside Meta's Muse Code subscription, and Muse Wonder on the API scores 52.4 at Opus 5.5's $4 / $20. Grok 4.7 (September 21) reached the API at an unchanged $2 / $6, and Xiaomi's MiMo-V2.6-Pro is still the highest-scoring open model at 46.3. On October 6 Mistral released Mistral Large 4 and Google shipped Nano Banana 2.1; neither takes a crown, but video changes hands to MiniMax H3. Rankings are updated within 48 hours of any major launch.
Oct 13 Google Gemini 4 Argon opens to Google AI Pro, Ultra and the paid API, and takes second place on the chat podium New
Oct 12 Muse Wonder Full lands third on the Intelligence Index, but only inside Meta's Muse Code subscription New
Oct 7 Anthropic Claude Haiku 5.5 scores 43.4 at GPT-6 Luna's price, and every Claude plan can pick it, Free included New
Oct 6 Mistral Mistral Large 4 is the strongest model from the US or Europe that promises open weights, but you cannot download it yet New
Oct 6 Google Nano Banana 2.1 replaces Nano Banana 2 at half the price per image and lands fifth on Arena text-to-image New
Sep 30 Google Gemini 4 Argon tops Arena's text board and matches GPT-6 Astra on the Intelligence Index, but only cyber defenders can use it New
Sep 29 OpenAI GPT-6.1 Sol reaches fifth on the Intelligence Index at $2 / $10, the cheapest per task in the top tier New
Sep 28 Anthropic Claude Sonnet 5.5 lands second on the Intelligence Index at 56.0, at Sonnet's $2 / $10 New
Sep 22 OpenAI GPT-6 Sol and GPT-6 Luna halve OpenAI's API prices, and land everywhere except ChatGPT's chat window New
Sep 22 Anthropic Claude Opus 5.5 takes the Intelligence Index at 57.6 and undercuts Opus 5 on price New
Sep 21 SpaceXAI Grok 4.7 arrives on a larger base model at an unchanged $2 / $6, and costs 47% more per task New
Sep 21 Xiaomi Xiaomi's MiMo-V2.6-Pro is the highest-scoring open model ever measured, at $0.13 an index task under MIT New
Sep 20 Alibaba Qwen-Image-2.1 is the best image model you can download, but its licence allows research use only New
Sep 15 TypeSafe TypeSafe leaves stealth with Jev, a model that returns typed decisions instead of text, at $0.042 per 1M tokens New
Pending Google Gemini 3.5 Pro, still unreleased, and Gemini 4 Argon has overtaken it Delayed
Best AI for Writing
The best AI for writing is Claude Fable 5.1, and the case for it is consistency rather than a single first place.
It is inside the top ten of all three prose boards: second on EQ-Bench Creative Writing v3 at 2162.0, third on LiveBench Language at 89.5 and ninth on Arena's creative-writing board. No other model places that well across all three. Gemini 4 Argon now leads Arena's creative-writing and text boards, at 1519.2 and 1525.4, and Google AI Pro subscribers can use it since October 13, but neither EQ-Bench nor LiveBench has rated it yet.
Claude Opus 5.5 is second on Arena's creative-writing board at 1517 but seventh on EQ-Bench and tenth on LiveBench Language; GPT-6 Astra leads EQ-Bench at 2173.3 but sits 42nd on Arena's creative-writing board; Claude Fable 5 tops LiveBench Language at 90.7 and is third on Arena's creative-writing board, but eleventh on EQ-Bench. If your writing is a work deliverable rather than prose, the GDPval-AA v2.1 professional-deliverables board is a different question, and Claude Opus 5.5 leads it at 1866, ahead of Meta's new Muse Wonder Full at 1857, Claude Sonnet 5.5 at 1838 and Claude Fable 5.1 at 1756.
Claude Sonnet 5.5 is the free-tier value pick, since anyone can use it on claude.ai, though it scores 83.4 on LiveBench Language, sits only 24th on Arena's creative-writing board and has no EQ-Bench rating yet. Claude Fable 5 is the pick if you weight Arena's human votes above the harness scores; it costs $10 / $50 per 1M tokens and is permanently included in Claude Max and Team Premium at roughly 50% of regular usage limits. Translation is a separate question with a separate winner, which we work through in our guide to the best AI for translation.
| Model | Best For | Strength | Weakness | Price (per 1M tokens) |
|---|---|---|---|---|
| Claude Fable 5.1 | Best writing overall | #2 EQ-Bench Creative Writing (2162.0), #3 LiveBench Language (89.5) and #9 Arena creative writing, the best combined placing of any model | Leads none of the three outright; Gemini 4 Argon now leads Arena's creative-writing board, with Claude Opus 5.5 second | $10 / $50 |
| Claude Fable 5 | Strong on the human-vote boards | #1 LiveBench Language (90.7), #3 Arena creative writing (1501.5), #4 Arena text (1503.7) | #11 EQ-Bench; priciest option here | $10 / $50 |
| Kimi K3 | Creative fiction and voice | #5 EQ-Bench Creative Writing (2082.3) | Only #28 on Arena creative writing | $3 / $15 |
| Claude Sonnet 5.5 | Free everyday writing | Free on claude.ai, 1M context; #3 GDPval-AA v2.1 (1838), behind Opus 5.5 and Muse Wonder Full | 83.4 LiveBench Language; #24 Arena creative writing; not yet rated on EQ-Bench | $2 / $10 |
| Claude Opus 5.5 | Arena's top creative writer you can use | #2 Arena creative writing (1517) and #2 Arena text (1507); #1 GDPval-AA v2.1 (1866) | #7 EQ-Bench and #10 LiveBench Language | $4 / $20 |
| Gemini 4 Argon | Top-voted prose on Arena | #1 Arena creative writing (1519.2) and #1 Arena text (1525.4) | Unrated on EQ-Bench and LiveBench | $19.99/mo Google AI Pro; $2 / $10 API intro to Nov 30 |
| GPT-5.5 | Fact-anchored business writing | Documented factual-reliability gains over GPT-5.4 | Reasoning tiers now marked deprecated | $5 / $30 |
| Gemini 3.8 Flash | Bulk drafts at scale | Intelligence Index 40.9, 308.4 tok/s output, 1M context | Agent-tuned rather than prose-tuned; intro price doubles January 1, 2027 | $0.75 / $3.75 |
The writing crown stays with Claude Fable 5.1, but its margin on Arena narrowed. Google's Gemini 4 Argon, announced September 30, went straight to first on Arena's creative-writing board at 1519.2, pushing Claude Opus 5.5 to second and Claude Fable 5 to third, and Fable 5.1 slipped from seventh to tenth and has since recovered to ninth, so this card's claim is now the top ten of all three prose boards rather than the top seven. Argon cannot take the crown yet: since October 13 Google AI Pro and Ultra subscribers can use it, but EQ-Bench and LiveBench have still not rated it. In September, Claude Opus 5.5 and Claude Sonnet 5.5 arrived, Sonnet 5.5 replaced Sonnet 5 as the free pick, and GPT-6.1 Sol entered LiveBench Language second, pushing Fable 5.1 to third there.
Best AI for Chat & Daily Assistant
The best AI for everyday chat is GPT-6, and the honest reason is reach rather than board position. Since October 7 it is what ChatGPT answers with by default: GPT-6 Sol on Plus, Pro, Business and Enterprise, and GPT-6 Luna on Free and Go, rolling out from October 8. That makes it the assistant most people can actually open.
On raw human preference it is far from the lead. GPT-6 Sol sits #67 on Arena's text leaderboard at 1455.9, below its predecessor GPT-5.6 Sol at #20, while Gemini 4 Argon leads at 1525.4 and Claude Opus 5.5 is second at 1507.1. Artificial Analysis scores GPT-6 Sol 47.6 on Intelligence Index v4.3.2 at maximum effort and GPT-6 Luna 38.1. In the API, Sol costs $2 / $10 and Luna $0.10 / $0.50 per 1M tokens.
| Model | Best For | Strength | Weakness | Price |
|---|---|---|---|---|
| GPT-6 | Everyday chat, ChatGPT's default | The assistant most people can open: Sol on paid plans, Luna on Free and Go | GPT-6 Sol only #67 on Arena text | Free / $20/mo Plus; API $0.10 / $0.50 (Luna) to $2 / $10 (Sol) |
| Gemini 4 Argon | Top-voted conversation | #1 on Arena text (1525.4); 15% hallucination rate, the lowest among leading models | Arena rating still preliminary; Google AI Pro or above in the Gemini app | $19.99/mo Google AI Pro; $2 / $10 API intro to Nov 30 |
| Claude Opus 5.5 | Highest-scoring conversation | #1 on the Intelligence Index (57.6) and #2 on Arena text (1507.1) | Not on the Free plan; usage-limited on Pro | $20/mo Pro, $4 / $20 API |
| Claude Sonnet 5.5 | Free Claude chat | Free on claude.ai; #2 on the Intelligence Index (56.0), behind only Claude Opus 5.5 | Only #32 on Arena text; runs at Medium effort by default in the apps | Free / $20/mo Pro, $2 / $10 API |
| GPT-5.5 Instant | Hallucination-sensitive daily work | 52.5% fewer hallucinated claims vs 5.3 Instant | Reasoning tiers now marked deprecated | $20/mo Plus; API $5 / $30 |
| Gemini 3.6 Flash | Fast, cheap, multimodal | 1M context, #23 on Arena text | Needs Google AI Plus in the Gemini app since October 9; 3.8 Flash outscores it at the same price | AI Plus / $0.75 / $3.75 API |
| Fello AI | Many leading models, one app | ChatGPT + Claude + Gemini + Grok + DeepSeek and more on Mac, iPhone and iPad | Routed via app, not direct | From $11.99/mo |
The chat pick moves from GPT-5.6 to GPT-6, for the same reason GPT-5.6 held it: on October 7 OpenAI made GPT-6 ChatGPT's default, Sol on paid plans and Luna on Free and Go from October 8. The vote-based boards rate it below its predecessor, GPT-6 Sol #67 on Arena text against GPT-5.6 Sol's #20, which is why this pick rests on reach. Since October 13 Gemini 4 Argon is in the Gemini app for Google AI Pro and Ultra subscribers, so the leader of Arena's text board, at 1525.4, takes second place on the podium; Claude Opus 5.5 moves to third and Claude Sonnet 5.5 stays in the table as the free Claude pick.
Best AI for Images
The best AI for image generation is ChatGPT Images 2.5, which OpenAI made the default on every ChatGPT tier on September 8 and which leads all four image boards we track.
Its two models finish first and second on each: GPT-Image-2.5 Sunburst, built for precision, leads Arena text-to-image at 1424.6 and Arena image editing at 1523.6, and Artificial Analysis's AA-Image-T2I v2.0 at 1197 and AA-Image-Editing v2.0 at 1182, with the faster GPT-Image-2.5 Flare second on all four. Read the Sunburst-to-Flare gap on Arena text-to-image as provisional, because each rests on about 17,000 votes against GPT Image 2's 93,000. MAI-Image-2.6 is the runner-up, third on Artificial Analysis's editing board and fifth on Arena's text-to-image board at 1332.1, a statistical tie with Grok Imagine Image 2.0 just above it.
Third is SpaceXAI's Grok Imagine Image 2.0, released in August and available in Grok Imagine and the xAI API: it is fourth on Artificial Analysis's text-to-image board, on Arena image editing and now on Arena text-to-image, ahead of Meta's Muse Image on three of the four boards. Google's Nano Banana 2.1, released on October 6, is now the highest-ranked Google model: sixth on Arena text-to-image at 1327.8, in the same rank band as MAI-Image-2.6 and Grok Imagine Image 2.0, and sixth on Arena editing, though Artificial Analysis has not rated it yet.
The best image model you can download is Alibaba's Qwen-Image-2.1, released on September 20 and now the highest-ranked open-weight model on all four boards, 18th on Arena image editing and on both Artificial Analysis boards and 19th on Arena text-to-image, but its licence allows research and evaluation only, so it is not a free commercial option. Our full breakdown of what shipped is in ChatGPT Images 2.5.
| Model | Best For | Strength | Weakness | Price |
|---|---|---|---|---|
| ChatGPT Images 2.5 | Images with readable text | #1 and #2 on all four boards: Arena text-to-image (1424.6 / 1397.6), Arena editing (1523.6 / 1481.0), Artificial Analysis text-to-image (1197 / 1191) and editing (1182 / 1162) | Its Arena text-to-image lead rests on about 17,000 votes per model | Default on every ChatGPT tier |
| MAI-Image-2.6 | Editing an image you already have | #3 on Artificial Analysis image editing (1137) and #5 on Arena text-to-image (1332.1) | Public preview, not in Copilot or Bing yet; lost the Artificial Analysis editing lead to ChatGPT Images 2.5 | MAI Playground / Microsoft Foundry |
| Grok Imagine Image 2.0 | Fewest restrictions, Spicy Mode | #4 on Artificial Analysis text-to-image (1155) and #4 on Arena image editing (1439.1); #4 on Arena text-to-image (1333.5) | Only #10 on Artificial Analysis image editing | $30/mo SuperGrok; xAI API |
| Nano Banana 2.1 | Google's everyday image model | #6 Arena text-to-image (1327.8) and #6 Arena image editing (1428.1), the highest of any Google model; half Nano Banana 2's API price per image | Not yet rated by Artificial Analysis; input tokens cost three times as much as on Nano Banana 2 | Gemini app / AI Studio; $0.0336 per 1K image |
| Seedream 5.0 Pro | Multilingual text + region editing | 10+ languages incl. Arabic RTL, lasso and layer editing | Around tenth on the independent boards; copyright cloud | BytePlus / Magnific |
| Midjourney v8 | Stylized art, illustration | Aesthetic baseline most artists prefer | Weaker on text in image | $10-$120/mo |
| Qwen-Image-2.1 | Best image model you can download | Highest-ranked open-weight model on all four boards: #18 Arena image editing (1368.7), #19 Arena text-to-image (1222.9) and #18 on both Artificial Analysis boards; 7B generator, transparent PNGs, up to 10 reference images | Qwen Research License, research or evaluation only, no commercial use | Free download (Hugging Face) |
| Qwen-Image-3.0-Pro | Dense, text-heavy layouts | #13 Arena text-to-image (1255.2) and #14 Artificial Analysis text-to-image (1090); prompts up to 4.5k tokens, text in 12 languages | Hosted only, no weights; not rated on Arena image editing | Qwen Chat; $0.04-$0.075 per image in the API |
| Muse Image | Image editing, Meta ecosystem | #6 on Artificial Analysis image editing (1118) and #7 on its text-to-image board | Off the podium; #9 on Arena text-to-image and #8 on Arena editing | Meta AI app |
ChatGPT Images 2.5 keeps the image crown and still holds first and second on all four boards we track. Since the last update Google released Nano Banana 2.1 on October 6, and Arena ranked it fifth on text-to-image and sixth on editing, the highest of any Google model, inside the same rank band as MAI-Image-2.6 and Grok Imagine Image 2.0. It takes Nano Banana 2's table row rather than a podium place: it now trails both MAI-Image-2.6 and Grok Imagine Image 2.0 on both Arena boards, and Artificial Analysis has not rated it yet.
Grok Imagine Image 2.0 has since climbed to fourth on Arena text-to-image, 1.4 points above MAI-Image-2.6 in fifth; Nano Banana 2.1 is now sixth and Reve 2.1 seventh. Earlier this month Grok Imagine Image 2.0 took third place from Muse Image, and Artificial Analysis moved both its image boards to v2.0. In September, Images 2.5 replaced GPT Image 2 at the top on September 8.
Best AI for Video
The best AI for video generation is MiniMax H3, which MiniMax released on July 31 with open weights, and the case for it is that it places near the top everywhere rather than winning one board outright.
It leads Arena's image-to-video board at 1495.4, ahead of Gemini Omni 1.1 Flash at 1488.5 and Alibaba's Wan 3.0 at 1479.8; on Artificial Analysis's image-to-video board it is second at 1181, behind only MiniMax H3 Max, a model Fal built on top of it; and it is fourth on Artificial Analysis's text-to-video board at 1137. Its weak spot is Arena's text-to-video board, where it is eighth at 1460.3.
It makes 2K clips of 4 to 15 seconds with native stereo audio, from $0.13 a second at 2K, and the weights are on Hugging Face under MiniMax's own community licence, without the 2K upscaler and with an application required in the US, EU, UK and South Korea. Gemini Omni 1.1 Flash, our pick until this update, still leads Arena's text-to-video board at 1516.2, in a statistical tie with Gemini Omni Flash at 1512.9, and it is the pick for long takes: scene extension in 10-second steps to 40 seconds, first and last frame control and 4K output, from about $0.03 a second at 360p to $0.30 at 4K.
But Artificial Analysis has now rated it, and it comes eighth on text-to-video at 1113 with no image-to-video rating at all. Wan 3.0 leads Artificial Analysis's text-to-video board at 1156 and is third on Arena's image-to-video board, but only sixth on Arena's text-to-video board. If you need longer takes inside Google's tooling, Veo 3.1 still runs in the Gemini app, AI Studio and Vertex AI with native audio and 1080p output.
| Model | Best For | Strength | Weakness | Price |
|---|---|---|---|---|
| MiniMax H3 | Best AI video overall | #1 Arena image-to-video (1495.4), #2 Artificial Analysis image-to-video (1181), #4 Artificial Analysis text-to-video (1137); 2K clips of 4-15s with native stereo audio | #8 on Arena text-to-video (1460); the open weights exclude the 2K upscaler and need an application in the US, EU, UK and South Korea | $0.13/sec at 2K |
| Gemini Omni 1.1 Flash | Long takes and 4K | #1 Arena text-to-video (1516), #2 Arena image-to-video (1488.5); 40-second scene extension, 4K output | Only #8 on Artificial Analysis text-to-video (1113); no Artificial Analysis image-to-video rating | $0.03-$0.30/sec; Gemini API / AI Studio / Flow |
| Gemini Omni Flash | Cheaper 10-second clips | #2 Arena text-to-video (1513), #3 Artificial Analysis image-to-video (1178); conversational editing | Caps at 10-second generations | ~$0.10/sec; Gemini app / AI Studio |
| Wan 3.0 | Video from documents and slides | #1 Artificial Analysis text-to-video (1156), #3 Arena image-to-video (1479.8); 2-30s, up to 1080p, Omni-Reference input | API-only, no published weights; #6 on Arena text-to-video | $0.05-$0.20/sec |
| Dreamina Seedance 2.5 | ByteDance challenger | #3 Artificial Analysis text-to-video (1143), #4 Arena image-to-video (1477.4) | #7 Arena text-to-video (1474); ByteDance ecosystem, limited Western access | Dreamina / BytePlus |
| Muse Video | Meta ecosystem video | #9 on Arena text-to-video at 1456 | Newest of the group, thin tooling | Meta AI app |
| Veo 3.1 | Longer production clips | Native audio, 1080p, strong physics consistency | #12 on Arena video, not the quality leader | Google AI Pro / Ultra |
| Kling 3.0 / 3.0 Turbo | Fast iteration at lower cost | Native 4K, 60fps, 15-second clips; Turbo shipped June 17 | Outside the top 16 on Arena text-to-video | From $10/mo |
| Luma Ray 3 | Photoreal scenes | Strong realism for landscapes | Smaller community | Free / from $9.99/mo |
The video crown moves from Gemini Omni 1.1 Flash to MiniMax H3. Since the last update Artificial Analysis has rated Omni 1.1 Flash for the first time, and on its text-to-video board, now at version 2.0, it comes eighth at 1113, behind Wan 3.0 at 1156 and MiniMax H3 at 1137. With H3 still first on Arena's image-to-video board and second on Artificial Analysis's, behind only a model built on it, H3 now places better across the four boards we track.
Omni 1.1 Flash keeps first place on Arena's text-to-video board, still a statistical tie with Gemini Omni Flash, so it stays on the podium as the text-to-video pick, and Wan 3.0 takes third place from Dreamina Seedance 2.0. Earlier this month FLUX 3 Video and Grok Imagine Video 1.5 entered Arena's text-to-video board third and fourth. In September, Gemini Omni 1.1 Flash held first place on Arena's text-to-video board and MiniMax H3 took first place on its image-to-video board.
Best AI for Coding
The best AI for coding is Claude Opus 5.5, which Anthropic shipped on September 22, though it no longer leads every board, and the model that took two of them is its own cheaper sibling.
Claude Sonnet 5.5, released September 28, leads Artificial Analysis's own Terminal-Bench 4.0 run at 63.6% against Opus 5.5's 59.6% and LiveBench Coding at 91.4 against 89.3. Opus 5.5 keeps the crown on the rest of the evidence. It leads Arena's WebDev board at 1813, ahead of GPT-6 Astra at 1786 and Claude Sonnet 5.5 at 1774. It scores 71.7 on LiveBench Agentic Coding, second only to DeepSeek V4.1-Flash, where Sonnet 5.5 manages 56.3, and on Anthropic's own harnesses it beats Sonnet 5.5 on FrontierCode v1.1, 54.4% to 52.1%, and on CursorBench 4.0, 57.8% to 55.5%. Price now favours Sonnet 5.5 at every effort level.
It is $2 / $10 per 1M tokens against Opus 5.5's $4 / $20, and Artificial Analysis now puts even a max-effort Intelligence Index task at $5.46 against Opus 5.5's $5.98; at xhigh it scores 51.9 on the index for $2.01 a task and at high 46.7 for $0.88. Opus 5.5 has also taken Arena's image-to-WebDev board at 1748.5, ahead of Sonnet 5.5 at 1740.0 and GPT-6 Astra at 1731.4; Astra matches Opus 5.5's 59.6% on Terminal-Bench 4.0 at xhigh, at $10 / $50, and Claude Fable 5.1 is fifth on WebDev and fourth on image-to-WebDev.
GPT-6.1 Sol is the cheap OpenAI option: fourth on WebDev and 56.1% on Terminal-Bench 4.0 for $0.72 an index task, though LiveBench puts it well outside the top ten on Coding, at 80.7. Gemini 4 Argon leads Google's own DeepSWE v1.1 table at 77.9%, but Artificial Analysis measures 57.1% on Terminal-Bench 4.0, Arena puts it ninth on WebDev, and since October 13 it is on the paid API and in Antigravity for Google AI Ultra subscribers.
Claude Haiku 5.5, released October 7 at $0.10 / $0.50, is the cheap Claude for high-volume sub-agent work: 33% on Artificial Analysis's Terminal-Bench 4.0 run, level with GLM 5.3 Flash, and 57.2 on LiveBench Agentic Coding, just above Sonnet 5.5, though Arena puts it only 30th on WebDev. Among open weights, Xiaomi's MiMo-V2.6-Pro takes 34.8% on Terminal-Bench 4.0 under plain MIT at $0.13 an index task, GLM-5.3 is still the strongest open model on that harness at 41.9%, and Kimi K3 is the highest-placed open model on Arena WebDev, fourteenth at 1654, on only 12.6% of the harness.
Artificial Analysis has retired both its Coding Index and its Coding Agent Index, so the two composite coding rankings this page used to quote no longer exist.
| Model | Best For | Strength | Weakness | Price (per 1M tokens) |
|---|---|---|---|---|
| Claude Opus 5.5 | Best coding overall | #1 Arena WebDev (1813) and #1 Intelligence Index (57.6, v4.3.2); 71.7 LiveBench Agentic Coding, 15 points above Sonnet 5.5 | Second to Sonnet 5.5 on Terminal-Bench 4.0 (59.6% to 63.6%) and LiveBench Coding (89.3 to 91.4) | $4 / $20 |
| Claude Sonnet 5.5 | Value pick for coding | #1 Terminal-Bench 4.0 (63.6%) and #1 LiveBench Coding (91.4), #3 Arena WebDev (1774); 51.9 on the index for $2.01 a task at xhigh | 56.3 LiveBench Agentic Coding, 15 points behind Opus 5.5 | $2 / $10 |
| GPT-6 Astra | Second on Arena WebDev | #2 Arena WebDev (1786) and #3 image-to-WebDev (1731.4); 59.6% Terminal-Bench 4.0 at xhigh | 2.5x Opus 5.5's price; behind Sonnet 5.5 on Terminal-Bench and well behind both Claude models on LiveBench Coding | $10 / $50 |
| Claude Fable 5.1 | Highest composite score before Opus 5.5 | #5 Arena WebDev and #4 image-to-WebDev; Intelligence Index 53.4; AA-Briefcase 1675 | 52.0% Terminal-Bench 4.0; 2.5x the price of Opus 5.5 | $10 / $50 |
| Claude Opus 5 | Superseded by Opus 5.5 | 49.0% Terminal-Bench 4.0 and #7 Arena WebDev and #7 image-to-WebDev | Costs more per token than Opus 5.5 and scores seven points lower | $5 / $25 |
| Claude Fable 5 | Hardest long-horizon agentic work | Intelligence Index 49.6; 42.4% Terminal-Bench 4.0; 1M context | The priciest per index task on this table at $8.75; #10 on Arena image-to-WebDev | $10 / $50 |
| Qwen3.8-Max-0902 | Brief holder of Arena's WebDev board | #10 Code Arena: WebDev (1674); Intelligence Index 45.4; 2.4T parameters, 1M context | QwenCloud API only with no consumer front-end; lost the WebDev lead within days | $2 / $6 |
| Kimi K3 | Highest-placed open model on Arena | #14 Arena WebDev (1654), the best open placement on that board; 2.8T/104B active | Only 12.6% on Terminal-Bench 4.0; 1.56 TB to self-host | $3 / $15 |
| GPT-5.6 Sol | OpenAI's cheaper flagship | Intelligence Index 47.0; 39.9% Terminal-Bench 4.0 | Superseded by GPT-6 Sol, which scores higher at half the price; eval-gaming flagged by METR | $4 / $20 |
| GPT-6 Sol | Cheap GPT-6 coding in Codex | Intelligence Index 47.6 (v4.3.2) and 43.9% Terminal-Bench 4.0, both above GPT-5.6 Sol, at half its price | #8 Arena WebDev (1688) | $2 / $10 |
| GPT-6.1 Sol | Cheapest top-tier model per task | Intelligence Index 51.8 (v4.3.2), #4 Arena WebDev (1755) and 56.1% Terminal-Bench 4.0 at $0.72 an index task, with cached input at $0.10 | 80.7 on LiveBench Coding, well outside the top ten; in Codex and ChatGPT Work only, not in Chat | $2 / $10 |
| Gemini 4 Argon | Long software tasks | 77.9% DeepSWE v1.1 on Google's own figures; Intelligence Index 52.6 at $1.99 an index task | 57.1% Terminal-Bench 4.0 and #9 Arena WebDev (1678) | $2 / $10 intro to Nov 30, $4 / $20 standard |
| Muse Spark 1.3 | Cheap agentic coding | Intelligence Index 48.1 at $1.25 / $4.25, and $1.60 per index task | 33.3% on Terminal-Bench 4.0; the coding wins come from Meta's own chart, measured on a partners-only max variant | $1.25 / $4.25 |
| Muse Wonder Full | Meta's strongest model, inside Muse Code | Intelligence Index 55.8 (v4.3.2), third among distinct models; #2 GDPval-AA v2.1 (1857); 57.1% Terminal-Bench 4.0 | Muse Code subscription only ($50 and $200 plans), no API; Arena has not rated it | Muse Code, from $50/mo |
| Muse Wonder | Meta's frontier model on the API | Intelligence Index 52.4 (v4.3.2); 52.0% Terminal-Bench 4.0; 1M context | Same $4 / $20 as Opus 5.5, which scores 5.2 points higher; $4.52 an index task | $4 / $20 |
| Grok 4.7 | Cheap value coder | 46.3% CursorBench 4.0 and 71.0% DeepSWE v1.1 on SpaceXAI's own figures; Intelligence Index 46.3 | 24.7% on Terminal-Bench 4.0; prompts of 200K tokens and up re-bill the whole request at double | $2 / $6 |
| Gemini 3.8 Flash | Agent coding at scale | Intelligence Index 40.9; 308.4 output tokens per second | 19.7% on Terminal-Bench 4.0; intro price doubles January 1, 2027 | $0.75 / $3.75 |
| GLM 5.3 Flash | Cheapest serious coder you can host | 32.8% Terminal-Bench 4.0 at $0.25 an index task; MIT, 320B/18B active | GLM-5.3 reaches 41.9% on the same harness; no consumer product | Open weights (MIT) |
| Claude Haiku 5.5 | Cheapest Claude for sub-agents | Intelligence Index 43.4 (v4.3.2) at $0.21 an index task; 33% Terminal-Bench 4.0, level with GLM 5.3 Flash; 57.2 LiveBench Agentic Coding, above Sonnet 5.5 | #30 Arena WebDev (1587); Anthropic says Sonnet 5.5 and Opus 5.5 remain better for complex agentic coding; prompts above 100K tokens cost five times as much | $0.10 / $0.50 |
| MiMo-V2.6-Pro | Highest open Intelligence Index | 46.3 on v4.3.2 and 34.8% Terminal-Bench 4.0 at $0.13 an index task; MIT, 1.02T/42B active | Only #19 on Arena WebDev (1629), five places behind Kimi K3 | $0.435 / $0.87 |
Claude Opus 5.5 keeps the coding crown. Since the last update Claude Haiku 5.5 arrived on October 7 at $0.10 / $0.50 and takes a table row as the cheapest Claude for sub-agent work, though Arena puts it only 30th on WebDev. Artificial Analysis now prices a max-effort Sonnet 5.5 index task at $5.46, below Opus 5.5's $5.98, so Opus 5.5 holds the crown on WebDev and LiveBench Agentic Coding rather than on cost. Claude Sonnet 5.5 has entered Arena's WebDev board third at 1774, behind GPT-6 Astra at 1786, which pushes GPT-6.1 Sol to fourth and Claude Fable 5.1 to fifth, and Gemini 4 Argon, which entered at the start of the month, is now ninth. Since then Opus 5.5 has also taken Arena's image-to-WebDev board from GPT-6 Astra, and Meta's Muse Wonder arrived on October 12 with two table rows: Muse Wonder Full scores 55.8 on the index but runs only in Muse Code, and Muse Wonder costs the same $4 / $20 as Opus 5.5 for 52.4.
Argon leads Google's own DeepSWE v1.1 table at 77.9%, but on Artificial Analysis's Terminal-Bench 4.0 it scores 57.1%, behind Sonnet 5.5, Opus 5.5 and GPT-6 Astra, and its public release on October 13 did not change those scores. In September the crown moved twice, from Claude Fable 5.1 to GPT-6 Astra and then to Opus 5.5, and Claude Sonnet 5.5 took Terminal-Bench 4.0 and LiveBench Coding as the value pick.
Best AI for Creativity
The best AI for unfiltered, on-trend creative work is Grok 4.7, and we want to be exact about why. This pick is about the product line, not the prose quality.
Grok carries the fewest content restrictions of any frontier model and the only native real-time X integration, which makes it the one model that will engage with edgy, topical or deliberately provocative briefs that the others decline. SpaceXAI shipped Grok 4.7 on September 21 to the Grok API, Cursor and Grok Build, and since October 3 it also powers Expert mode on grok.com, plus Fast mode for paid subscribers. It is not the best writer, though the picture is more mixed than it was.
EQ-Bench has now rated Grok 4.7 and puts it eighth at 2006.7, inside its top ten and far above Grok 4.5 in 52nd, but Arena's human voters put 4.7 only 74th on creative writing, behind Grok 4.6 in 54th and the older Grok 4.20-beta1 in 23rd. If you are picking on output quality alone, Gemini 4 Argon now leads Arena's creative-writing board, on Google AI Pro since October 13, with Claude Opus 5.5 second and Claude Fable 5 third, while EQ-Bench puts GPT-6 Astra first at 2173.3, Claude Fable 5.1 second and Kimi K3 fifth. Choose Grok for what it will let you make, not for how well it writes.
| Model | Best For | Strength | Weakness | Price |
|---|---|---|---|---|
| Grok 4.7 | Unfiltered, opinionated, on-trend | Fewest content restrictions, native real-time X grounding | #74 on Arena creative writing, though #8 on EQ-Bench (2006.7) | $2 / $6 API; $30/mo SuperGrok app |
| Claude Fable 5 | Highest-quality creative prose | #3 Arena creative writing, #1 LiveBench Language | Cautious guardrails on edgy briefs | $10 / $50 API |
| Kimi K3 | Fiction and distinctive voice | #5 EQ-Bench Creative Writing at 2082.3 | Only #28 on Arena creative writing | $3 / $15 |
| Claude Opus 5 | Long-form structured creativity | Holds long threads and self-edits; Intelligence Index 50.8, now behind six newer models | Most cautious of the group | $20/mo Pro; $5 / $25 API |
| Gemini 3.1 Pro | Multimodal creative | Strong text, image and video chain | Needs Google AI Pro in the Gemini app since October 9 | AI Pro / $2.00-$4.00 API in |
| Grok Imagine (Spicy Mode) | NSFW / adult creative | Most permissive image generation | Niche use case | $30/mo SuperGrok |
Grok keeps this pick on Grok 4.7, and nothing about the product's permissiveness or its live X access changed, which is what the pick rests on. Arena's creative-writing board moved around it: Gemini 4 Argon, announced September 30, went in at first, Claude Opus 5.5 is now second and Claude Fable 5 third, and Grok 4.7 has slipped to 74th. EQ-Bench has not changed and still puts 4.7 eighth. The app the permissiveness argument is really about caught up on October 3, when Grok 4.7 started powering Expert mode on grok.com. In September, Grok 4.7 replaced Grok 4.6 as SpaceXAI's flagship on September 21 and both creative-writing boards rated it.
Best AI for Accuracy & Research
The best AI for accuracy and research is Claude Fable 5.1, which holds the highest factual accuracy Artificial Analysis has measured, 67% on AA-Omniscience.
That is the exact column this category is decided on. Claude Opus 5.5 beat Fable 5.1 on almost everything else when it arrived on September 22, including Humanity's Last Exam at 61.4% to 59.1% and the hallucination-penalised AA-Omniscience index at 46.4 to 43.5, but on raw factual accuracy it reads 66% to Fable 5.1's 67%. Treat that one-point gap as a tie and read the two together: Opus 5.5 is the better bet when a wrong answer is worse than no answer, Fable 5.1 when you want the most facts right.
The value pick is now GPT-6.1 Sol, which answers 62% correctly with an AA-Omniscience index of 41.5 at $2 / $10 per 1M tokens and $0.72 an index task, and scores 98.5% on ARC Prize's ARC-AGI-1 for $0.06 a task. That beats Gemini 3.1 Pro, our value pick until this update, on every accuracy measure Artificial Analysis publishes: it reads 55% raw accuracy and an index of 31.9.
Gemini 3.1 Pro keeps its case where the answer has to be current, because it grounds answers in Google Search and is in the Gemini app (Google AI Pro and above since October 9), while GPT-6.1 Sol runs in ChatGPT Work, Codex and the API rather than in ChatGPT's chat window. Gemini 4 Argon is the model to watch: Artificial Analysis measures a 15% hallucination rate, the lowest among leading models, because it declines rather than guesses, but it answers only 50% correctly; since October 13 it is in the Gemini app on Google AI Pro and above.
On grounded search specifically, Arena's search leaderboard is led by OpenAI: GPT-5.6 Sol tops it at 1257, with Claude Fable 5 fifth and Gemini 3.1 Pro grounding ninth. On novel reasoning the crown sits elsewhere, with GPT-6 Astra leading ARC-AGI-2 and ARC-AGI-3. Claude Opus 5 holds no accuracy crown because Artificial Analysis measures its hallucination rate at 61%.
| Model | Best For | Key Benchmark | Weakness | Price |
|---|---|---|---|---|
| Claude Fable 5.1 | Highest measured factual accuracy | 67% factual accuracy on AA-Omniscience, the highest Artificial Analysis has measured, one point above Claude Opus 5.5 | No cheap tier; unrated on Arena's search leaderboard; Opus 5.5 leads Humanity's Last Exam and the AA-Omniscience index | $10 / $50 |
| Claude Opus 5.5 | When a wrong answer is worse than none | #1 AA-Omniscience index (46.4) and #1 Humanity's Last Exam (61.4%); 66% raw accuracy | One point behind Fable 5.1 on raw accuracy | $4 / $20 |
| GPT-6.1 Sol | Best value | 62% raw accuracy and an AA-Omniscience index of 41.5 at $0.72 an index task; 98.5% ARC-AGI-1 at $0.06 a task | 54% hallucination rate; in ChatGPT Work and Codex, not in Chat | $2 / $10 |
| Gemini 4 Argon | Fewest hallucinations | 15% hallucination rate on AA-Omniscience, the lowest among leading models | Only 50% raw accuracy | $19.99/mo Google AI Pro; $2 / $10 API intro |
| Gemini 3.1 Pro | Grounded search; Gemini app on AI Pro from Oct 9 | Native Google Search grounding; 98% ARC-AGI-1 at $0.52/task | 55% raw accuracy on AA-Omniscience, below GPT-6.1 Sol; #9 on Arena search | $2.00-$4.00 / $12.00-$18.00 (tiered) |
| Claude Fable 5 | Grounded search | #5 on Arena's search leaderboard, behind GPT-5.6 Sol | No single cheap tier | $10 / $50 (Fable 5) |
| GPT-5.6 Sol | Novel reasoning | #4 ARC-AGI-2 at 92.5%, behind GPT-6 Astra (95%), GPT-6.1 Sol (94.2%) and Claude Opus 5.5 (93.3%) | Scheming flagged by METR | $4 / $20 |
| Claude Opus 5 | Hardest unseen problems | 30.2% ARC-AGI-3 on the standard harness, second to GPT-6 Astra (ARC Prize) | Artificial Analysis measures a 61% hallucination rate | $5 / $25 |
| Qwen 3.7 Max | Frontier accuracy at value pricing | 92.4 GPQA Diamond, 200 free requests/day | API-only, no chat front-end | $1.25 / $3.75 promo; $2.50 / $7.50 list |
| Claude Opus 4.6 | Honesty under pressure | #1 on Scale SEAL's MASK board at 96.28; Anthropic holds the top 5 | Superseded as a flagship | Legacy Anthropic model |
The accuracy crown stays with Claude Fable 5.1, at 67% raw factual accuracy against Claude Opus 5.5's 66%, and the value pick moved. GPT-6.1 Sol now beats Gemini 3.1 Pro on every accuracy measure Artificial Analysis publishes, 62% raw accuracy against 55% and an AA-Omniscience index of 41.5 against 31.9, and ARC Prize scores it 98.5% on ARC-AGI-1 for $0.06 a task against Gemini 3.1 Pro's 98% for $0.52, so it takes the value card. Gemini 3.1 Pro stays in the table for grounded search and the Gemini app, where it needs Google AI Pro since October 9.
Gemini 4 Argon, announced September 30, brings the lowest hallucination rate Artificial Analysis has measured among leading models, 15%, but it answers only half its questions correctly, so its public release on October 13 changes nothing at the top. Two older lines are corrected as well: Claude Opus 5's hallucination rate now reads 61% rather than 50%, and it no longer leads ARC-AGI-3. In September, Opus 5.5 took the hallucination-penalised index and Humanity's Last Exam, which is why this block now splits the two Claude models rather than crowning one outright.
Best AI for Problem Solving
The best AI for hard problem solving is GPT-6 Astra, which took the reasoning boards off GPT-5.6 Sol within days of launching.
It leads LiveBench Reasoning at 92.65 and ARC-AGI-2 at 95%, the highest anyone has scored against that board's 100% human panel, and sits fourth on LiveBench Mathematics at 96.81, behind Claude Opus 5.5 at 97.08, Claude Fable 5.1 at 97.01 and GPT-6.1 Sol at 96.83. It also reports 97.6% on FrontierMath Tier 4 v2, a number worth carrying with Epoch AI's disclosure that OpenAI funded the benchmark and holds exclusive access to part of it. The catch is price and reach: $10 / $50 per 1M tokens against GPT-6.1 Sol's $2 / $10, and it needs a paid ChatGPT plan.
GPT-6.1 Sol, released September 29, is the value alternative and very nearly a co-leader: 92.63 on LiveBench Reasoning, 0.02 behind Astra, and 94.2% on ARC-AGI-2, 0.8 points behind, for $0.25 a task against Astra's $1.12. Astra keeps the crown because it still leads both boards and ARC-AGI-3, where it scores 62.7% on the standard harness against GPT-6.1 Sol's 52.7%. Gemini 4 Argon leads Arena's math category, but on only a few hundred votes, and neither LiveBench nor ARC Prize has rated it. GPT-5.6 Sol, the old value pick, is now fifth on LiveBench Reasoning and fourth on ARC-AGI-2 at 92.5%.
Qwen 3.7 Max is the budget pick for competition-style problems at 97.1 on the February 2026 HMMT index and 44.5 on Apex, with 200 free model requests a day. Claude Opus 5 remains the alternative for long agentic reasoning chains, though Astra has taken ARC-AGI-3 from it as well.
| Model | Best For | Key Benchmark | Weakness | Price |
|---|---|---|---|---|
| GPT-6 Astra | Hardest math, science and reasoning | #1 LiveBench Reasoning (92.65), #1 ARC-AGI-2 (95%), #1 ARC-AGI-3 | Needs a paid ChatGPT plan; 5x GPT-6.1 Sol's price | $10 / $50 |
| Claude Opus 5 | Long agentic reasoning chains | 1662 on AA-Briefcase v1.1 and 1724 on GDPval-AA v2.1, fourth among distinct models on both; 30.2% ARC-AGI-3 | Astra now leads ARC-AGI-3; 61% hallucination rate; now a legacy model | $5 / $25 |
| GPT-5.6 Sol | Value STEM flagship | #4 ARC-AGI-2 (92.5%); #5 LiveBench Reasoning (91.65), Mathematics 96.20 | FrontierMath still unpublished; scheming flagged by METR | $100/mo ChatGPT Pro; API $4 / $20 |
| GPT-6.1 Sol | Value pick, near-Astra reasoning | #2 LiveBench Reasoning (92.63), #2 ARC-AGI-2 (94.2%), #3 LiveBench Mathematics (96.83); Intelligence Index 51.8 at $0.72 an index task | 52.7% on ARC-AGI-3 against Astra's 62.7%; in ChatGPT Work and Codex, not in Chat | $2 / $10 |
| Qwen 3.7 Max | Competition math on a budget | 97.1 HMMT 2026 Feb, 44.5 Apex, 200 free requests/day | API-only | $1.25 / $3.75 promo; $2.50 / $7.50 list |
| Claude Fable 5 | Math inside a coding workflow | #3 on Arena's math subcategory (1522), behind Gemini 4 Argon and Claude Opus 5; 96.0 LiveBench Mathematics | Priciest option here | $10 / $50 |
| GLM 5.3 Flash | Open-weight problem solving | Intelligence Index 41.8 under MIT, almost eight points above GLM-5.2 at less than half the size; 320B/18B active, 1M context | Needs a multi-GPU server, not a workstation; GLM 5.3 scores higher on Z.ai's own figures and is downloadable since August 28, but at more than twice the size and under a bespoke licence | Open weights (MIT) |
GPT-6 Astra keeps the problem-solving crown, by less than a point. ARC Prize has now scored GPT-6.1 Sol, and it takes 94.2% on ARC-AGI-2, second to Astra's 95% and ahead of Claude Opus 5.5's 93.3%, for under a quarter of Astra's cost per task. Together with its 92.63 on LiveBench Reasoning, 0.02 behind Astra, that makes GPT-6.1 Sol a near co-leader, but Astra still leads both boards and ARC-AGI-3, so the crown does not move. GPT-5.6 Sol drops to fourth on ARC-AGI-2. Gemini 4 Argon, announced September 30, leads Arena's math category on a few hundred votes but has no LiveBench or ARC Prize score yet, and Claude Fable 5, which led that Arena category, is now third. In September, Astra took this crown from GPT-5.6 Sol after its September 3 launch, and LiveBench Mathematics passed to Claude Opus 5.5.
Best AI Agent
The best AI agent is Gemini Spark if you want the agent in the cloud and Claude Cowork if you want it on your desktop.
These are joint picks rather than a first and a second: Spark runs in a Google Cloud VM, so it keeps working while your laptop is shut, wired into Gmail, Docs and, since early September, Google Photos; Cowork runs on your Mac or Windows machine and drives your local apps and your screen. Spark is no longer the only agent that keeps working in the cloud.
SpaceXAI's Grok Bot (August 11) gives each account a persistent cloud computer that signs into your apps, from a $20/month Cursor Pro plan; Meta's Muse (September 8) runs errands from a cloud VM of its own and is free up to 100 million tokens a week; and OpenAI dots (September 29) run on GPT-6 Astra with their own cloud computer and browser, from the $100/month Pro plan, which does not include them in the EEA, UK or Switzerland. No independent board rates these products against each other, so the choice is about where the work has to happen rather than which one scores higher.
Price is no longer a tiebreaker either: Spark now reaches the $19.99/month Google AI Pro tier in the US and more than 160 other countries, and Cowork is included at no extra charge on every paid Claude plan from $20/month. ChatGPT Codex Mobile (May 14) is the alternative for coding-agent work. Read the full Gemini Spark vs Claude Cowork comparison.
| Agent | Best For | Where It Runs | Strength | Price |
|---|---|---|---|---|
| Gemini Spark | 24/7 cloud tasks, Workspace workflows | Google Cloud VM (always-on) | Always-on, deep Workspace integration | From $19.99/mo Google AI Pro |
| Claude Cowork | Desktop, app-driving, design + code | Your Mac/Windows desktop | Drives local apps, sees your screen | $20/mo Claude Pro |
| ChatGPT Codex Mobile | Coding agent on phone | OpenAI cloud + iOS/Android | Approve diffs and redirect work from phone | Included in ChatGPT plans |
| Grok Bot | Browser jobs across logged-in apps | One persistent SpaceXAI cloud computer shared by all your Bots | Signs into apps with your own logins and keeps going with your laptop closed | From $20/mo Cursor Pro, or a linked SuperGrok plan |
| OpenAI dots | Ongoing responsibilities, not one-off tasks | OpenAI cloud computer and browser | Runs on GPT-6 Astra; keeps working with your computer off; reachable in ChatGPT, Slack and by voice | From $100/mo ChatGPT Pro (not EEA/UK/CH); Business Premium |
| Meta Muse | Free personal errands | A Muse Secure VM in Meta's cloud | Free up to 100M tokens a week; a separate Sentinel agent approves what it sends out | Free; $20/mo Power, $100/mo Maximum |
Gemini Spark (cloud) and Claude Cowork (desktop) remain joint picks, because this category crowns products and no new agent product shipped since the last update. The model layer moved. Claude Sonnet 5.5 has entered Arena's Agent Arena third, behind Claude Fable 5.1, which still tops it with 17.6% confirmed success, and Claude Opus 5.5, and it has taken the lead on Artificial Analysis's AA-Briefcase v1.1 at 1823, with Opus 5.5 second at 1807. Opus 5.5 still leads GDPval-AA v2.1 at 1866, with Meta's new Muse Wonder Full second at 1857 and Sonnet 5.5 third at 1838. Gemini 4 Argon, announced September 30, leads Artificial Analysis's AutomationBench at 77.5% and has a 15.4% confirmed-success rate on the Agent Arena, above Opus 5.5's 14.1%, but sits tenth there overall and since October 13 it is on the paid API and in the Gemini app on Google AI Pro.
Among open models on the Agent Arena, Kimi K3 is now the highest at fourteenth, ahead of DeepSeek V4.1-Flash at seventeenth and Tencent's Hy4 Preview at nineteenth. In September, Grok Bot, Meta's Muse and OpenAI dots joined Gemini Spark as always-on cloud agents, and Spark reached the $19.99/month Google AI Pro tier.
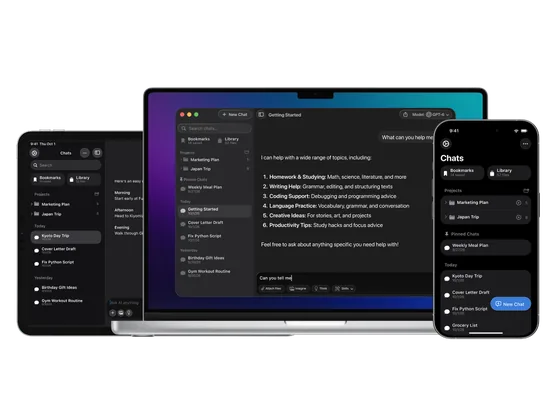
Press ⌥ Space on your Mac, ask, and keep working. Also on iPhone and iPad.
Free to start, 4.7★ across 27,000+ reviews.
Download Fello AIBest AI for Students
The best AI for students is GPT-6 Luna inside ChatGPT for general coursework and Gemini 3.6 Flash for STEM and multimodal study, with Qwen 3.7 Max as the API alternative for harder problem sets (200 free requests a day) and Claude Sonnet 5.5 as the free alternative for essay editing.
Most students don't need to pay. Since October 8, ChatGPT Free and Go have been moving from GPT-5.6 Luna to GPT-6 Luna, which Artificial Analysis scores 38.1 on its index against 37.3; the free plan has unlimited text chats, while file uploads and image tools stay capped. Claude Sonnet 5.5 is free on claude.ai, where free accounts can also pick Claude Haiku 5.5 (October 7), the Claude model that uses the least of your usage limit.
Gemini changed on October 9: the free Gemini app now runs on Auto, which sends most prompts to Flash-Lite, so choosing Gemini 3.6 Flash yourself needs Google AI Plus, though it stays free in Google AI Studio. For step-by-step working on the hardest math, GPT-6 Astra reports 97.6% on FrontierMath Tier 4 v2 but is not on ChatGPT's free tier; Qwen 3.7 Max is the value alternative at 97.1 HMMT 2026 February with API pricing at $1.25 / $3.75 on its current 50% promo ($2.50 / $7.50 list).
| Task | Best Model | Why | Free? | Alternative |
|---|---|---|---|---|
| Essays & coursework | GPT-6 Luna | ChatGPT's Free and Go model, rolling out since October 8; unlimited text chats | Yes | Claude Sonnet 5.5 (free Claude) |
| STEM problem-solving | GPT-6 Sol / Qwen 3.7 Max | ChatGPT's paid default; Astra reports 97.6% FrontierMath Tier 4 v2 / 97.1 HMMT 2026 Feb | Plus paid / Qwen API paid | Gemini 3.6 Flash (AI Plus since Oct 9) |
| Research & accuracy | Gemini 3.1 Pro | 98% ARC-AGI-1 at $0.52/task, native Google Search grounding | AI Pro (Gemini app) since Oct 9 | Claude Opus 5 |
| Writing editing | Claude Sonnet 5.5 | Free on claude.ai since September 28 and second only to Opus 5.5 on the Intelligence Index; Claude Fable 5.1 is the quality leader | Yes (Claude free) | Claude Fable 5.1 |
| Multimodal study (PDFs, slides, images) | Gemini 3.6 Flash | 1M context via AI Studio; Gemini app needs AI Plus since Oct 9 | Free in AI Studio | NotebookLM (Google) |
Two changes for students. ChatGPT's free model is moving from GPT-5.6 Luna to GPT-6 Luna, rolling out to Free and Go since October 8, so GPT-6 Luna takes the essays row. And since October 9 the free Gemini app runs on Auto, which sends most prompts to Flash-Lite, so picking Gemini 3.6 Flash in the app needs Google AI Plus.
Anthropic also released Claude Haiku 5.5 on October 7, which free Claude accounts can pick, and Claude Sonnet 5.5 is still free on claude.ai. Gemini 4 Argon, public since October 13, comes with Google AI Pro, so US students on Google's free year of AI Pro get it, while the free plan and the Google AI Plus student offer elsewhere do not. In September, Claude Sonnet 5.5 replaced Sonnet 5 as the free writing and editing pick.
Best AI for Work & Professionals
The best AI for professional work is GPT-6 (ChatGPT's default since October 7, Sol on paid plans) for daily knowledge work, Claude Opus 5.5 for coding and high-stakes writing, and Gemini Spark for 24/7 agentic workflows.
Most professionals get the most out of running two paid subscriptions (ChatGPT Plus at $20/month plus Claude Pro at $20/month, total $40/month). Or keep one bill: Fello AI covers ChatGPT, Claude and Gemini for everyday work. For agentic work that runs while you sleep, Gemini Spark is the always-on cloud agent that lives inside Google Workspace, and since July 30 it reaches the $19.99/month Google AI Pro tier as well as Google AI Ultra; OpenAI dots, Grok Bot and Meta's Muse are the alternatives, covered in the agents section above.
| Use Case | Best Model | Key Stat | Price | Alternative |
|---|---|---|---|---|
| Daily knowledge work | GPT-6 | ChatGPT's default since October 7; GPT-6 Sol on Plus | $20/mo ChatGPT Plus | Claude Opus 5.5 |
| Legal, finance & tax research | Gemini 4 Argon | #1 Vals Index (68.9%) and #1 AutomationBench-AA (77.5%) | $19.99/mo Google AI Pro | Claude Opus 5.5 |
| ChatGPT Work & Codex | GPT-6.1 Sol | In ChatGPT Work and Codex for Plus, Pro, Business, Enterprise and Edu since September 29, at $2 / $10 in the API | $20/mo ChatGPT Plus | GPT-6 Luna for volume work |
| Coding (proprietary) | Claude Opus 5.5 | #1 Arena WebDev (1813) and #1 Intelligence Index (57.6), at $4 / $20 | $20/mo Claude Pro | Claude Sonnet 5.5, which leads Terminal-Bench 4.0 at half the token price |
| Coding (cost-effective) | Claude Sonnet 5.5 | #1 Terminal-Bench 4.0 (63.6%) and #1 LiveBench Coding (91.4); $0.88 an index task at high effort | $2 / $10 | Qwen3.8-Max-0902; DeepSeek V4.1-Flash |
| Research & briefings | Gemini 3.1 Pro | 98% ARC-AGI-1 at $0.52/task, Google grounding | Google AI Pro / Ultra | Claude Opus 5.5 |
| Hard math, physics, finance modelling | GPT-6 Astra | #1 LiveBench Reasoning and ARC-AGI-2 (95%); reports 97.6% FrontierMath Tier 4 v2 | $100/mo ChatGPT Pro | GPT-6.1 Sol; Qwen 3.7 Max |
| Always-on agent workflows | Gemini Spark | Always-on cloud agent inside Google Workspace | From $19.99/mo Google AI Pro | Claude Cowork |
| Live news, X-context creative | Grok 4.7 | Intelligence Index 46.3 + native X grounding; in the Grok app since October 3 | $30/mo SuperGrok | Gemini 3.1 Pro |
| All-in-one consolidation | Fello AI | ChatGPT + Claude + Gemini + Grok + DeepSeek | From $11.99/mo | Pay each vendor separately |
The daily knowledge work row moves from GPT-5.6 to GPT-6, which became ChatGPT's default on October 7. Gemini 4 Argon takes a new legal, finance and tax row: it leads the Vals Index of that work and Artificial Analysis's AutomationBench, and since October 13 it is in the Gemini app on Google AI Pro at $19.99/month. In September, Claude Opus 5.5 took the proprietary coding row at a lower price than Opus 5, Claude Sonnet 5.5 took the cost-effective coding row, and GPT-6.1 Sol took the ChatGPT Work and Codex row on September 29.
AI Model Pricing in October 2026
From $0 free tiers to $199.99/month Google AI Ultra. The price that matters most on this table is Claude Opus 5.5 at $4 / $20. Since September 22 the highest-scoring model any independent evaluator has measured costs less than the Claude Opus 5 it replaced ($5 / $25), and cache reads fall 60% to $0.20. Claude Fable 5.1 and GPT-6 Astra both list at $10 / $50 and both score below it.
The busiest rate is now $2 / $10, shared by Claude Sonnet 5.5, GPT-6 Sol and GPT-6.1 Sol. GPT-6.1 Sol is the cheapest route to a top-six Intelligence Index score, at $0.72 an index task. With Sonnet 5.5 the effort setting decides the bill: an index task costs $0.88 at high effort and $5.46 at max, now just under Opus 5.5's $5.98, and Anthropic halved its cache reads to $0.10 on October 7. Google's Gemini 4 Argon also starts at an introductory $2 / $10 ($4 / $20 standard), until November 30, and since October 13 anyone on the paid API can buy it.
Token price and task cost can drift apart. Grok 4.7 lists at $2 / $6, the same as Grok 4.6, yet an index task costs $2.73 against $1.86, because 4.7 writes roughly twice the output. Mistral Large 4 (public preview since October 6) lists at $1.36 / $4.18, though Mistral's own model page shows half that, and it is verbose enough that an index task costs $1.13 for a score of 38.4. At the frontier the value pick is Meta's Muse Spark 1.3 at $1.25 / $4.25, or $1.60 an index task for 48.1.
At the cheap end, GPT-6 Luna is the cheapest model per task on this page: $0.10 / $0.50, or $0.07 an index task. Claude Haiku 5.5 (October 7) matches that token price on prompts up to 100,000 tokens and scores 43.4 to Luna's 38.1, but it writes so much more that an index task costs $0.21 at max effort, or $0.12 for 41.3 at xhigh; above 100,000 tokens it rises to $0.50 / $2.50. Among open models sold by the token, GLM 5.3 Flash stays the pick at $0.15 / $0.50 ($0.25 an index task for 41.8), ahead of DeepSeek V4.1-Flash at $0.15 / $0.60 off-peak and $0.30 / $1.20 at peak ($0.27 for 39.5). Xiaomi's MiMo-V2.6-Pro is cheaper still at $0.13 an index task for 46.3, but only if you host its 1.02 trillion parameters yourself. For a deeper breakdown see our full AI Pricing Comparison Guide.
| Model | Input (per 1M) | Output (per 1M) | Context | Free Access? |
|---|---|---|---|---|
| GPT-6 Astra | $10.00 | $50.00 | 1,050,000 (922,000 max input) | In Chat on Pro, Business and Enterprise since September 4; Plus gets it in ChatGPT Work and Codex rather than Chat; no free tier; live in the API |
| GPT-6 Sol | $2.00 | $10.00 | 1,050,000 (922,000 max input) | ChatGPT Chat on Plus, Pro, Business and Enterprise since October 7; Work & Codex; API |
| GPT-6.1 Sol | $2.00 | $10.00 | 1,050,000 (922,000 max input) | ChatGPT Work & Codex on Plus, Pro, Business, Enterprise and Edu since September 29; API; not in Chat; cache reads $0.10 |
| GPT-6 Luna | $0.10 | $0.50 | 1,050,000 (922,000 max input) | ChatGPT Chat on Free and Go, rolling out since October 8; Work & Codex on paid plans; API |
| GPT-5.5 | $5.00 | $30.00 | 1M (400K in Codex) | ChatGPT Free; API paid |
| GPT-5.5 Pro | $30.00 | $180.00 | 1M | ChatGPT Pro from $100/mo ($200 and $500 higher-usage tiers) |
| GPT-5.6 Sol | $4.00 | $20.00 | Not published | Live in ChatGPT, Codex & API (July 9); promotional rate through at least November 21, 2026 |
| GPT-5.6 Terra | $2.00 | $12.00 | Not published | Live in ChatGPT, Codex & API (July 9) |
| GPT-5.6 Luna | $0.20 | $1.20 | Not published | Live in ChatGPT, Codex & API (July 9) |
| Claude Opus 5.5 | $4.00 | $20.00 | 1M | Claude Pro/Max/Team; API paid; cache reads $0.20 |
| Claude Opus 5 | $5.00 | $25.00 | 1M | Legacy model at Anthropic; Pro/Max/API |
| Claude Opus 4.8 | $5.00 | $25.00 | 1M | Legacy model at Anthropic; Pro/Max/API |
| Claude Fable 5.1 | $10.00 | $50.00 | 1M | Cache reads $0.25; in Max/Team Premium (~50% of usage limits); Pro/Team Standard via credits. Mythos 5.1 bills identically, by invitation only |
| Claude Fable 5 | $10.00 | $50.00 | 1M | Permanent in Max/Team Premium (~50% of usage limits); Pro/Team Standard via credits |
| Claude Sonnet 5.5 | $2.00 | $10.00 | 1M | Free on claude.ai; Pro/Max/Team; API paid; cache reads $0.10 since October 7 |
| Claude Sonnet 5 | $2.00 | $10.00 | 1M | Legacy model since September 28; the fallback for flagged cyber requests; API paid |
| Claude Sonnet 4.6 | $3.00 | $15.00 | 1M | API paid (superseded by Sonnet 5) |
| Claude Haiku 5.5 | $0.10 (≤100K) / $0.50 (>100K) | $0.50 (≤100K) / $2.50 (>100K) | 1M | Free, Pro, Max, Team and Enterprise on Claude.ai (web, iOS, Android); API paid; cache reads $0.01 |
| Gemini 3.1 Pro | $2.00 (≤200K) / $4.00 (>200K) | $12.00 (≤200K) / $18.00 (>200K) | 1M | Gemini app on Google AI Pro and above since Oct 9; API paid |
| Gemini 4 Argon | $2.00 intro to Nov 30 / $4.00 standard ($0.10 cached, intro) | $10.00 intro / $20.00 standard | 1M, shared by input and output | Paid API since October 13; Gemini app on Google AI Pro and Ultra |
| Gemini 3.8 Flash | $0.75 intro / $1.50 from Jan 1, 2027 | $3.75 intro / $7.50 from Jan 1, 2027 | 1M | AI Studio, Antigravity, Gemini Enterprise + paid API; in the Gemini app reported for AI Pro/Ultra |
| Gemini 3.7 Flash | $0.75 intro / $1.50 from Jan 1, 2027 | $3.75 intro / $7.50 from Jan 1, 2027 | 1M | AI Studio, Android Studio, Antigravity + paid API; in the Gemini app via Spark only (AI Pro/Ultra, excludes EEA/UK/CH/Nigeria) |
| Gemini 3.6 Flash | $0.75 intro / $1.50 from Jan 1, 2027 | $3.75 intro / $7.50 from Jan 1, 2027 | 1M | Gemini app on AI Plus and above since Oct 9; AI Studio; free API tier + paid API |
| Gemini 3.5 Flash-Lite | $0.30 | $2.50 | 1M | AI Studio; free API tier + paid API |
| Qwen3.8-Max-0902 | $2.00 ($0.17 explicit cache hit, $0.25 implicit) | $6.00 | 1M (128K output) | QwenCloud API only; no consumer chat front-end; open weights only as the text-only Qwen3.8-2.4T-A95B it is built on |
| Qwen 3.7 Max | $1.25 promo / $2.50 list | $3.75 promo / $7.50 list | 1M | 200 free requests/day; API paid beyond that |
| MiniMax M3 | $0.30 (50% off $0.60) | $1.20 (≤512K) | 1M | Open weights; hosting costs apply |
| LongCat-2.0 | Provider-dependent | Provider-dependent | 1M | Open weights (MIT); hosting costs apply |
| NVIDIA Nemotron 3 Ultra | Provider-dependent | Provider-dependent | 1M | Open weights (OpenMDW); hosting costs apply |
| Qwen 3.5 (open-weight) | Self-host / Together | Self-host / Together | 1M | Open weights; hosting costs apply |
| Nex-N2-Pro | Self-host / providers | Self-host / providers | 1M | Open weights (Apache 2.0); hosting costs apply |
| Rio 3.5 Open 397B | Self-host / providers | Self-host / providers | 1M | Open weights (MIT); hosting costs apply |
| Grok 4.3 | $1.25 | $2.50 | 1M | Free consumer plan; API paid |
| Grok 4.6 | $2.00 (<200K) / $4.00 (≥200K) | $6.00 (<200K) / $12.00 (≥200K) | 500K | SpaceXAI API, Cursor, Grok Build, OpenRouter, Vercel, Cloudflare |
| Grok 4.7 | $2.00 (<200K) / $4.00 (≥200K) | $6.00 (<200K) / $12.00 (≥200K) | 500K | SpaceXAI API, Cursor, Grok Build, harnesses and cloud routers; not in the Grok app |
| Muse Spark 1.3 | $1.25 ($0.10 Contributor tier) | $4.25 ($0.20 Contributor tier) | 1M | Paid API; Muse Code, Meta Model API and OpenRouter; Contributor tier trades training rights for a ~92% discount |
| Muse Wonder | $4.00 | $20.00 | 1M | Paid API; Meta Model API, Muse Code and OpenRouter; Muse Wonder Full is only in Muse Code, on the $50 and $200 plans |
| Kimi K3 | $3.00 ($0.30 cache-hit) | $15.00 | 1M | Free basic tier in the Kimi app; open weights on Hugging Face (Kimi K3 License) |
| Mistral Large 4 | $1.36 ($0.68 on Mistral's model page) | $4.18 ($2.09) | 512K (1M per Mistral) | Public preview API since October 6; open weights promised by the end of October, no licence named yet |
| Gemini Omni Flash (video) | $1.50 | $17.50 (video output) | 10-second clips | Gemini app / Flow; AI Studio + API |
| DeepSeek V4-Pro | $0.66 off-peak / $1.32 peak ($0.022 cache-hit off-peak) | $1.98 off-peak / $3.96 peak | 1M | DeepSeek Chat free; API paid, peak/off-peak tiers since August 16 |
| DeepSeek V4.1-Flash | $0.15 off-peak / $0.30 peak ($0.003 cache-hit off-peak) | $0.60 off-peak / $1.20 peak | 1M | DeepSeek Chat free; API paid, peak/off-peak tiers; replaced V4-Flash on September 10 |
| Kimi K2.7 Code | Provider-dependent | Provider-dependent | 256K | Open weights; hosting costs apply |
| GLM-5.2 | Provider-dependent | Provider-dependent | 1M | Open weights; hosting costs apply |
| GLM 5.3 | $1.40 ($0.26 cache-hit) | $4.40 | 1M | Z.ai API, GLM Coding Plan and ZCode; weights on Hugging Face since August 28 under the bespoke GLM 5.3 License |
| GLM 5.3 Flash | $0.15 ($0.03 cache-hit) | $0.50 | 1M | Z.ai API, GLM Coding Plan, OpenRouter; MIT weights on Hugging Face; the launch promotion ended September 9 |
| Tencent Hy4 Preview | $0.834 ($0.042 cache-hit) | $2.501 | 1M+ | Open weights (Apache 2.0); Tencent Cloud TokenHub, OpenRouter, WorkBuddy, CodeBuddy |
| Qwen3.8-Flash-Next | Provider-dependent | Provider-dependent | 262K (to 1M) | Open weights (Qwen Community License 1.0); hosting costs apply |
| MiMo-V2.6-Pro | $0.435 | $0.87 | 1M | Open weights (MIT); hosting costs apply |
| ERNIE 5.1 | China-region pricing | China-region pricing | 256K | Baidu free tier |
| Gemini Spark (agent) | Not API-priced | Not API-priced | 1M (Gemini base) | Google AI Pro $19.99, AI Ultra $99.99 or $199.99/mo |
| Fello AI (aggregator) | Routed via app | Routed via app | Model-dependent | From $11.99/mo, free tier available |
The GPT-5.5 and GPT-5.5 Pro rates above are short-context prices; OpenAI no longer publishes the specific long-context figures. The GPT-5.6 tiers are billed at 2x input and 1.5x output once a prompt passes 272K input tokens, which puts long-context Terra at $4 / $18 and Luna at $0.40 / $1.80. The GPT-6 tiers carry the same surcharge past 272K input tokens, applied to the whole request, and their cached input reads are 90% off: $1.00 for Astra, $0.20 for GPT-6 Sol and $0.01 for Luna, with GPT-6.1 Sol at 95% off, $0.10.
Grok 4.6 works the same way but bites harder: at 200,000 prompt tokens and above, SpaceXAI re-bills the entire request at the higher rate rather than only the overage, so crossing the line by a thousand tokens doubles the cost of the whole call. DeepSeek is the other rate card that needs reading twice: since August 16 both V4 models bill at peak rates from 01:00 to 04:00 and from 06:00 to 10:00 UTC on weekdays, and at exactly half that in every other hour, so the same job can cost twice as much depending on when you run it.
The cheapest way through this table is often one subscription instead of three. Fello AI puts GPT, Claude, Gemini, Grok, Perplexity and more in a single app for Mac, iPhone and iPad, from $11.99 a month in most countries.
Best Open-Weight Models in October 2026
The best open-weight model in October 2026 is Xiaomi's MiMo-V2.6-Pro, published on September 21 under plain MIT: 1.02 trillion parameters with 42 billion active and a 1M-token context. Artificial Analysis scores it 46.3 on Intelligence Index v4.3.2, the highest open score it has ever published, ahead of GLM-5.3 at 44.8 and Kimi K3 at 43.6, at just $0.13 an index task. The catch: Arena's human voters rank it only 19th on WebDev and 26th on text.
Two other open models still lead somewhere. Kimi K3 is the highest-placed open model on Arena, 14th on WebDev and 14th on the Agent Arena. GLM-5.3 is the strongest open model on Terminal-Bench 4.0 at 41.9%, though on a bespoke Z.ai licence rather than MIT.
For teams running their own weights, the practical pick is still GLM 5.3 Flash (Z.ai, MIT): 41.8 on v4.3.2 from 320B total and 18B active. It is a separate model on a newly trained base, not a trimmed GLM 5.3, which is why it ships under MIT. A 1.02-trillion-parameter model is not a workstation proposition, and the K3 download alone is about 1.56 TB. For the cheapest tier, DeepSeek-V4.1-Flash replaced V4-Flash on September 10: MIT, natively multimodal, 39.5 on v4.3.2 and $0.15 / $0.60 off-peak.
Three more are worth watching. Mistral Large 4 (public preview since October 6) is the highest-scoring model from the US or Europe that promises open weights, at 38.4, but you cannot download it yet: Mistral says the weights follow by the end of October and has not named a licence. Alibaba's Qwen3.8-Flash-Next, 125B with only 6B active, previews the Qwen4 architecture and scores 39.8. Tencent's Hy4 Preview, 770B total and 49B active under Apache 2.0, has no Artificial Analysis rating but sits 18th on Arena WebDev.
| Model | Best For | Key Benchmark | Context / License | Where To Run |
|---|---|---|---|---|
| MiMo-V2.6-Pro | Highest open Intelligence Index ever measured | II 46.3 (v4.3.2), above GLM-5.3 and Kimi K3, at $0.13 an index task; 34.8% Terminal-Bench 4.0; GDPval-AA v2.1 1685; 1.02T/42B active | 1M / MIT | Hugging Face (XiaomiMiMo), providers, self-host |
| Kimi K3 | Highest-placed open model on Arena | II 43.6 (v4.3.2); #14 Arena WebDev, the best open placement there; #14 Agent Arena; 2.8T/104B active | 1M / Kimi K3 License | Hugging Face (96 shards, 1.56 TB), Moonshot API, providers |
| GLM 5.3 Flash | Best open model most teams can actually run | II 41.8 (v4.3.2), on the intelligence-versus-cost Pareto frontier at about $0.25 an index task; 320B/18B active, natively multimodal | 1M / MIT | Hugging Face, Z.ai API ($0.15/$0.50), OpenRouter |
| GLM-5.2 | Fallback with an independent track record | II 33.7 (v4.3.2); #27 Arena WebDev (1,603.2), #20 Agent Arena; 744B/40B active | 1M / MIT | Z.ai, Hugging Face, OpenRouter |
| GLM 5.3 | Open since August 28, but on a bespoke licence | II 44.8 (v4.3.2), the second-highest open score we found; same 744B base as GLM-5.2, post-trained only, published checkpoint counted at 753B; CyberGym 84.5% and Terminal-Bench 3.0 28.3 (vendor figures) | 1M / GLM 5.3 License (MaaS above $10B revenue needs a Z.ai security review) | Hugging Face, Z.ai API ($1.40/$4.40), GLM Coding Plan, ZCode |
| DeepSeek V4.1-Flash | Best open value if you host it yourself | II 39.5 (v4.3.2) against 34.3 for the V4-Flash 0731 build it replaces; 552B, 8B active at prefill and 16B at decode | 1M / MIT | DeepSeek API ($0.15/$0.60 off-peak, $0.30/$1.20 peak since September 10), local |
| Tencent Hy4 Preview | Largest permissively licensed model yet | 770B/49B active; 2.99/4.00 on Tencent's own 203-task expert panel vs Kimi K3 2.94 and GLM 5.3 2.92 (vendor); no Artificial Analysis rating; #18 Arena WebDev (1632), #19 Agent Arena | 1M+ / Apache 2.0 | Hugging Face (BF16 and FP8), Tencent Cloud TokenHub, OpenRouter |
| Qwen3.8-Flash-Next | Preview of the Qwen4 architecture | 125B total plus a 51B N-gram embedding, 6B active; 91.7 GPQA Diamond and 62.5 SWE-Bench Pro (vendor); II 39.8 (v4.3.2); #17 Arena WebDev (1633) | 262K to 1M / Qwen Community License 1.0 | Hugging Face, providers, self-host |
| LongCat-2.0 | Frontier open coder trained on Chinese chips | II 33 (v4.1); 59.5% SWE-Bench Pro (vendor), 1.6T/~48B active | 1M / MIT | Hugging Face, GitHub, OpenRouter |
| MiniMax M3 | Cheap long-context multimodal | II 29.2 (v4.3.2; 44 on v4.1), 59% SWE-Bench Pro, multimodal | 1M / MiniMax Community License | Hugging Face, API $0.30/1M (50% off) |
| Nex-N2-Pro | Strongest open coding score | II 41 (v4.1); 80.8 SWE-Bench Verified, 397B/17B active | Qwen-based / Apache 2.0 | Hugging Face, providers, self-host |
| Kimi K2.7 Code | Strongest commercially-licensed open coder | +21.8% on Kimi Code Bench v2 vs K2.6 (vendor); 1T/32B active | 256K / Modified MIT | Hugging Face, DeepInfra, providers |
| DeepSeek V4-Pro | Agentic real-world work | II 44 (v4.1), 1.6T/49B active | 1M / MIT | DeepSeek API ($0.66/$1.98 off-peak, $1.32/$3.96 peak since August 16), local |
| Hy3 | Newest permissive-licence entrant | II 41 (v4.1); #56 on Arena WebDev (1,508.4) | Apache 2.0 | Hugging Face, providers, self-host |
| Inkling | Thinking Machines' first open model | II 41 (v4.1), agentic 32.3, released July 15 | Open weights | Hugging Face, providers, self-host |
| Inkling Small | Same family at a quarter the size | II 40 (v4.1), agentic 30.8; 276B/12B active, text, image and audio in | Apache 2.0 | Hugging Face (BF16 and NVFP4), providers, self-host |
| NVIDIA Nemotron 3 Ultra | NVIDIA-tuned, fully permissive license | II 38 (v4.1), 65-70.4 SWE-Bench Verified, 550B/55B active | 1M / OpenMDW | OpenRouter, Hugging Face, AWS (8x B200 self-host) |
| Qwen 3.5 (397B / 17B active) | Multimodal, fast decode | 88.4 GPQA, 91.3 AIME 2026, 83.6 LiveCodeBench v6 | 1M / open | Together, OpenRouter, local |
| Qwen3.6-35B-A3B | Efficient open agentic coder (3B active) | 86.0 GPQA Diamond, 92.7 AIME 2026, 35B/3B active | 262K (to 1M YaRN) / Apache 2.0 | Hugging Face, OpenRouter, local |
| Qwen3.6-27B | Laptop-runnable dense coder | 87.8 GPQA Diamond, dense 27B, multimodal | 256K / Apache 2.0 | Local Mac/PC, Hugging Face, OpenRouter |
| Rio 3.5 Open 397B | Qwen 3.5 fine-tune, multilingual reasoning | 70.8 Terminal-Bench 2.1 (first-party), beats Qwen 3.7 Plus on 4/5 | 397B/17B active / MIT | Hugging Face, providers, self-host |
| Llama 4 Maverick | Meta-line flagship | 17B active / 400B total params | Llama 4 license | Meta cloud, Hugging Face, local |
| NVIDIA Nemotron 3 Nano Omni | Edge / low-power | Multimodal, very small footprint | Compact / open | Local, NVIDIA tool |
Licensing matters as much as raw score here, and August widened the gap between the two groups. Kimi K2.7 (Modified MIT), DeepSeek V4 (MIT), GLM 5.3 Flash (MIT), MiMo-V2.6-Pro (MIT), GLM-5.2 (MIT), LongCat-2.0 (MIT), Hy3 (Apache 2.0), Hy4 Preview (Apache 2.0), Nex-N2-Pro (Apache 2.0) and Nemotron 3 Ultra (OpenMDW) all clearly allow commercial use with no revenue test.
The rest carry conditions worth reading before you build on them: MiniMax M3 and MiniMax H3 ship under their own community licences, H3 additionally requiring an application from the US, EU, UK and South Korea; Kimi K3 sits on a custom licence with a revenue threshold for anyone reselling it as a service; GLM 5.3 requires a Z.ai security review of any model-as-a-service operator above $10 billion in revenue; and the Qwen Community License 1.0 on Qwen3.8-Flash-Next requires a separate licence from Qwen to run a model-as-a-service or an AI work-assistant business, though internal use is exempt. No open model is first on any Arena board we track any more: Claude Opus 5 took the Agent board in July, the last one an open model led.
Benchmarks, Prices, and Hands-On Use
Every ranking on this page combines three inputs: public benchmarks from seven independent houses (Artificial Analysis, Arena formerly LMArena, Scale SEAL, LiveBench, EQ-Bench, ARC Prize and the official Terminal-Bench 4.0 board, covering the Intelligence Index, GPQA Diamond, ARC-AGI-1 through 3, Humanity's Last Exam, GDPval-AA, FrontierMath, HMMT, MCP Atlas, SWE Atlas and the Remote Labor Index), published API and subscription pricing from each vendor's official pricing page, and hands-on use by the FelloAI editorial team running real prompts across the same task on every model. We re-fetch official pricing and benchmark sources before every monthly update.
Benchmarks are weighted to the use case: SWE-bench and Terminal-Bench drive coding, GPQA Diamond and ARC-AGI-2 drive accuracy, GDPval-AA (Artificial Analysis's professional-deliverables benchmark) informs professional-task quality while writing style is judged primarily by hands-on testing, FrontierMath and HMMT drive problem-solving. We disclose when a benchmark is vendor-reported but not independently verified, and we strip any claim we cannot reproduce against a live source. We rank on measured scores: a category crown moves as soon as a model out-scores the holder on the boards that define that category, without waiting for the vote-based boards to catch up, and a model that is not yet widely available is flagged on its card rather than denied one. We re-check ranks as well as figures, because a score can stay correct while the board around it moves. When a model goes through a major upgrade between updates, we re-rank the category and add a "What changed this month" line at the bottom of the deep-dive.
Ask ChatGPT, Claude and Gemini and keep the best answer. No three bills.
Fello AI runs on Mac, iPhone and iPad, free to start.
Download Fello AI